
Study Guides
IB DP Mathematics: Analysis and Approaches – Sampling, data presentation, summary statistics and regression Study Guide
Study guide to sampling, data displays, summary statistics, correlation and regression lines for IB DP Maths AA SL and HL, with worked examples.
- Level
- IB
- Topic
- Sampling, data presentation, summary statistics and regression
- Author
- Marlbridge Academic Team
- Updated
- Reviewed by
- Muhammad Ghazali Siddiqui (what this means)
Aligned to International Baccalaureate IB Diploma Programme Mathematics: Analysis and Approaches (DP Mathematics: Analysis and Approaches), First assessment 2021. Official subject brief .
Syllabus page (what it covers and how it is assessed): IB Diploma Programme Mathematics: Analysis and Approaches.
Syllabus points this page covers
DP Mathematics: Analysis and Approaches
- 4.1 Concepts of population, sample, sampling techniques and outliers
- 4.2 Presentation of data: frequency distributions, histograms and box-and-whisker diagrams
- 4.3 Measures of central tendency and measures of dispersion
- 4.4 Linear correlation of bivariate data and the regression line of y on x
- 4.10 The regression line of x on y
Found an error? Report a correction.
Need help with this topic? Request a free trial class for IB Diploma Programme Mathematics: Analysis and Approaches (DP Mathematics: Analysis and Approaches).
This study guide teaches the descriptive statistics unit of IB Diploma Programme Mathematics: Analysis and Approaches from scratch. It is aligned to the IB Mathematics: analysis and approaches guide, first assessment 2021, and covers syllabus sections 4.1–4.4 and 4.10. All of this content is common to SL and HL. It follows the IB guide for first assessment 2021, which remains the examined syllabus until the new course is first assessed in May 2029, so it applies to the May and November 2026, 2027 and 2028 SL and HL sessions.
When you have worked through it, use the statistics revision notes for final-weeks recall and the statistics practice questions to test yourself. For the whole course, see the IB DP Maths AA course hub and the printable syllabus checklist.
What this unit covers
| Syllabus section | What you must be able to do | SL/HL |
|---|---|---|
| 4.1 | Use the terms population, sample, random sample, discrete and continuous data; judge reliability and bias; identify and interpret outliers; describe simple random, convenience, systematic, quota and stratified sampling | SL and HL |
| 4.2 | Read and draw frequency tables, frequency histograms (equal class intervals), cumulative frequency graphs and box and whisker diagrams; use them to find the median, quartiles, percentiles, range and IQR | SL and HL |
| 4.3 | Find the mean, median and mode; estimate the mean of grouped data; state the modal class; find the IQR, standard deviation and variance; know the effect of constant changes to the data | SL and HL |
| 4.4 | Draw and describe scatter diagrams; find and interpret Pearson’s r; find the regression line of y on x and use it to predict; interpret a and b in y = ax + b | SL and HL |
| 4.10 | Find the regression line of x on y and use it to predict x from y | SL and HL |
Most calculations in this topic are done with technology, and the data set is treated as the population unless you are told otherwise. Paper 1 allows no technology, so be ready to do these by hand: sampling calculations, quartiles of short lists, outlier checks, mid-interval means, constant-change rules and using a given regression line.
4.1 Populations, samples and sampling
The population is every item of interest; a sample is the part you measure. In a random sample every item has an equal chance of selection.
- Discrete data can take only separate values, usually counts: number of siblings, goals scored.
- Continuous data can take any value in a range, usually measurements: time, mass, length.
Reliability and bias. Ask who collected the data and why. A sample is biased if some members of the population are more likely to be chosen than others. Also check for missing data and recording errors (a height typed as 1.7 instead of 170).
Sampling techniques
| Method | How it works | Main weakness |
|---|---|---|
| Simple random | Number the population and choose with random numbers | Needs a full list; may miss small groups by chance |
| Convenience | Use whoever is easiest to reach | Very likely to be biased |
| Systematic | Choose every kth item from a list, random start | Biased if the list has a repeating pattern |
| Quota | Fill a fixed number from each group, not chosen at random | The interviewer chooses, so bias creeps in |
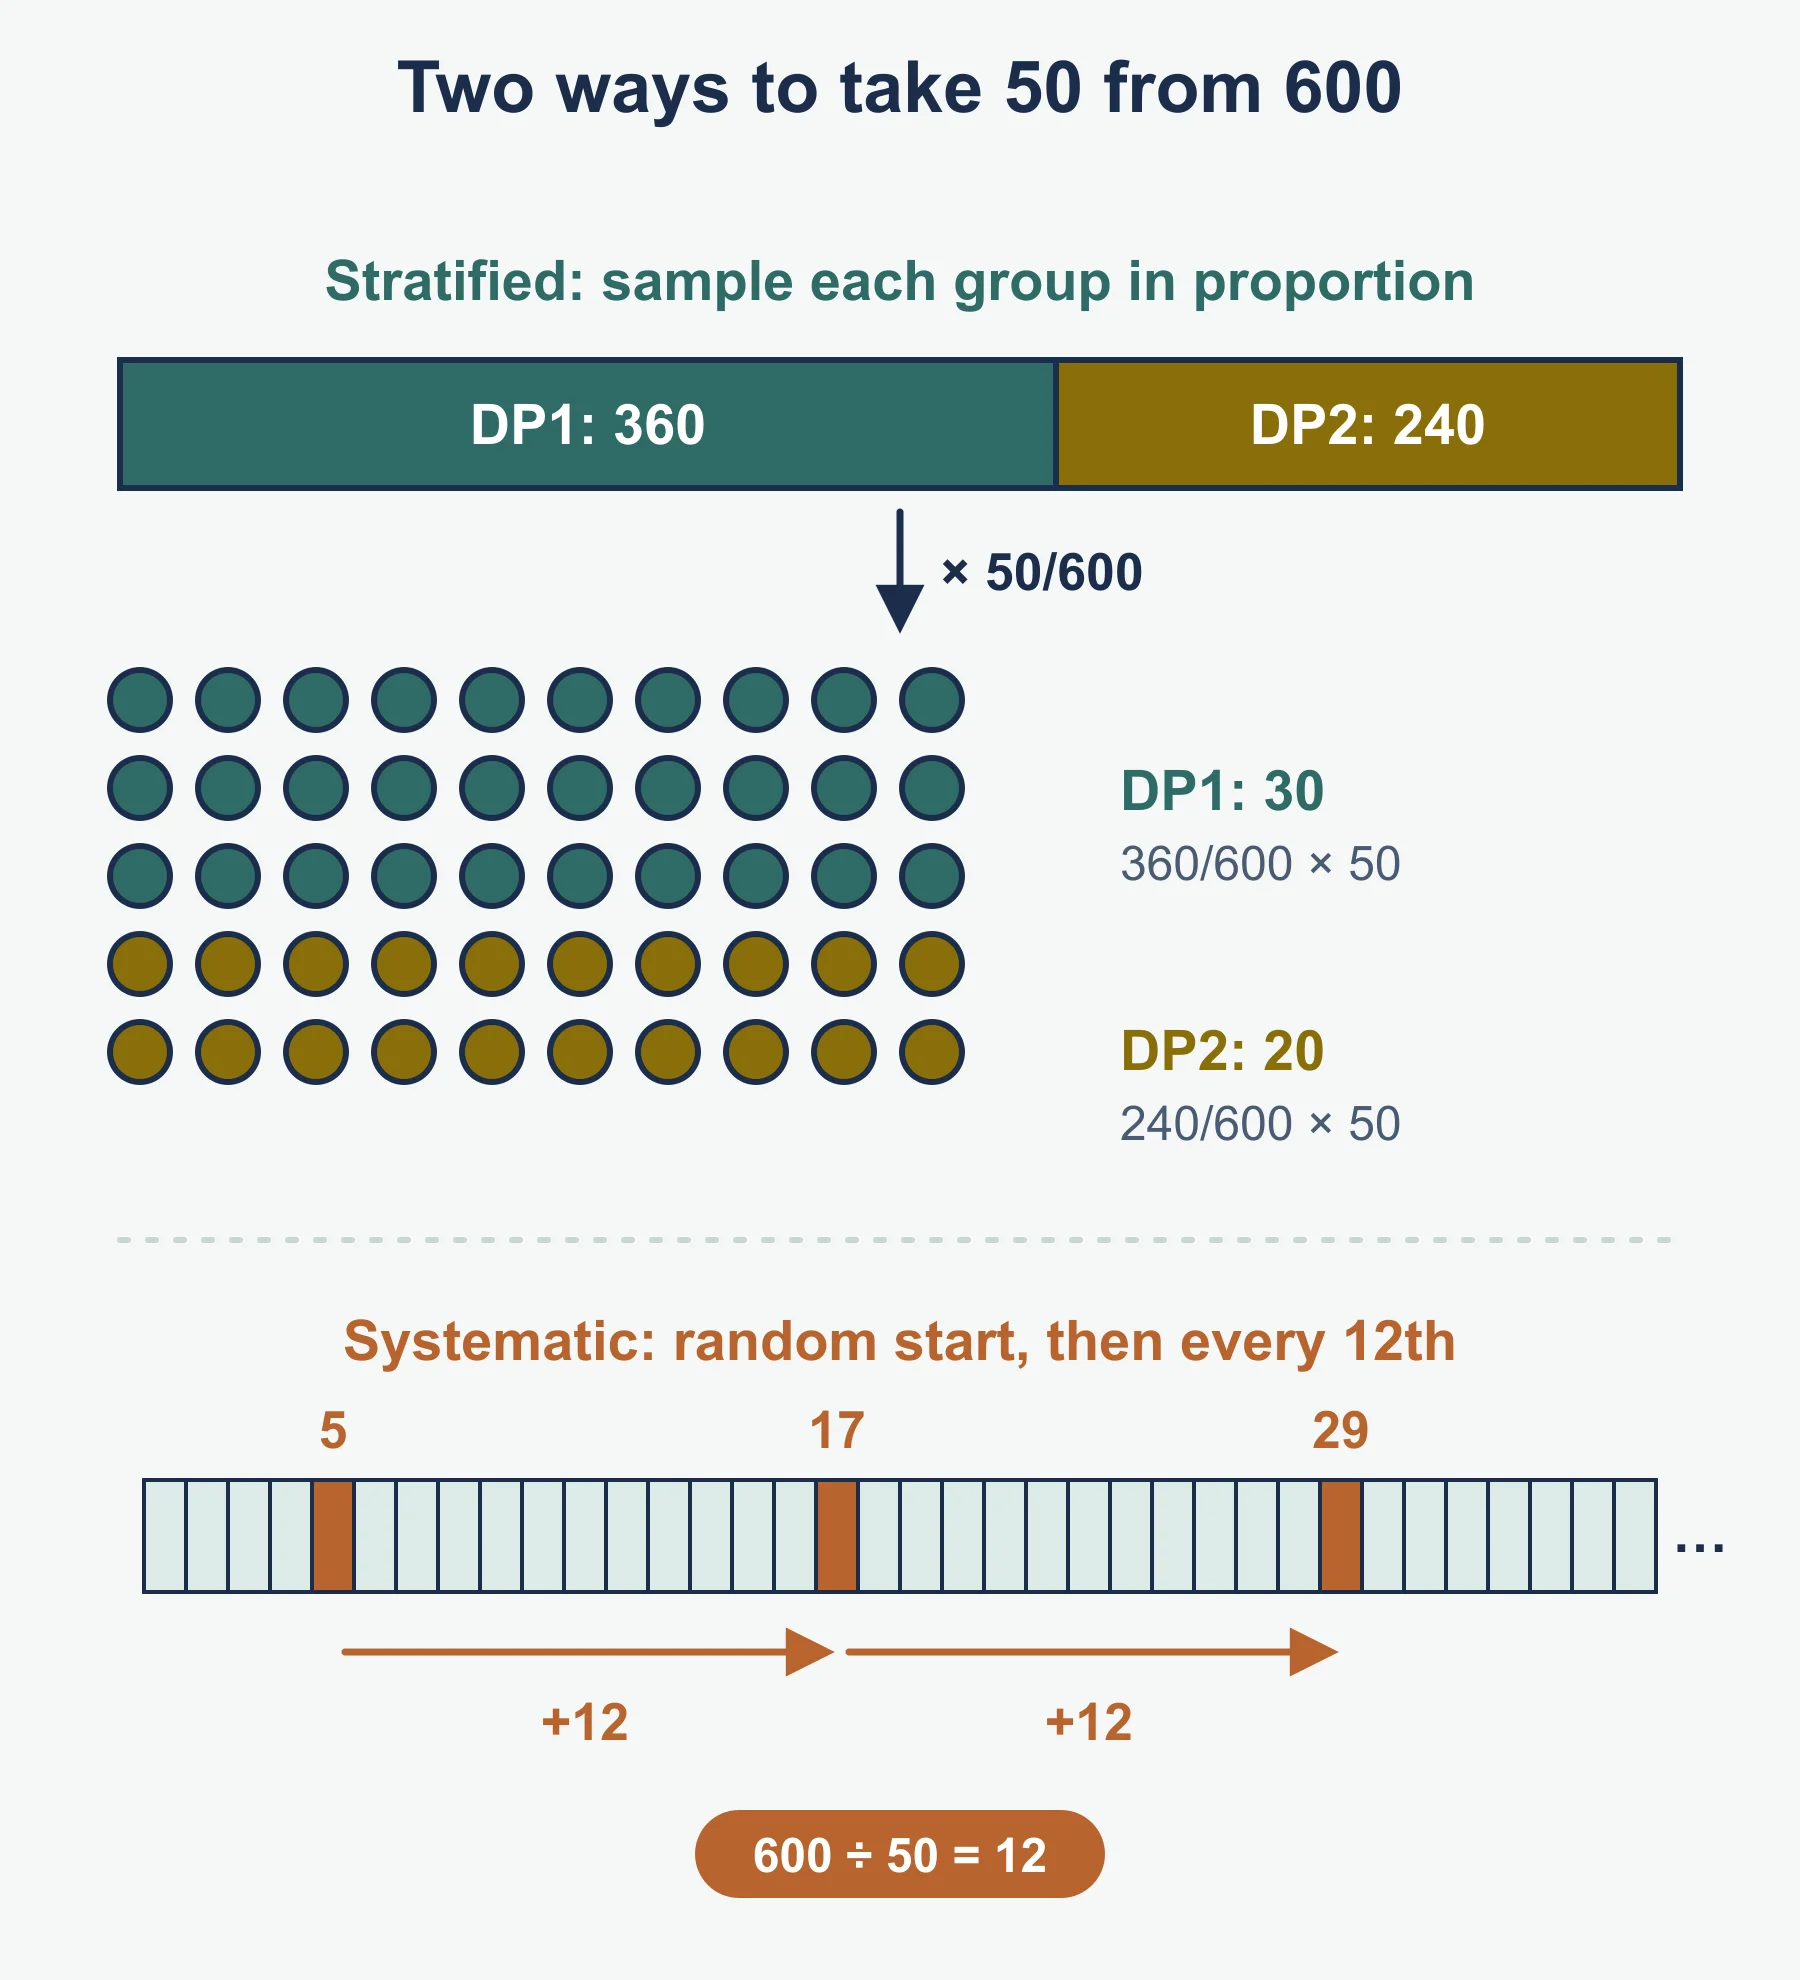
| Stratified | Split into groups (strata); sample each group in proportion to its size, at random | Needs the size of each group |
Worked example 1. A school has 360 DP1 and 240 DP2 students. A stratified sample of 50 is needed.
Total = 360 + 240 = 600
DP1: (360/600) × 50 = 30
DP2: (240/600) × 50 = 20
For a systematic sample of 50 from the list of 600, take every 600/50 = 12th name, starting at a random position from 1 to 12.
Outliers
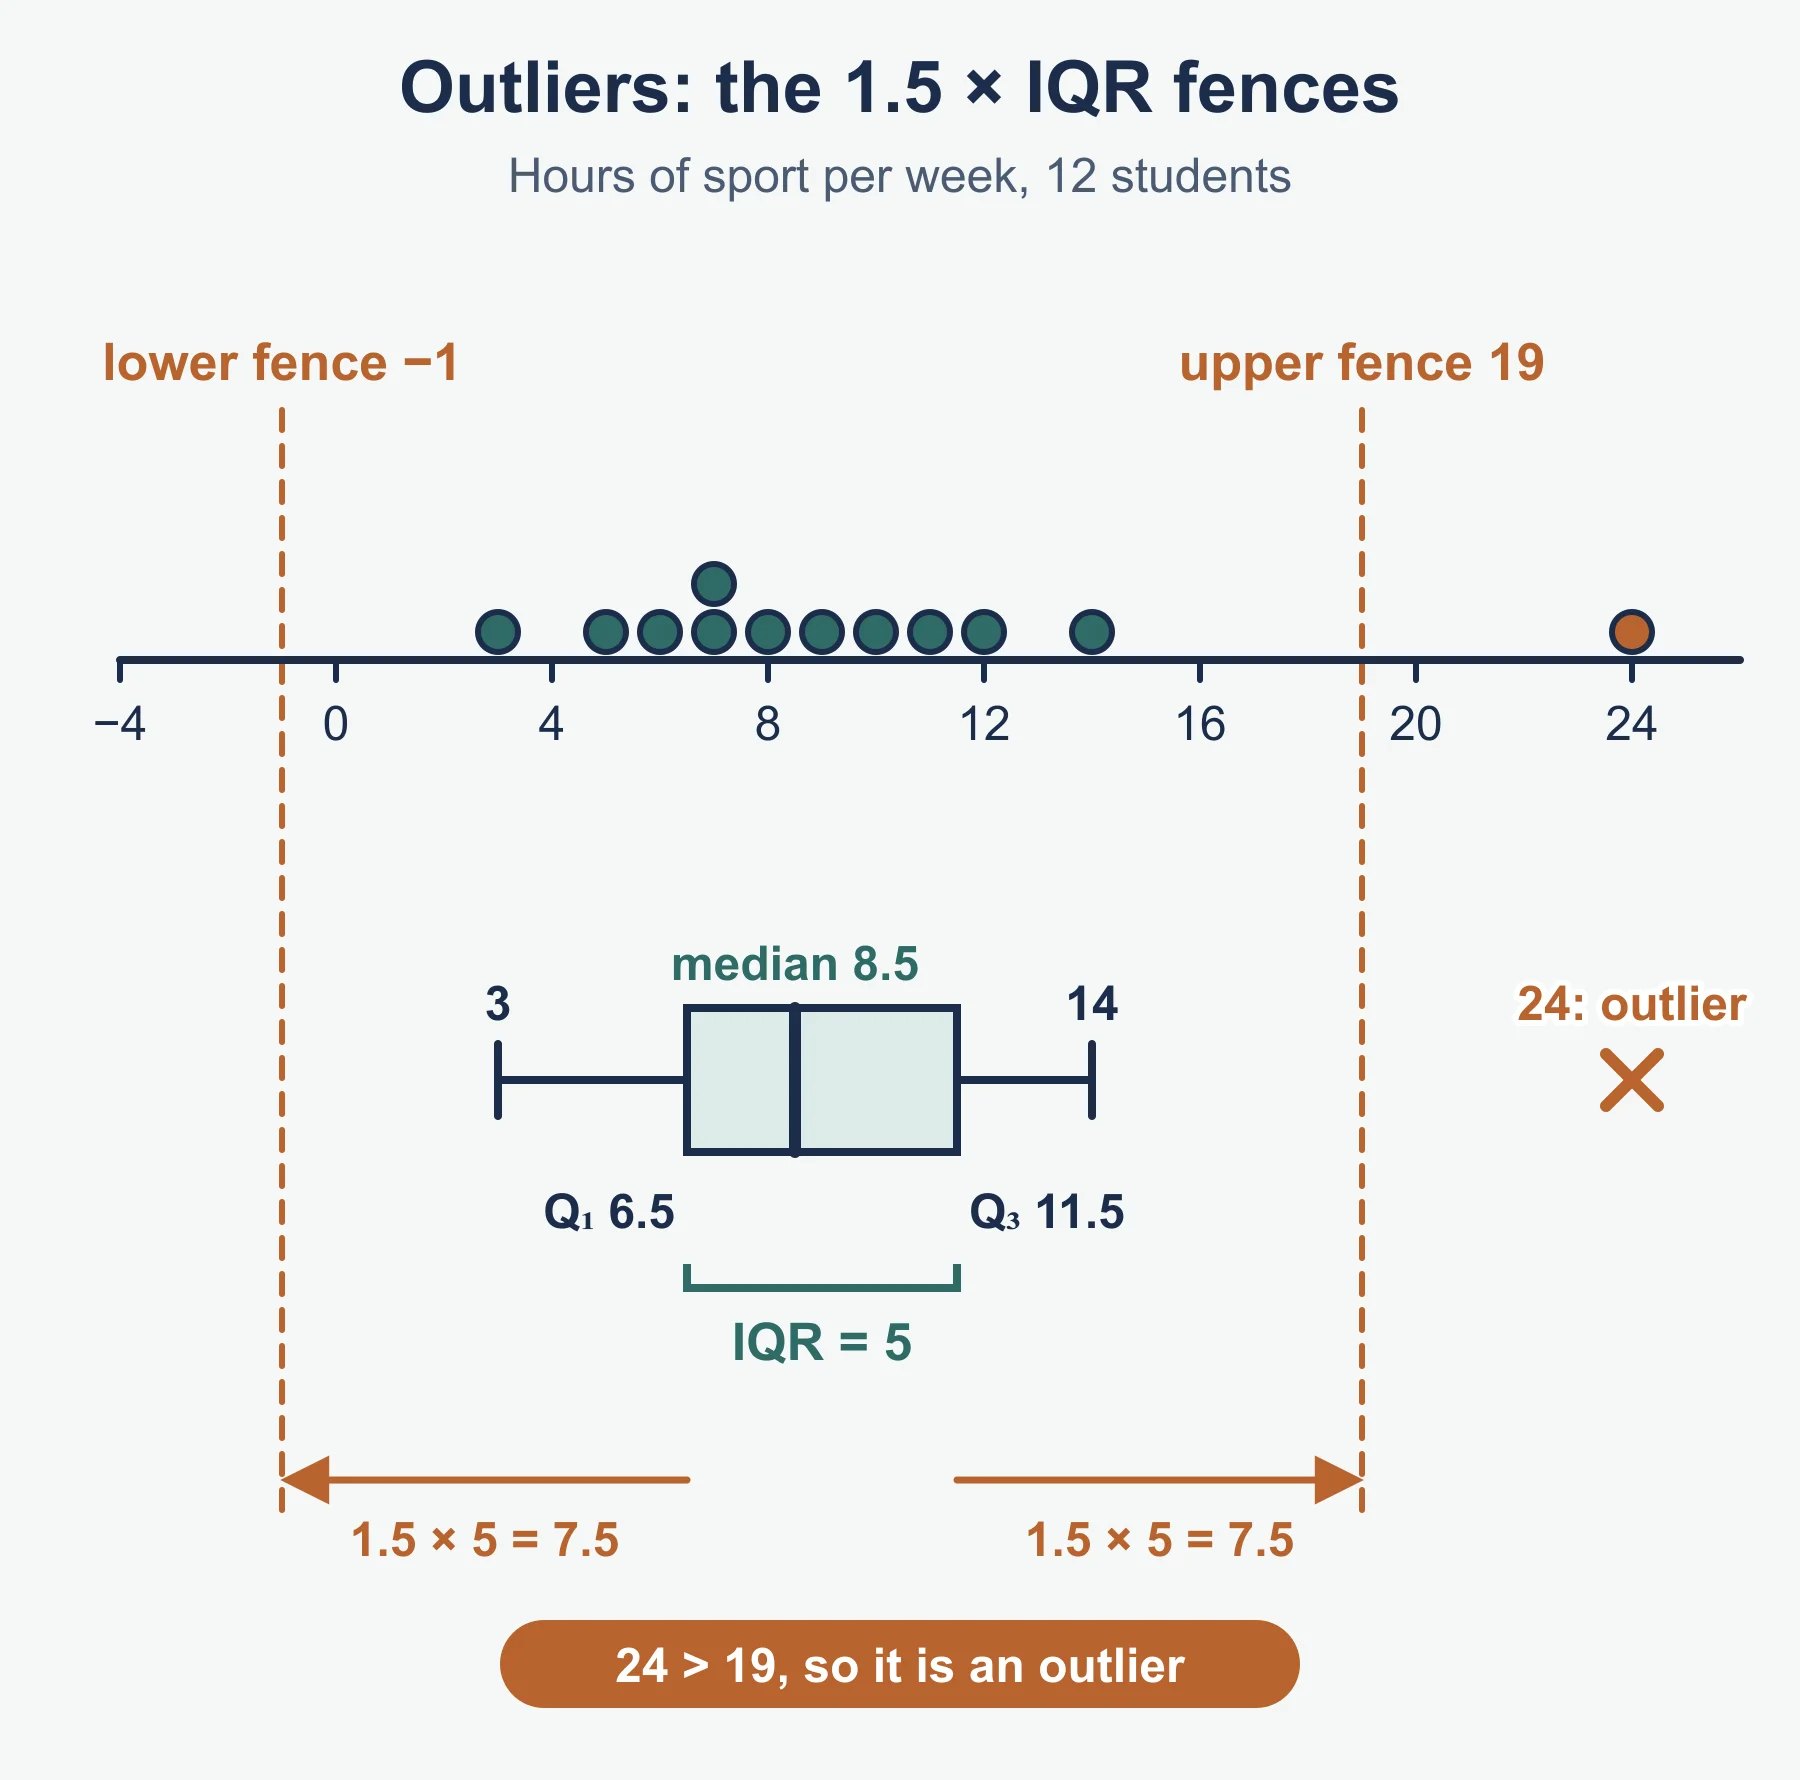
An outlier is a data item more than 1.5 × IQR from the nearest quartile.
lower fence = Q₁ − 1.5 × IQR
upper fence = Q₃ + 1.5 × IQR
In context, decide whether an outlier is a genuine value that belongs in the data or an error that should be checked or removed.
4.2 Presenting data
Class intervals are written as inequalities with no gaps, for example 10 ≤ t < 20. A frequency histogram uses equal class widths, so bar height is frequency. Frequency density histograms are not required.
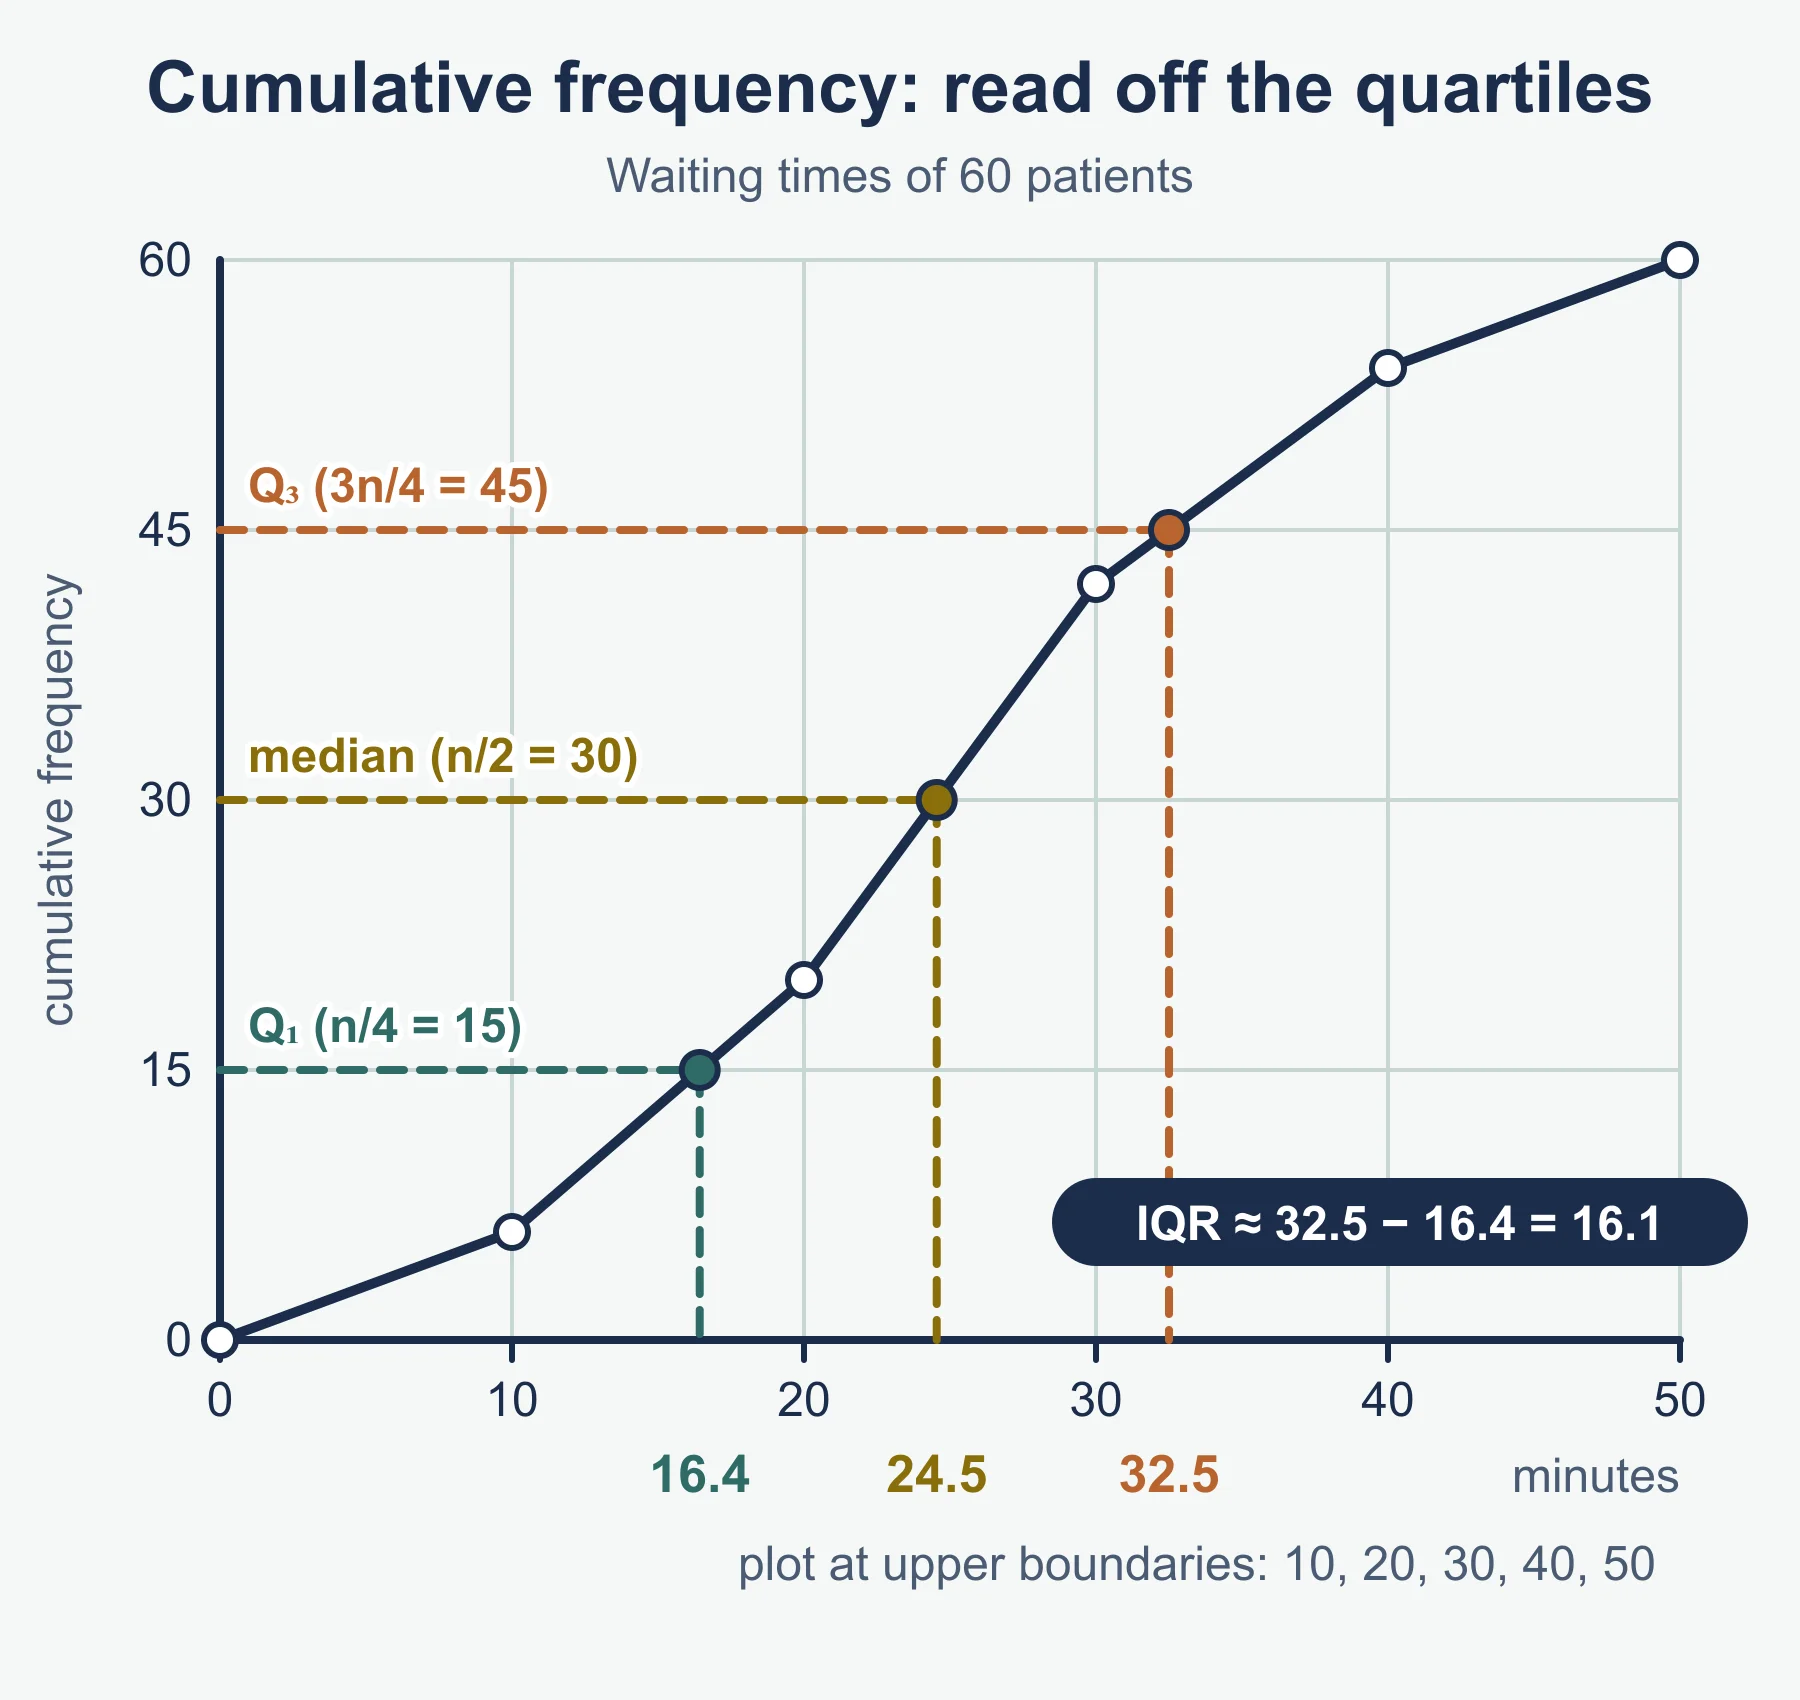
A cumulative frequency is a running total. Plot each cumulative frequency against the upper class boundary and join the points. For n items, read across from:
- n/2 for the median
- n/4 for Q₁ and 3n/4 for Q₃
- p% of n for the pth percentile
Worked example 2. Waiting times, t minutes, for 60 patients.
| t | 0 ≤ t < 10 | 10 ≤ t < 20 | 20 ≤ t < 30 | 30 ≤ t < 40 | 40 ≤ t < 50 |
|---|---|---|---|---|---|
| Frequency | 6 | 14 | 22 | 12 | 6 |
| Cumulative frequency | 6 | 20 | 42 | 54 | 60 |
Plot (10, 6), (20, 20), (30, 42), (40, 54), (50, 60), starting from (0, 0). The median is at 60/2 = 30, which lies in the class 20 ≤ t < 30. Reading from a graph joined with straight lines (linear interpolation):
median ≈ 20 + (30 − 20)/22 × 10 ≈ 24.5 minutes
Q₁ (15th) ≈ 10 + (15 − 6)/14 × 10 ≈ 16.4
Q₃ (45th) ≈ 30 + (45 − 42)/12 × 10 = 32.5
IQR ≈ 32.5 − 16.4 ≈ 16.1 minutes
90th percentile (54th) = 40 minutes
Box and whisker diagrams
A box and whisker diagram shows the minimum, Q₁, median, Q₃ and maximum. Outliers are marked with a cross, and the whisker stops at the most extreme value that is not an outlier.
To compare two distributions, comment on a measure of centre (median) and a measure of spread (IQR or range), in context. If the median sits near the middle of the box and the whiskers are about the same length, the data are roughly symmetric and may be normally distributed.
4.3 Summary statistics
Mean x̄ = Σx / n, or Σfx / Σf from a frequency table. For grouped data, use mid-interval values to estimate the mean. The modal class is the class with the highest frequency (equal class intervals only).
Worked example 3. Estimate the mean waiting time in worked example 2.
mid-interval values: 5, 15, 25, 35, 45
Σfx = 5(6) + 15(14) + 25(22) + 35(12) + 45(6) = 1480
x̄ ≈ 1480 / 60 ≈ 24.7 minutes
The modal class is 20 ≤ t < 30.
Worked example 4. Twelve students recorded the number of hours of sport they did in a week:
3, 5, 6, 7, 7, 8, 9, 10, 11, 12, 14, 24
Σx = 116, so x̄ = 116/12 ≈ 9.67 hours
Mode = 7
Median = mean of 6th and 7th values = (8 + 9)/2 = 8.5
Lower half 3, 5, 6, 7, 7, 8  → Q₁ = (6 + 7)/2 = 6.5
Upper half 9, 10, 11, 12, 14, 24 → Q₃ = (11 + 12)/2 = 11.5
IQR = 11.5 − 6.5 = 5
Upper fence = 11.5 + 1.5 × 5 = 19, so 24 is an outlier
Lower fence = 6.5 − 7.5 = −1, so there are no low outliers
On a box plot, the whiskers reach 3 and 14 and 24 is a cross. Different quartile methods exist, so a GDC and a hand method can disagree on some data sets.
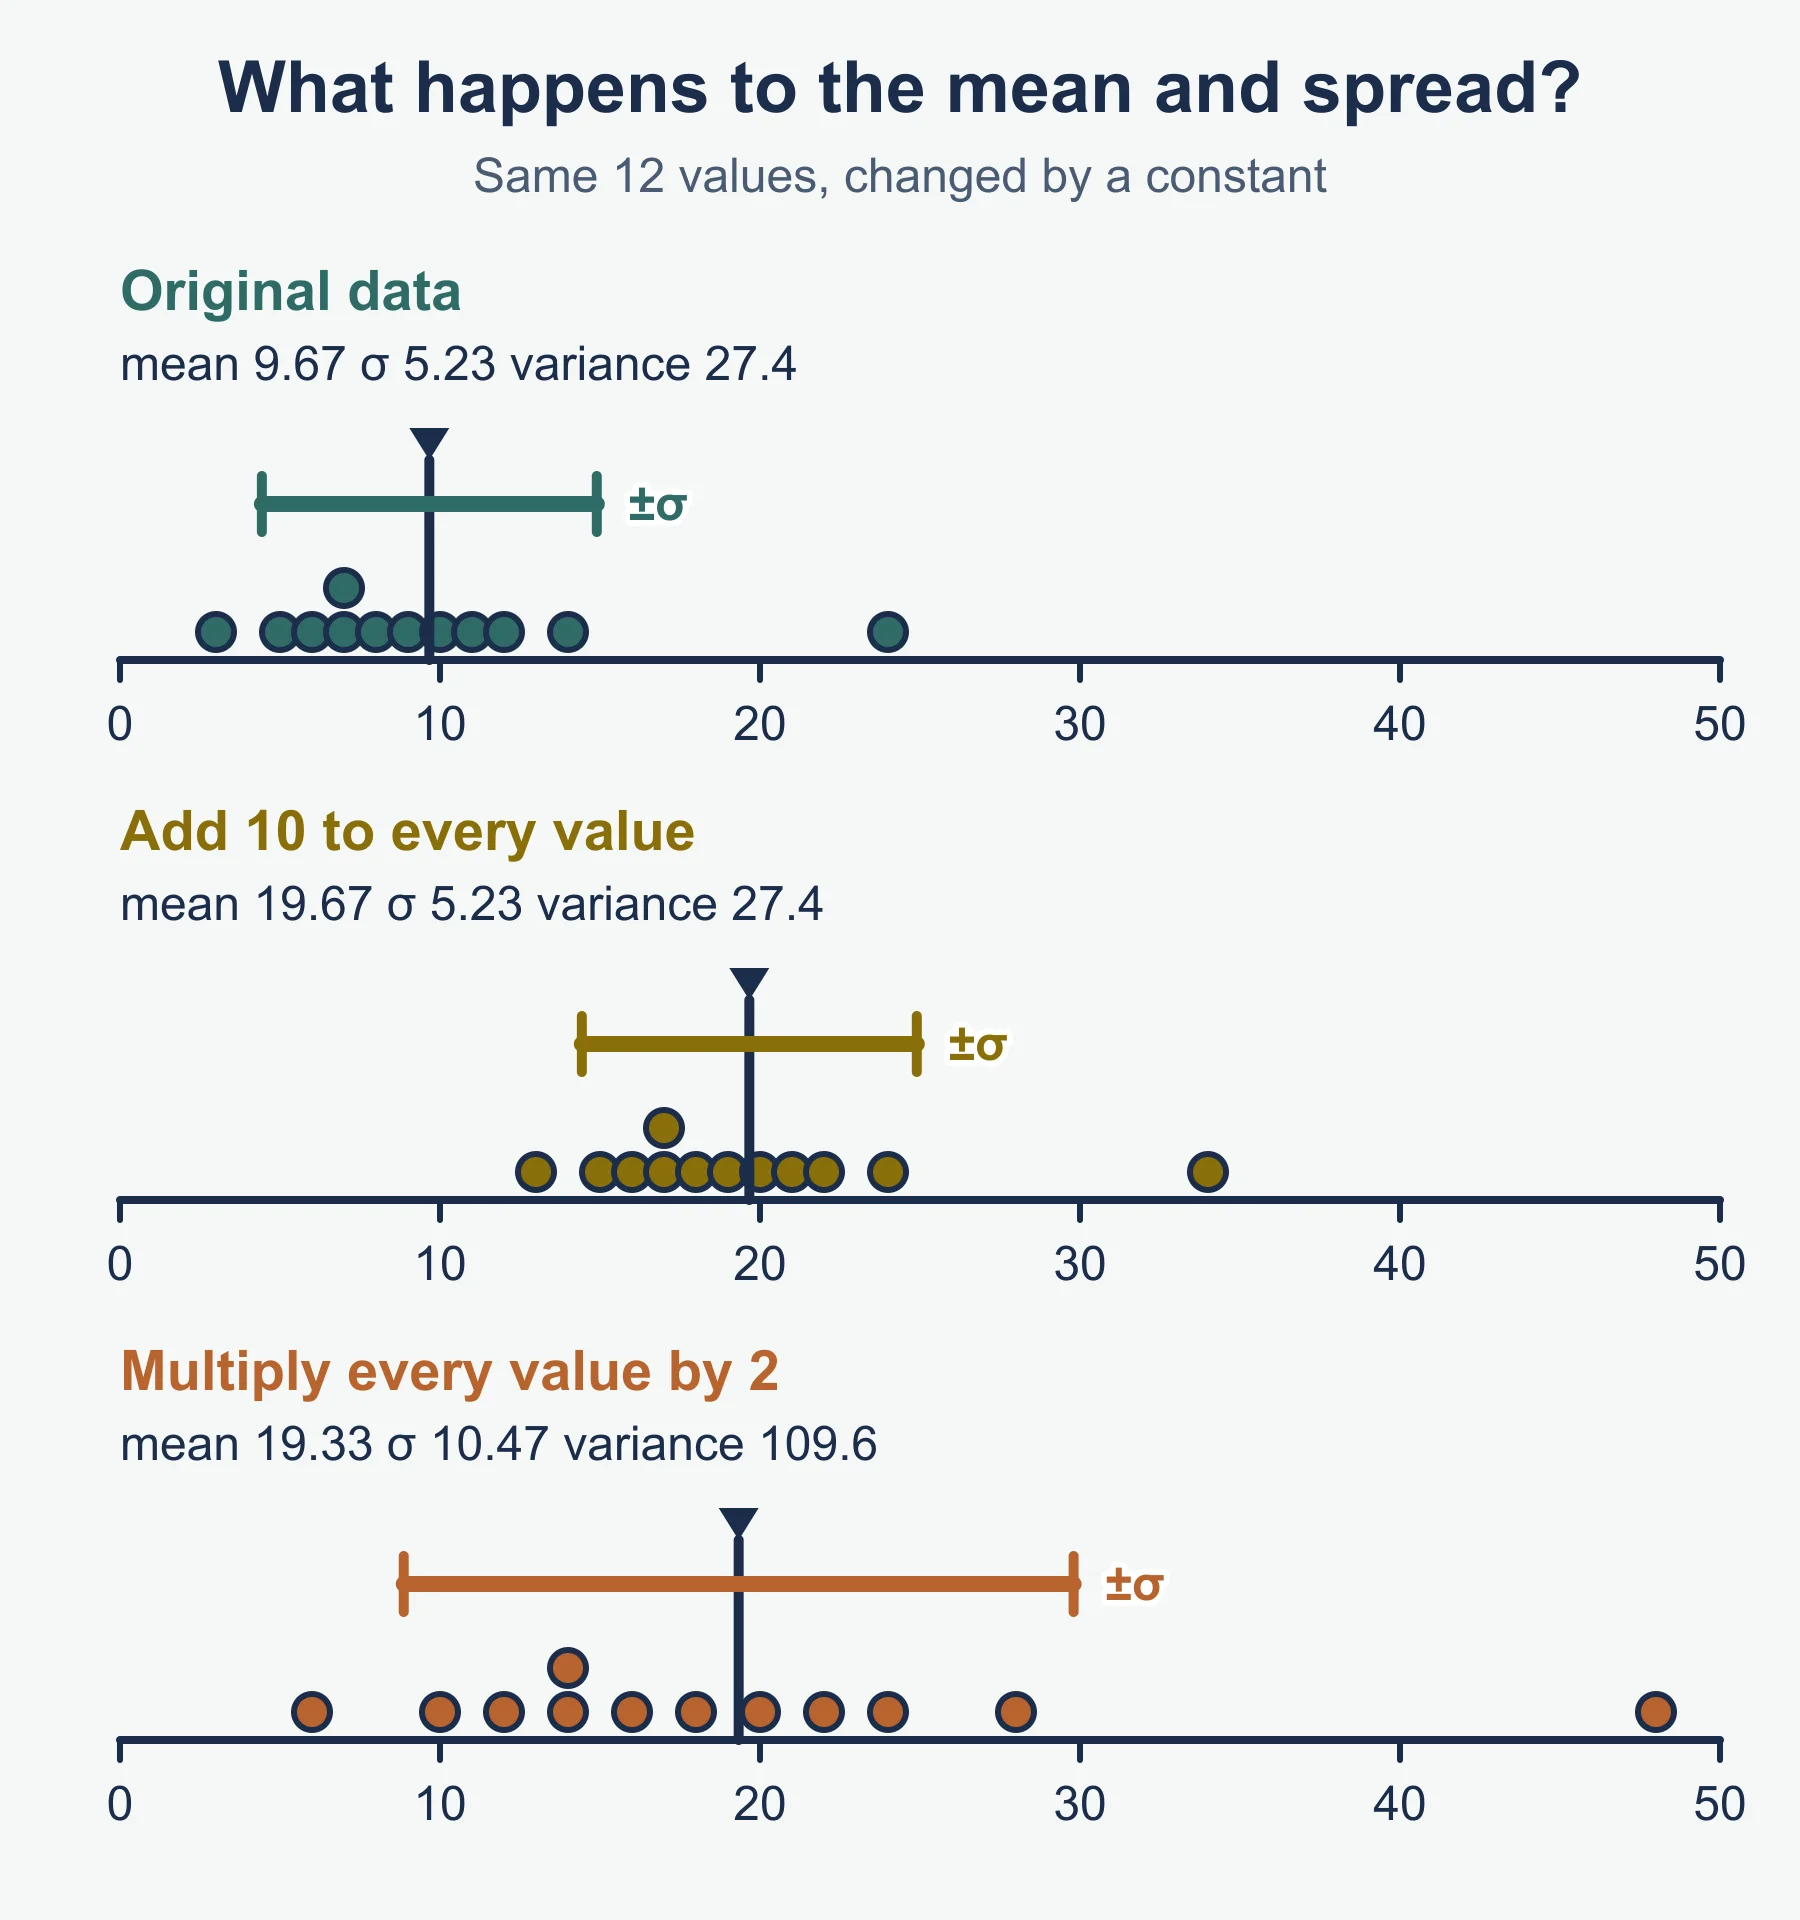
Standard deviation and variance. The guide expects these from technology only. Variance is the square of the standard deviation. On your GDC, treat the data as the population unless told otherwise and use σx. For the data above, σ ≈ 5.23 hours and variance ≈ 27.4 hours². Removing the outlier 24 would drop the mean to 8.36 but move the median only to 8: the median and IQR resist outliers.
Effect of constant changes
| Change to every data item | Mean, median, quartiles | Standard deviation, IQR, range | Variance |
|---|---|---|---|
| Add or subtract c | Add or subtract c | Unchanged | Unchanged |
| Multiply by k (k > 0) | Multiply by k | Multiply by k | Multiply by k² |
Worked example 5. Daily temperatures have mean 18.5 °C and standard deviation 4.2 °C. Convert to Fahrenheit using F = 1.8C + 32.
new mean = 1.8 × 18.5 + 32 = 65.3 °F
new SD = 1.8 × 4.2 = 7.56 °F   (adding 32 does not change the spread)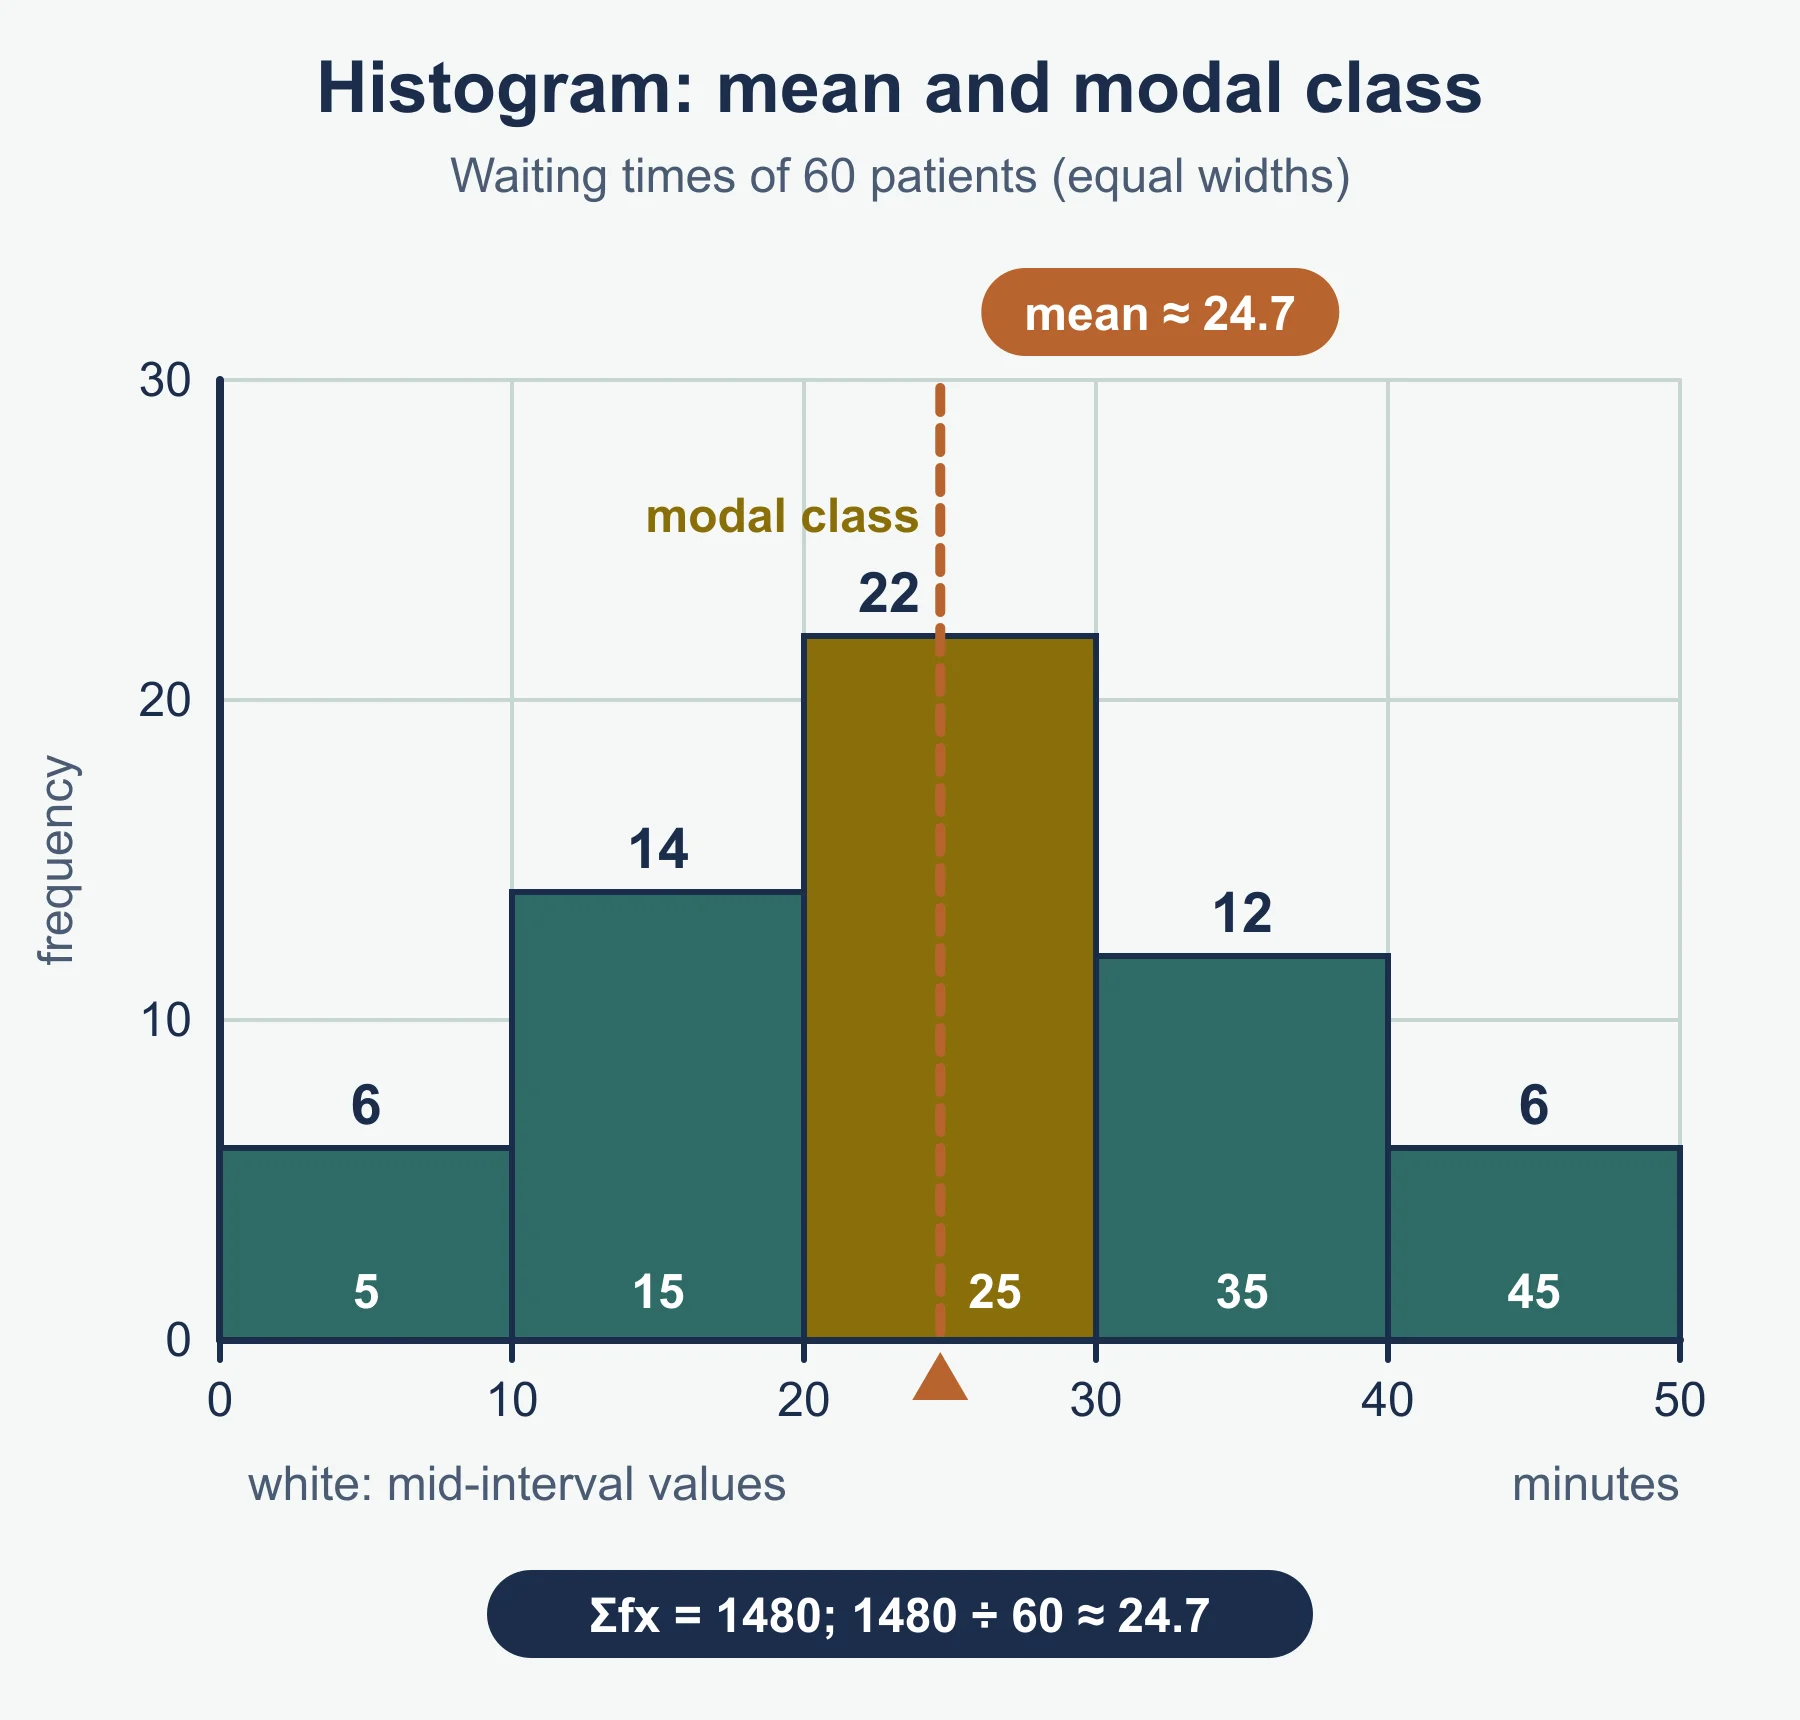
4.4 Correlation and the regression line of y on x
Bivariate data come in pairs (x, y). Plot them on a scatter diagram and describe the correlation as positive, negative or zero, and as strong or weak. A line of best fit by eye should pass through the mean point (x̄, ȳ).
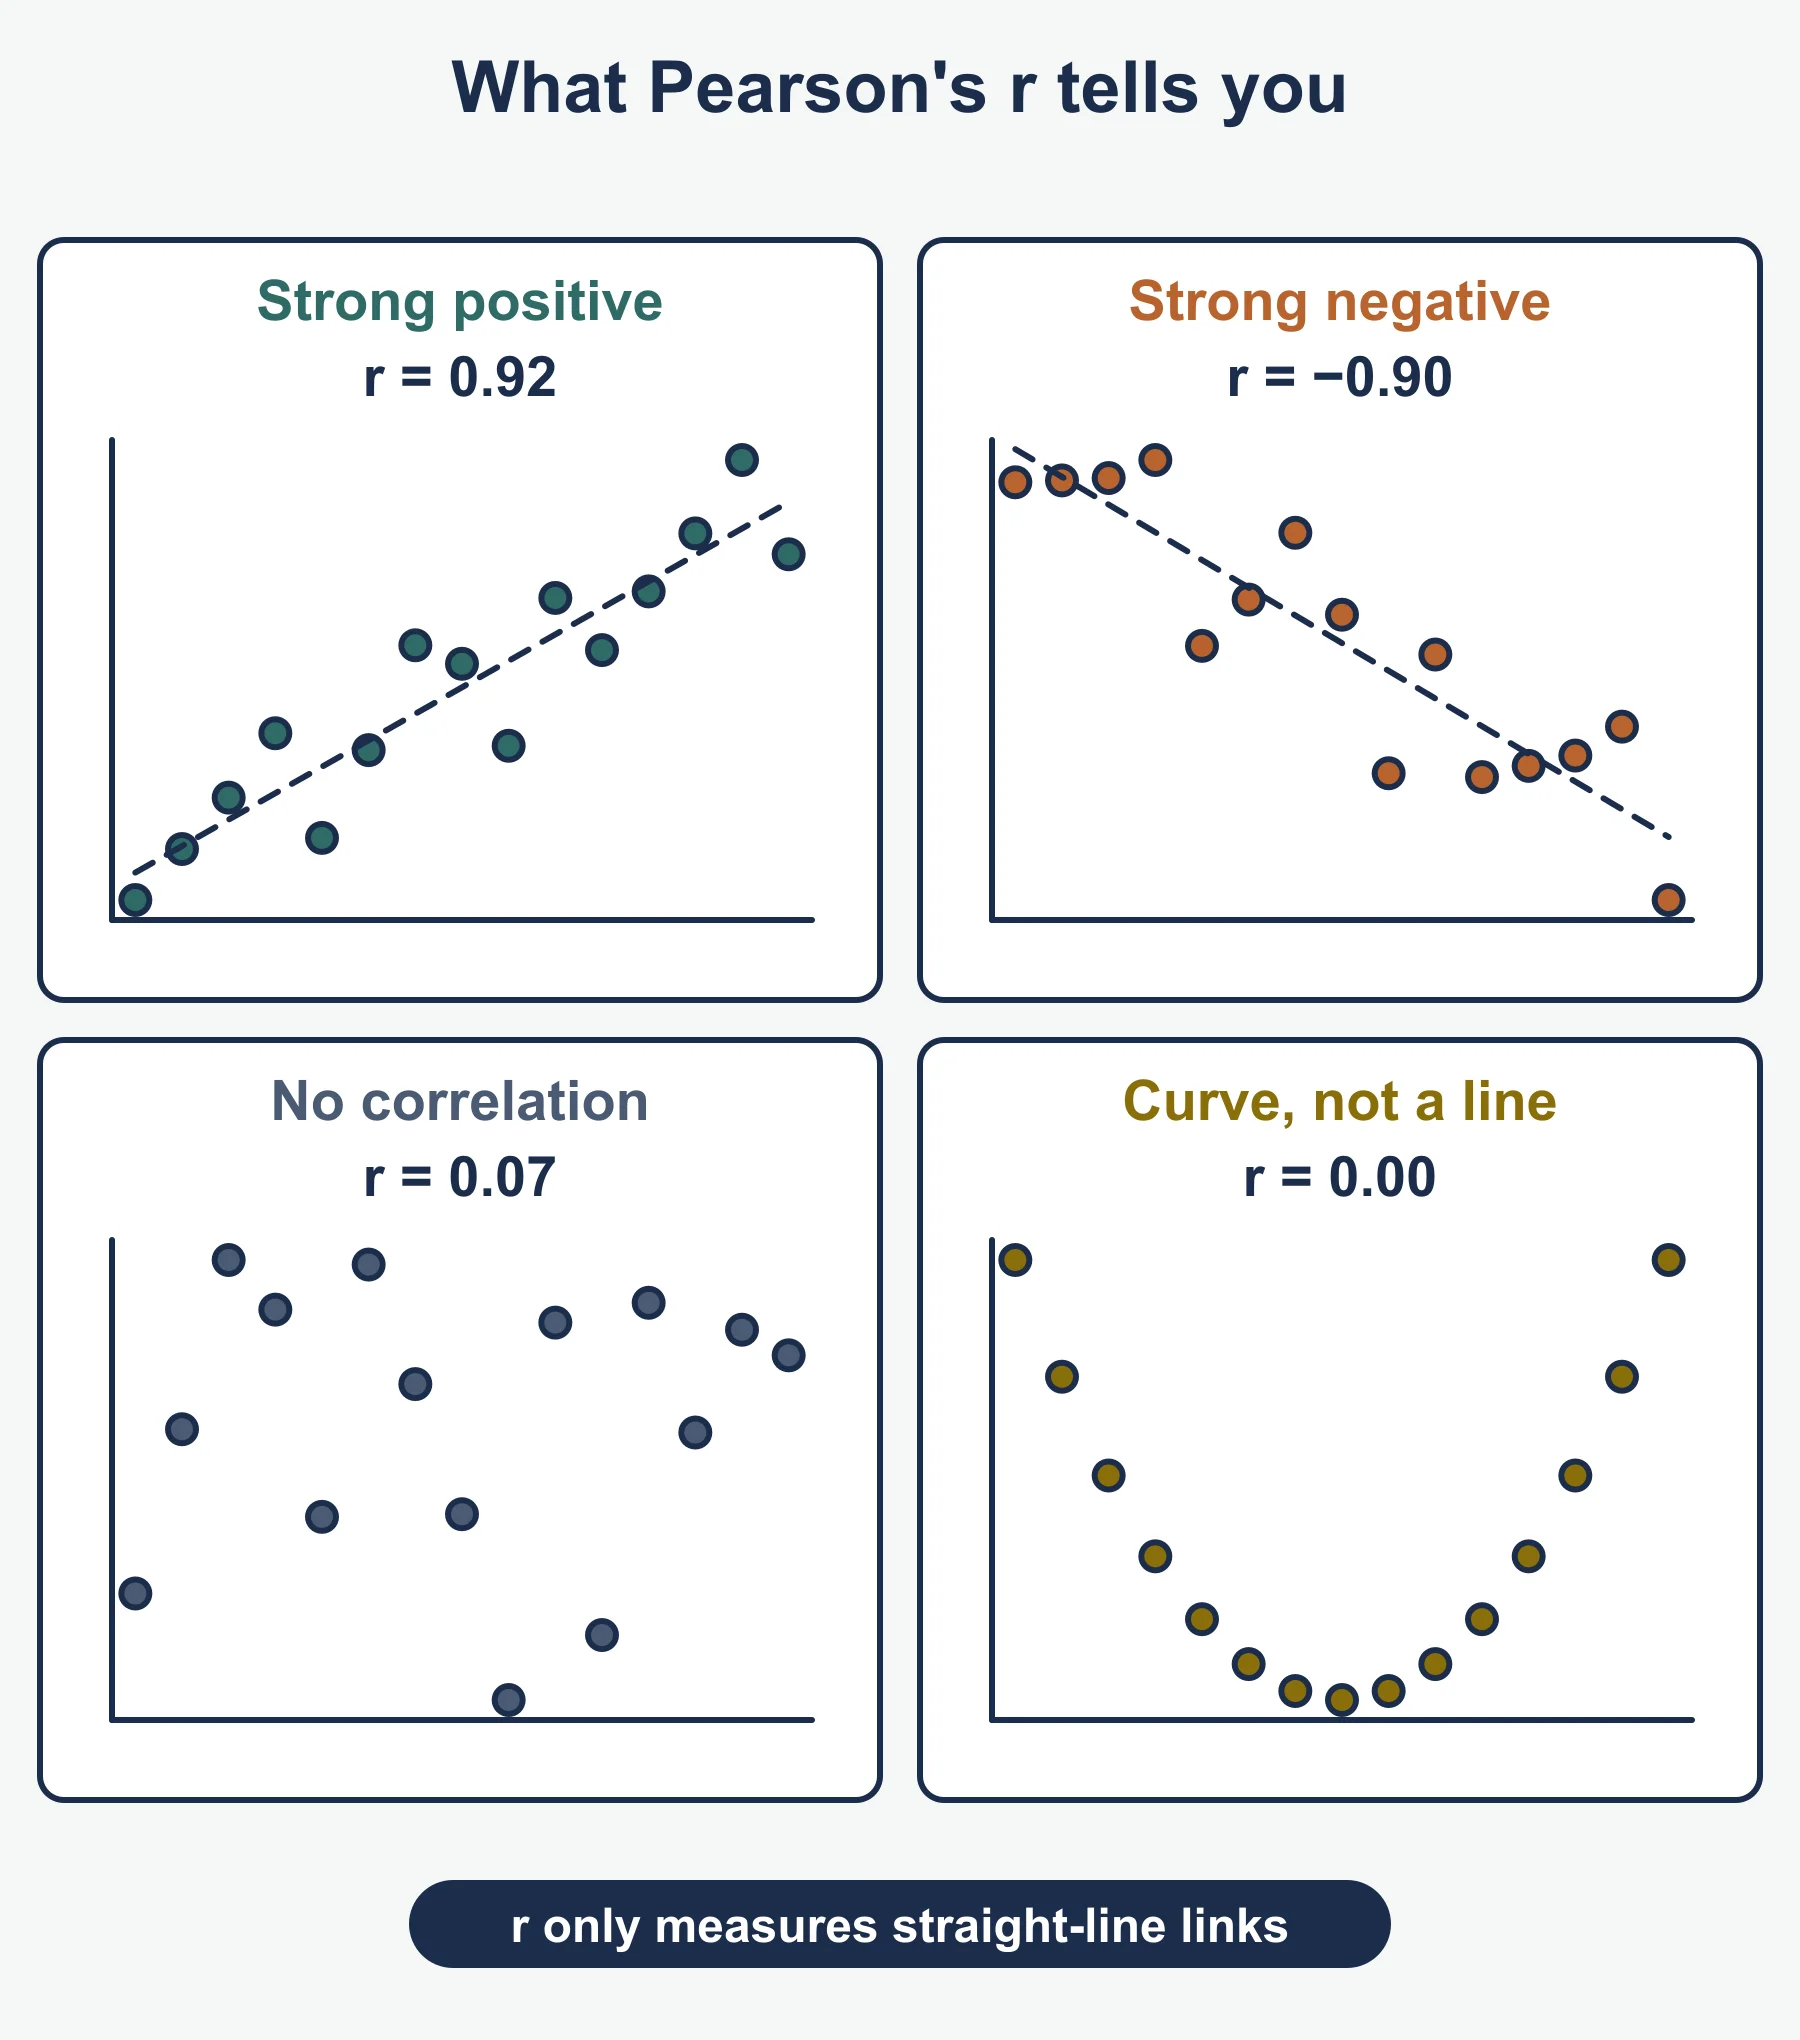
Pearson’s product-moment correlation coefficient, r, measures the strength of a linear relationship, with −1 ≤ r ≤ 1. Values near 1 mean strong positive linear correlation, near −1 strong negative, and near 0 no linear correlation. Find r with technology. It is only meaningful for linear relationships: data on a clear curve can have r close to 0. Where a question gives a critical value of r, the correlation is significant if |r| is greater than it.
Correlation does not imply causation. Both variables may depend on a third.
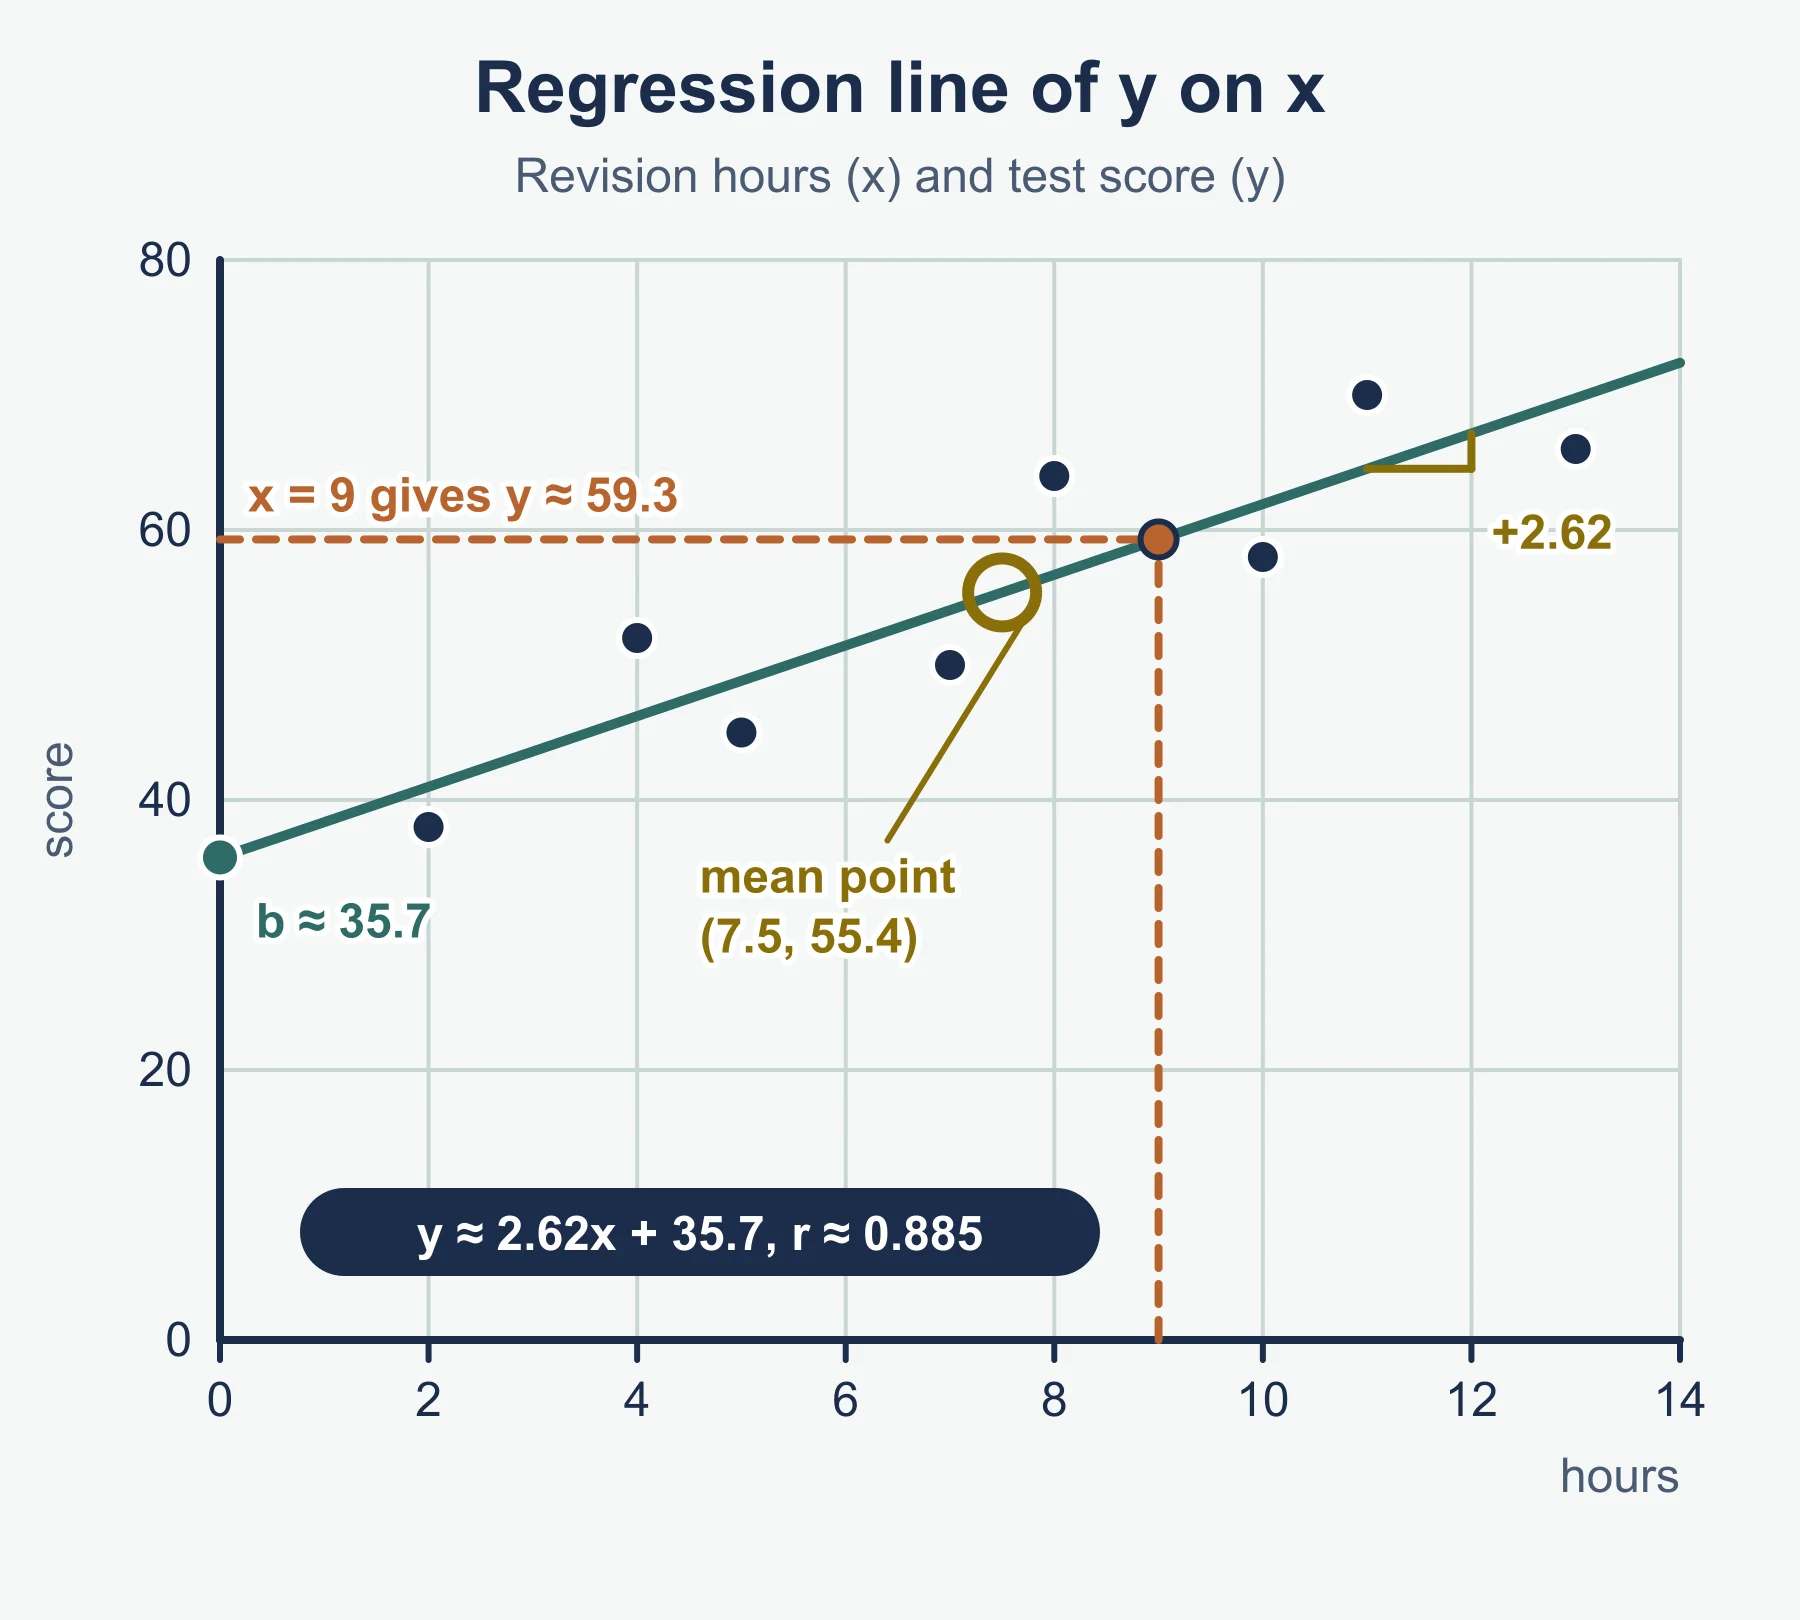
The regression line of y on x, y = ax + b, is found with technology and is used to predict y from a given x. Here a is the gradient: the change in y for each increase of 1 in x. b is the value of y when x = 0, which may have no sensible meaning in context.
Worked example 6. Eight students recorded revision hours, x, and test score, y (out of 100).
| x | 2 | 4 | 5 | 7 | 8 | 10 | 11 | 13 |
|---|---|---|---|---|---|---|---|---|
| y | 38 | 52 | 45 | 50 | 64 | 58 | 70 | 66 |
Using a GDC (linear regression):
r ≈ 0.885  → strong positive linear correlation
y ≈ 2.62x + 35.7
mean point (7.5, 55.375) lies on this line
Each extra hour of revision is associated with about 2.62 more marks on average; 35.7 is the predicted score for no revision.
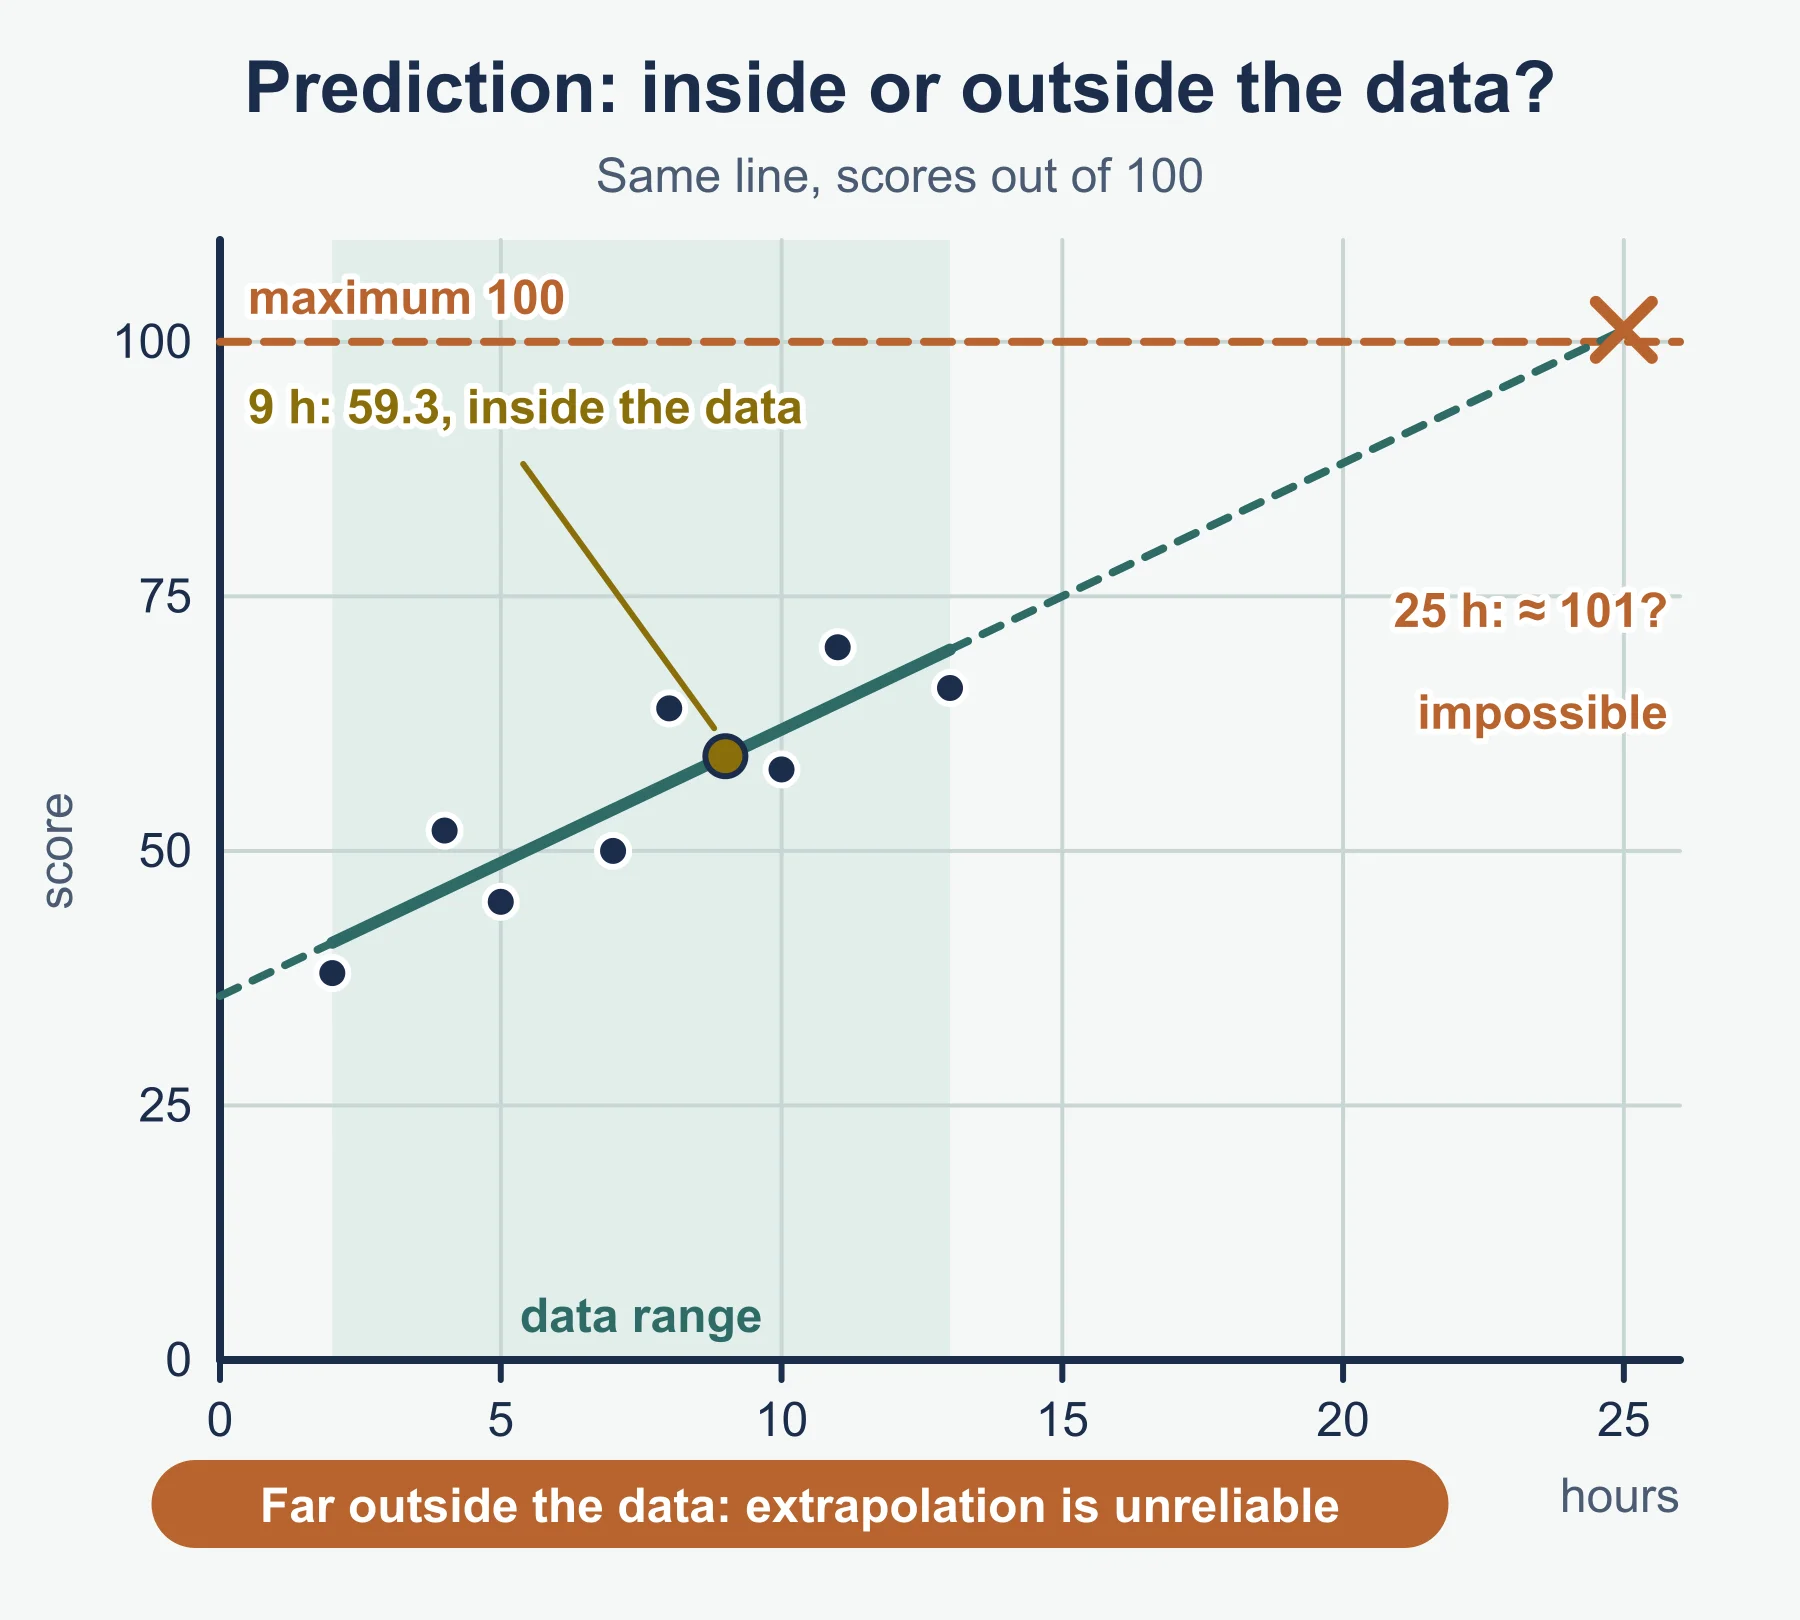
To predict the score for 9 hours: y ≈ 2.62 × 9 + 35.7 ≈ 59.3. Use unrounded GDC coefficients.
Predicting for 25 hours gives about 101, which is impossible for a test out of 100. This is extrapolation: x = 25 is far outside the data range of 2 to 13, so the prediction is unreliable.
4.10 The regression line of x on y
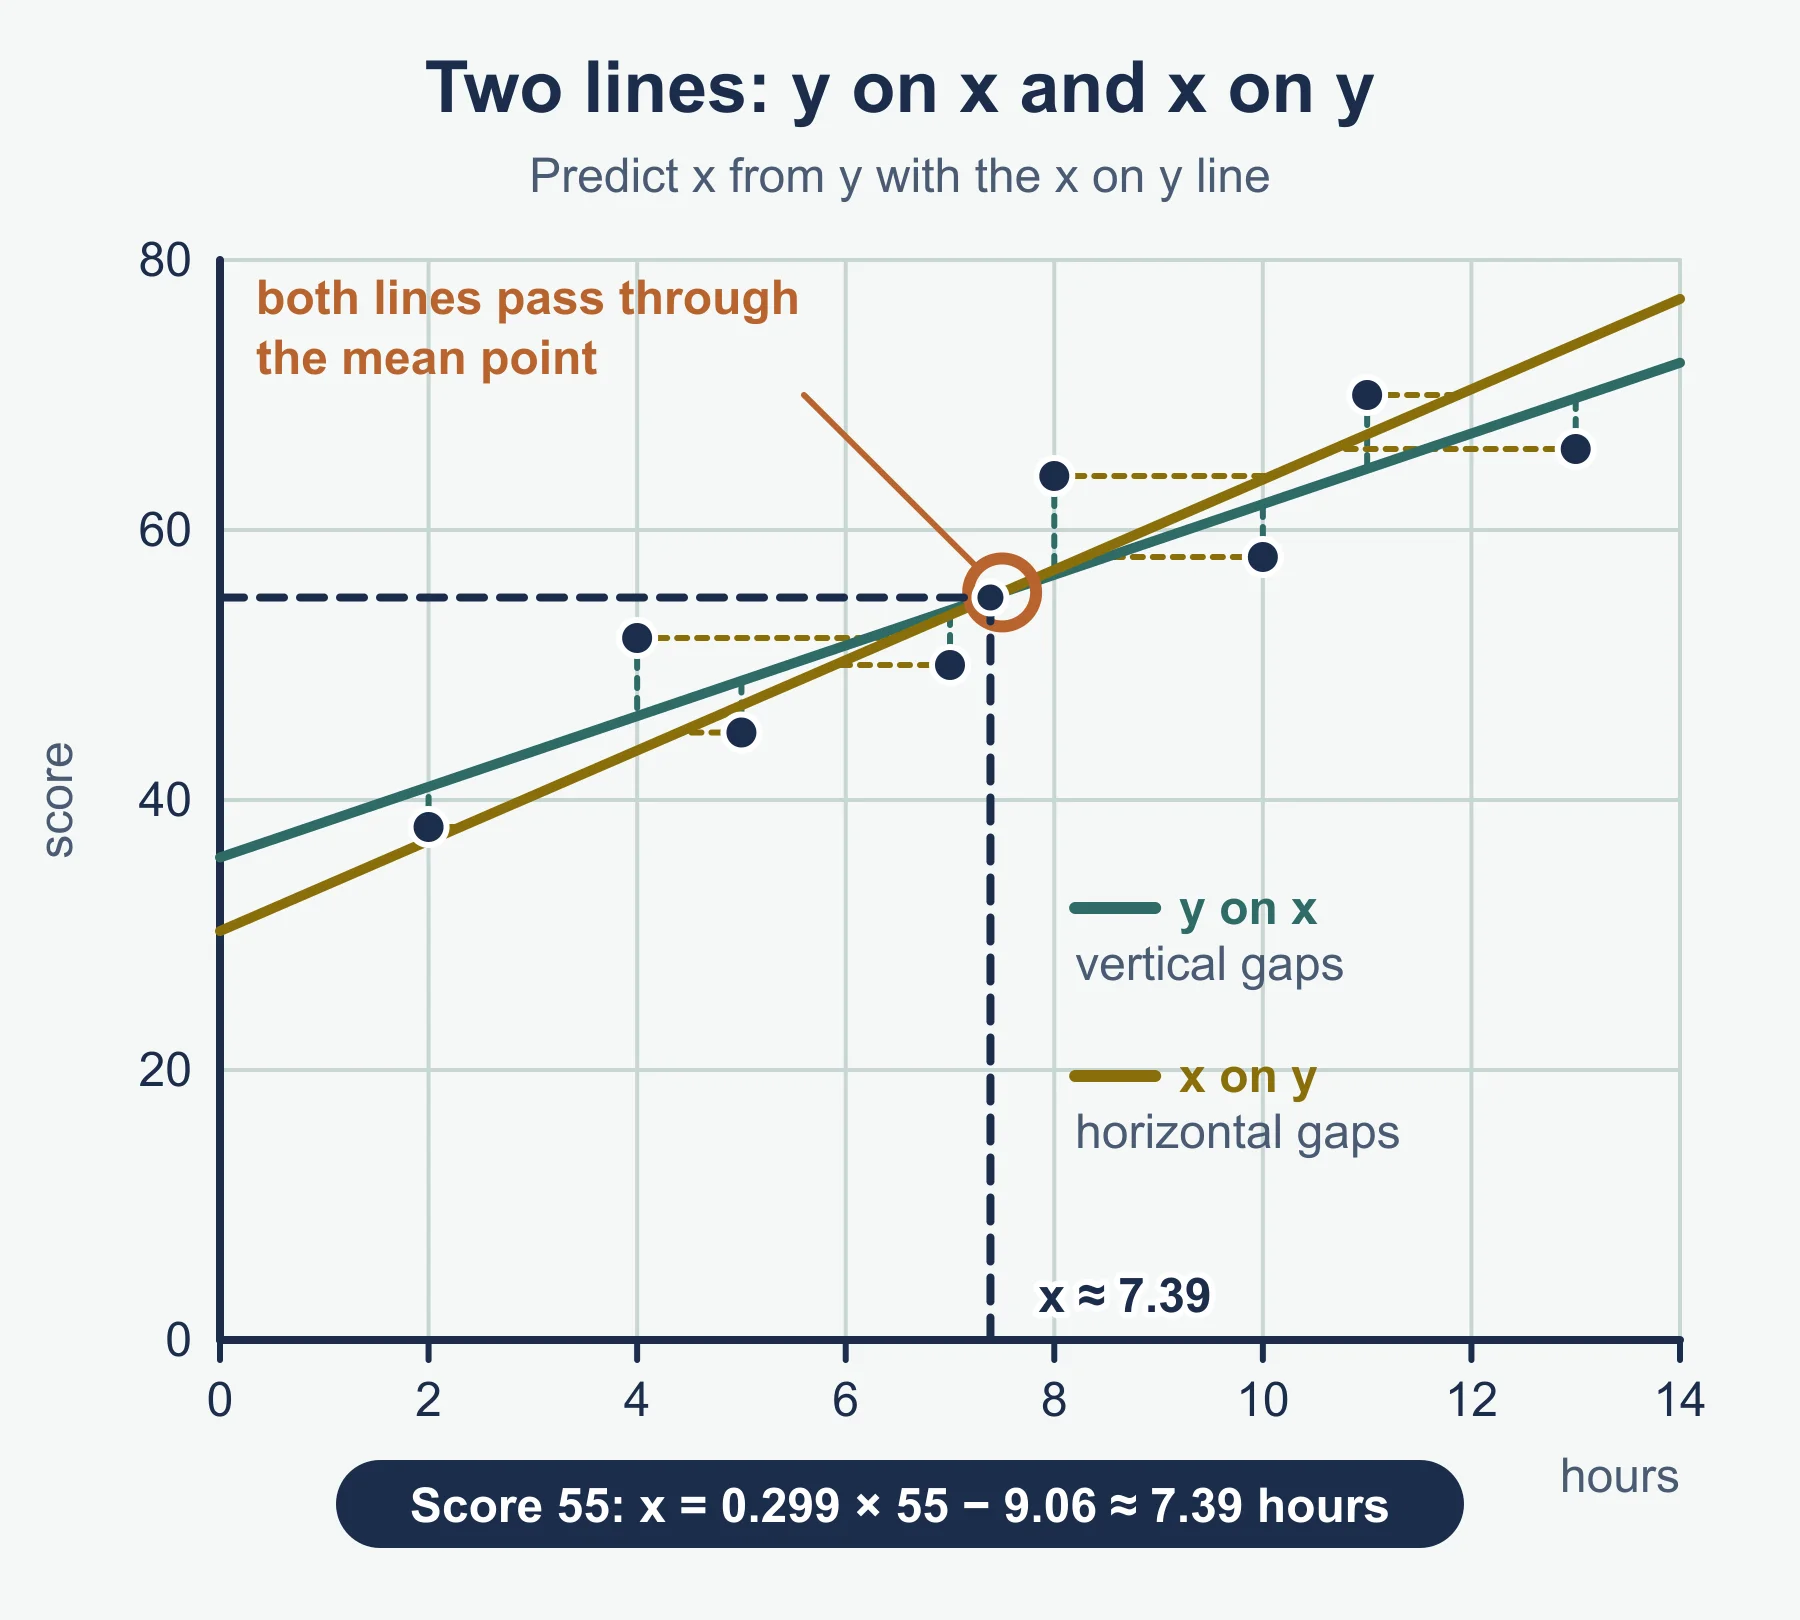
To predict x from a given y, use the regression line of x on y, found with technology by making y the independent variable. Do not rearrange the y on x line. The two lines are different unless r = ±1, and both pass through the mean point.
Worked example 6 continued. Estimate the revision hours for a score of 55.
x on y line: x ≈ 0.299y − 9.06
x ≈ 0.299 × 55 − 9.06 ≈ 7.39 hours
Rearranging the y on x line would give 7.36, but that is the wrong method, even though the numbers here are close. Likewise, do not use the x on y line to predict y.
Using your GDC
- One-variable statistics (with a frequency list if needed) gives x̄, σx, Q₁, median and Q₃.
- Two-variable linear regression gives a, b and r. Swap the lists to get the x on y line.
- Write the equation down before using it.
Common errors
- Plotting cumulative frequency at lower class boundaries or mid-points instead of upper boundaries.
- Measuring the outlier fence from the median instead of the nearest quartile.
- Adding a constant to the standard deviation, or multiplying the variance by k instead of k².
- Rearranging y = ax + b to predict x from y instead of using the x on y line.
- Treating a high r as proof of cause.
- Giving a prediction far outside the data range without a warning about extrapolation.
Where to go next
Next, use the revision notes and the practice questions. For other units, see the functions study guide and the calculus study guide. See also the AA syllabus guide and exam preparation guide.
Frequently asked questions
What does Pearson’s correlation coefficient r measure? r measures the strength of a linear relationship, with −1 ≤ r ≤ 1. Values near 1 mean strong positive linear correlation and values near −1 strong negative linear correlation.
What is extrapolation and why is it unreliable? Extrapolation is predicting outside the range of the data. The pattern may not continue, so a prediction can be impossible, such as a test score above 100.
Where do you plot points on a cumulative frequency graph? Plot each cumulative frequency against the upper class boundary and join the points, starting from the lower end at zero. Read the median at n/2 and the quartiles at n/4 and 3n/4.
What is the difference between discrete and continuous data? Discrete data can take only separate values, usually counts such as goals scored. Continuous data can take any value in a range, such as a measured time or length.
What do a and b mean in the regression line y = ax + b? a is the change in y for each increase of 1 in x, and b is the predicted value of y when x = 0, which may have no sensible meaning in context.
Official syllabus
International Baccalaureate Organization, Diploma Programme, Mathematics: analysis and approaches guide, first assessment 2021 (published February 2019, updated November 2020).
Get free revision emails (optional)
Occasional emails with practice questions, worked explanations and links to free resources for the qualification and subjects you choose. No spam, and you can unsubscribe from any email. The free tools on this site never need an email.
Related resources
-
Study guides
IB DP Mathematics: Analysis and Approaches – Polynomials, rational functions, odd/even functions and modulus graphs (HL) Study Guide
Study guide to IB DP Maths AA HL further functions: factor theorem, roots of polynomials, rational graphs, odd/even and inverse functions, modulus.
Mathematics: Analysis and Approaches · International Baccalaureate · IB
Read guide -
Practice questions
IB DP Mathematics: Analysis and Approaches – Sampling, data presentation, summary statistics and regression Practice Questions
12 original IB DP Maths AA SL and HL statistics and regression questions, calculator-free and calculator allowed, with worked mark-by-mark answers.
Mathematics: Analysis and Approaches · International Baccalaureate · IB
Try questions -
Revision notes
IB DP Mathematics: Analysis and Approaches – Sampling, data presentation, summary statistics and regression Revision Notes
Revision notes for IB DP Maths AA SL and HL statistics: sampling, outliers, box plots, mean and standard deviation, r and both regression lines.
Mathematics: Analysis and Approaches · International Baccalaureate · IB
Revise topic
Related articles
-
teaching
A Level tuition in Dubai: Cambridge or Pearson Edexcel International A Level?
Schools in Dubai and Abu Dhabi teach either Cambridge International AS & A Level or Pearson Edexcel International A Level. How the two are structured, why it matters for tuition, and how online classes from Lahore work.
9 October 2026
-
curriculum guides
Choosing subjects at IGCSE and A Level
How subject choices at 14 and 16 affect university options later, and how to keep pathways open without overloading a timetable.
28 July 2026
Studying this with a teacher
Working through Mathematics: Analysis and Approaches IB?
This page is free and stays free. If you would rather be taught it, Marlbridge runs Mathematics: Analysis and Approaches classes one-to-one, online in your own time zone. The first trial class is free. WhatsApp replies within an hour (8am–11pm Pakistan time, every day); email the same day.
IB Mathematics: Analysis and Approaches teachers at Marlbridge

