
Revision Notes
IB DP Mathematics: Applications and Interpretation – Data collection, non-linear regression, hypothesis tests and Markov chains (HL) Revision Notes
Condensed IB Maths AI HL revision notes on survey design, χ² df, SSres and R², z, t, binomial and Poisson tests and Markov chains, with a self-test.
- Level
- IB
- Topic
- Data collection, non-linear regression, hypothesis tests and Markov chains (HL)
- Author
- Marlbridge Academic Team
- Updated
- Reviewed by
- Muhammad Ghazali Siddiqui (what this means)
Aligned to International Baccalaureate IB Diploma Programme Mathematics: Applications and Interpretation (DP Mathematics: Applications and Interpretation), First assessments for SL and HL—2021. Official subject brief .
Syllabus page (what it covers and how it is assessed): IB Diploma Programme Mathematics: Applications and Interpretation.
Syllabus points this page covers
DP Mathematics: Applications and Interpretation
- 4.12 Design of valid data collection methods; reliability and validity tests (AHL only)
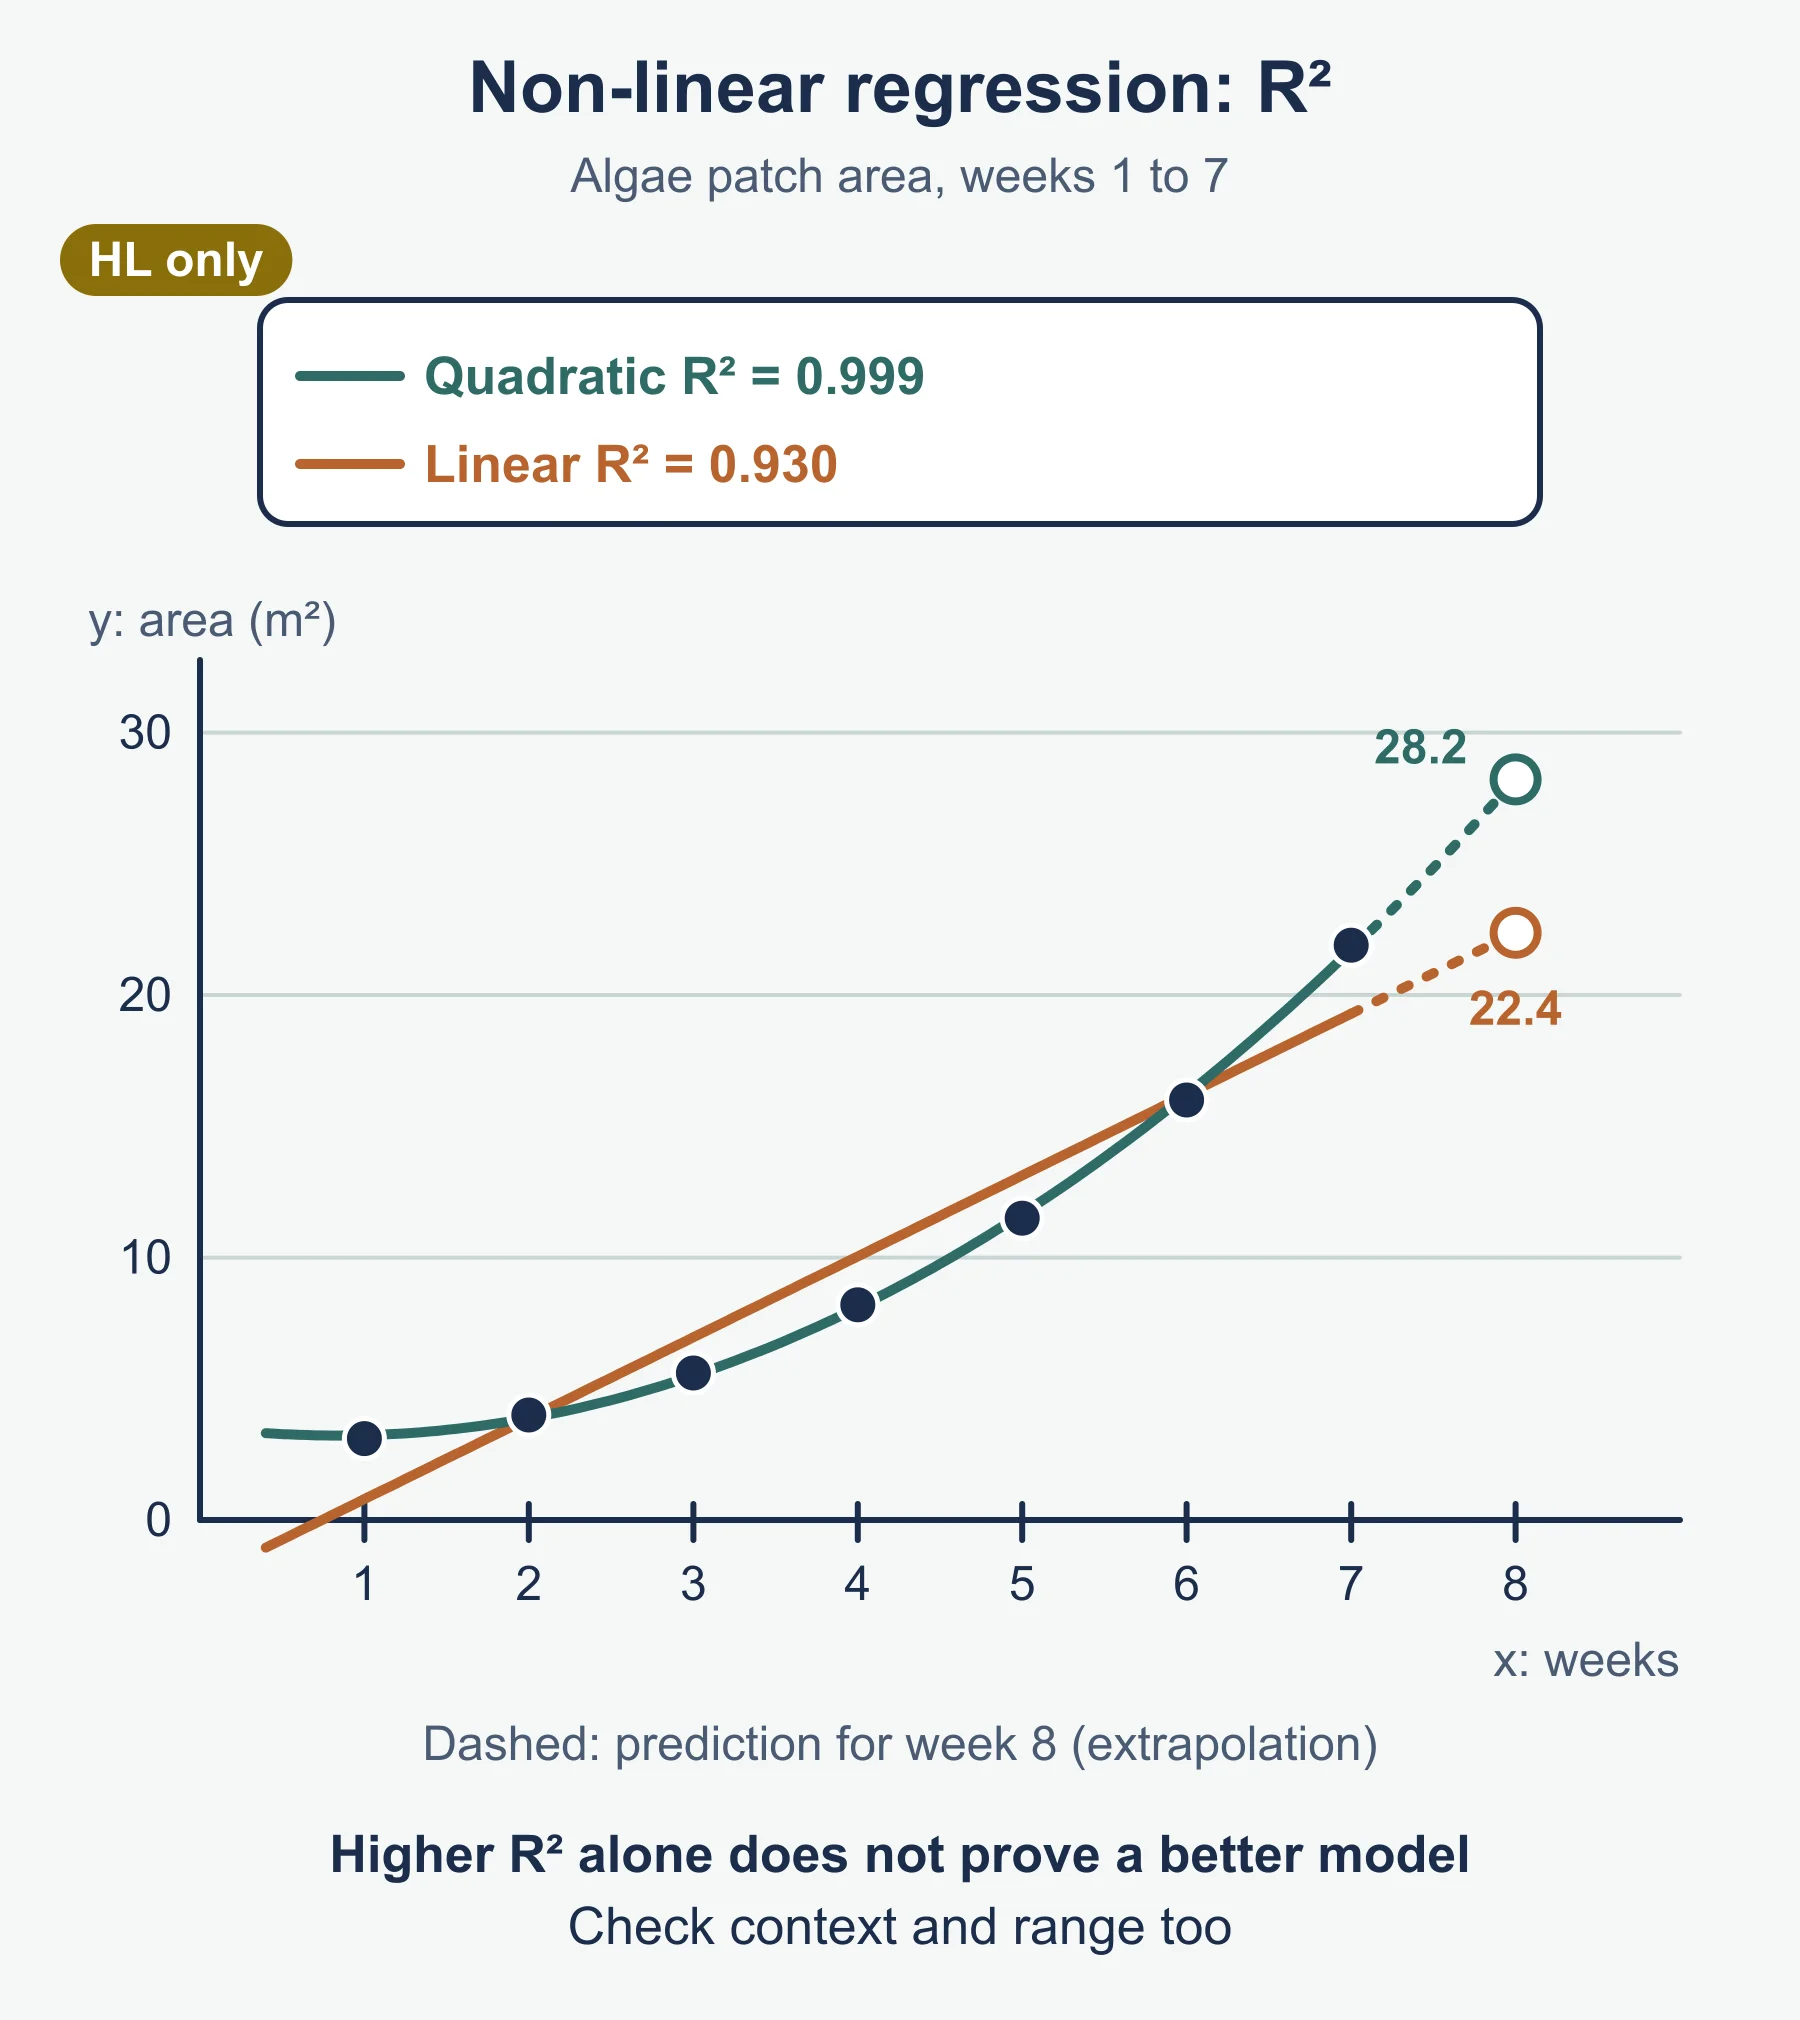
- 4.13 Non-linear regression; sum of square residuals; coefficient of determination R² (AHL only)
- 4.18 Critical values/regions; hypothesis tests for mean, proportion and correlation; Type I and II errors (AHL only)
- 4.19 Transition matrices, regular Markov chains, steady-state and long-term probabilities (AHL only)
Found an error? Report a correction.
Need help with this topic? Request a free trial class for IB Diploma Programme Mathematics: Applications and Interpretation (DP Mathematics: Applications and Interpretation).
For full explanations and longer worked examples, use the study guide for this unit.
These revision notes cover one HL unit of IB Diploma Programme Mathematics: Applications and Interpretation. They are aligned to the IB Mathematics: applications and interpretation guide, first assessment 2021, syllabus sections 4.12, 4.13, 4.18 and 4.19, and all of it is HL only (AHL). The notes follow the IB guide for first assessment 2021, which remains the examined syllabus until the new course is first assessed in May 2029, so they apply to the May and November 2026, 2027 and 2028 HL sessions. All three HL papers require a GDC.
When you are ready, test yourself with the practice questions. The IB DP Maths AI course hub and the printable syllabus checklist show the whole course. The SL tests these notes build on are in the statistics and probability guide.
Definitions
Data collection (4.12)
- Biased question: wording leads towards an answer. Unbiased: neutral wording.
- Personal question: sensitive (income, health). Risk of refusal or dishonest answers.
- Unstructured question: open answer. Structured question: fixed, consistent answer choices.
- Precise question: clear time frame, units and categories that do not overlap.
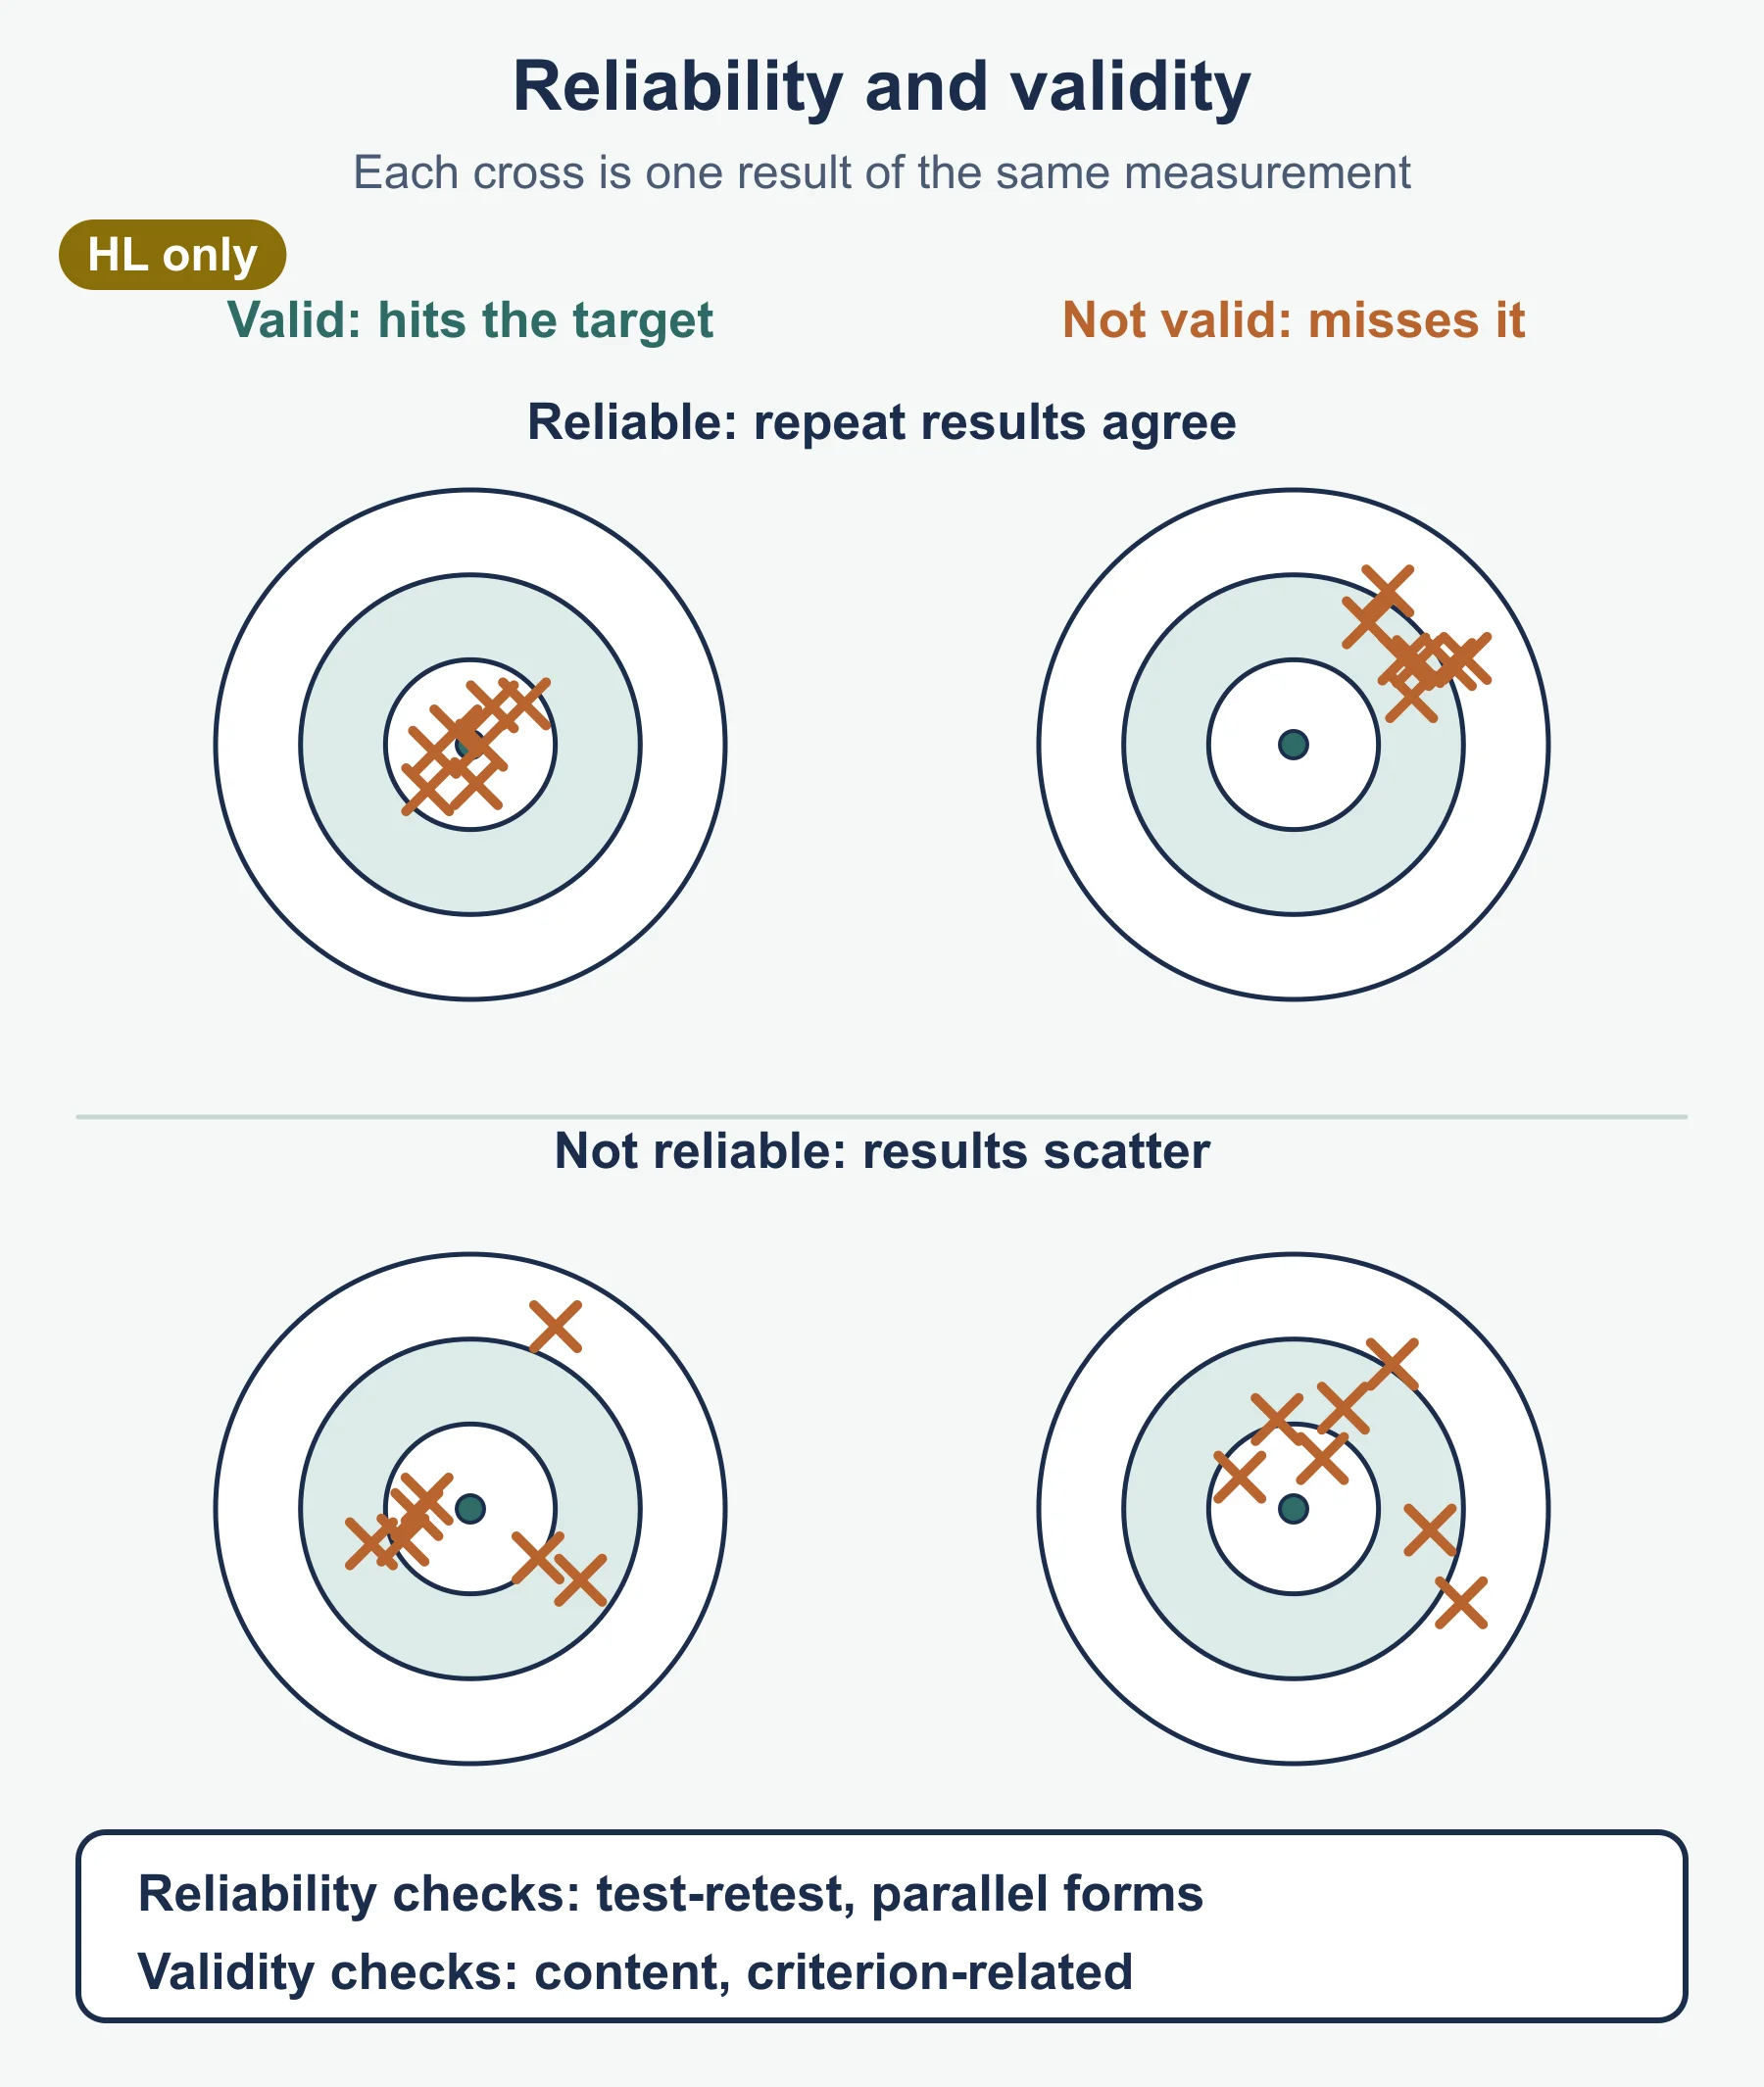
- Reliability: the method gives consistent results when repeated.
- Test-retest: same test, same group, two different times.
- Parallel forms: two equivalent versions of the test, same group.
- Validity: the method measures what it claims to.
- Content validity: the questions cover every part of what is measured.
- Criterion-related validity: results agree with an established measure.
Regression (4.13)
- Residual = observed y − predicted y.
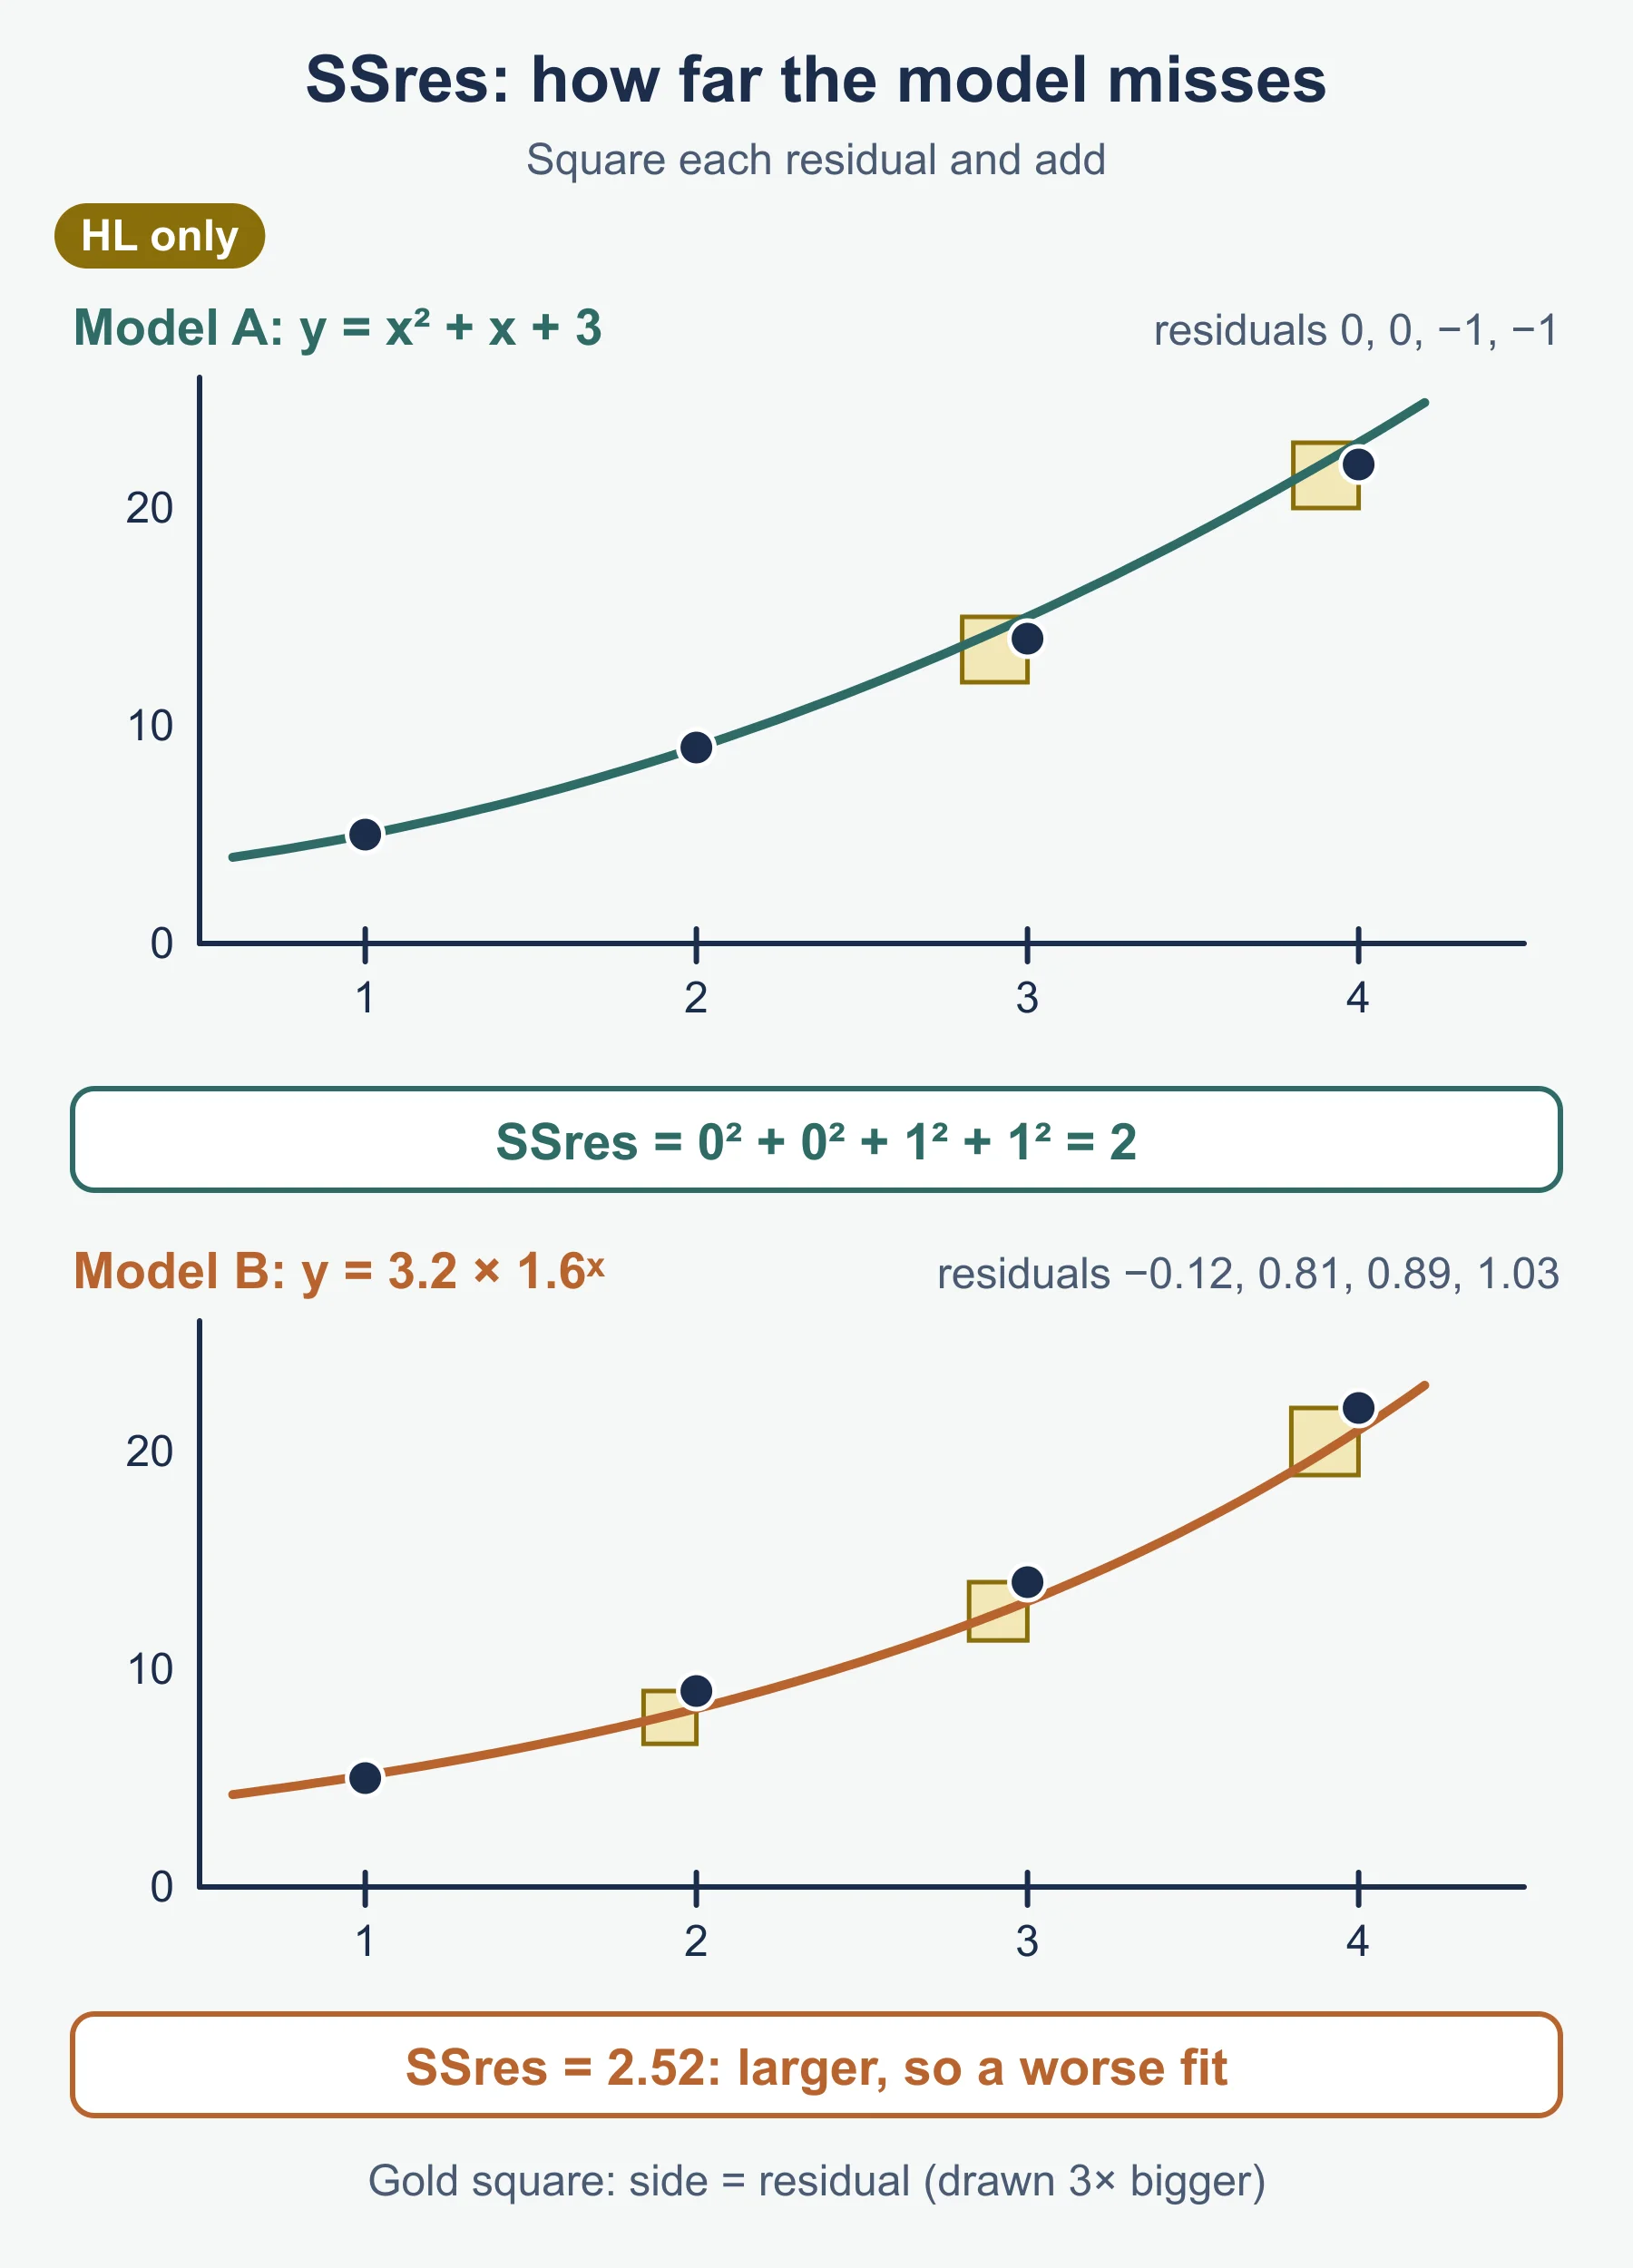
- SSres: sum of the squared residuals. Smaller means a closer fit.
- R²: proportion of the variability in y accounted for by the model. 0 ≤ R² ≤ 1.
- Models in examinations: linear, quadratic, cubic, exponential, power, sine.
Hypothesis tests (4.18)
- Critical region: values of the test statistic that lead to rejecting H₀. Critical value: its boundary.
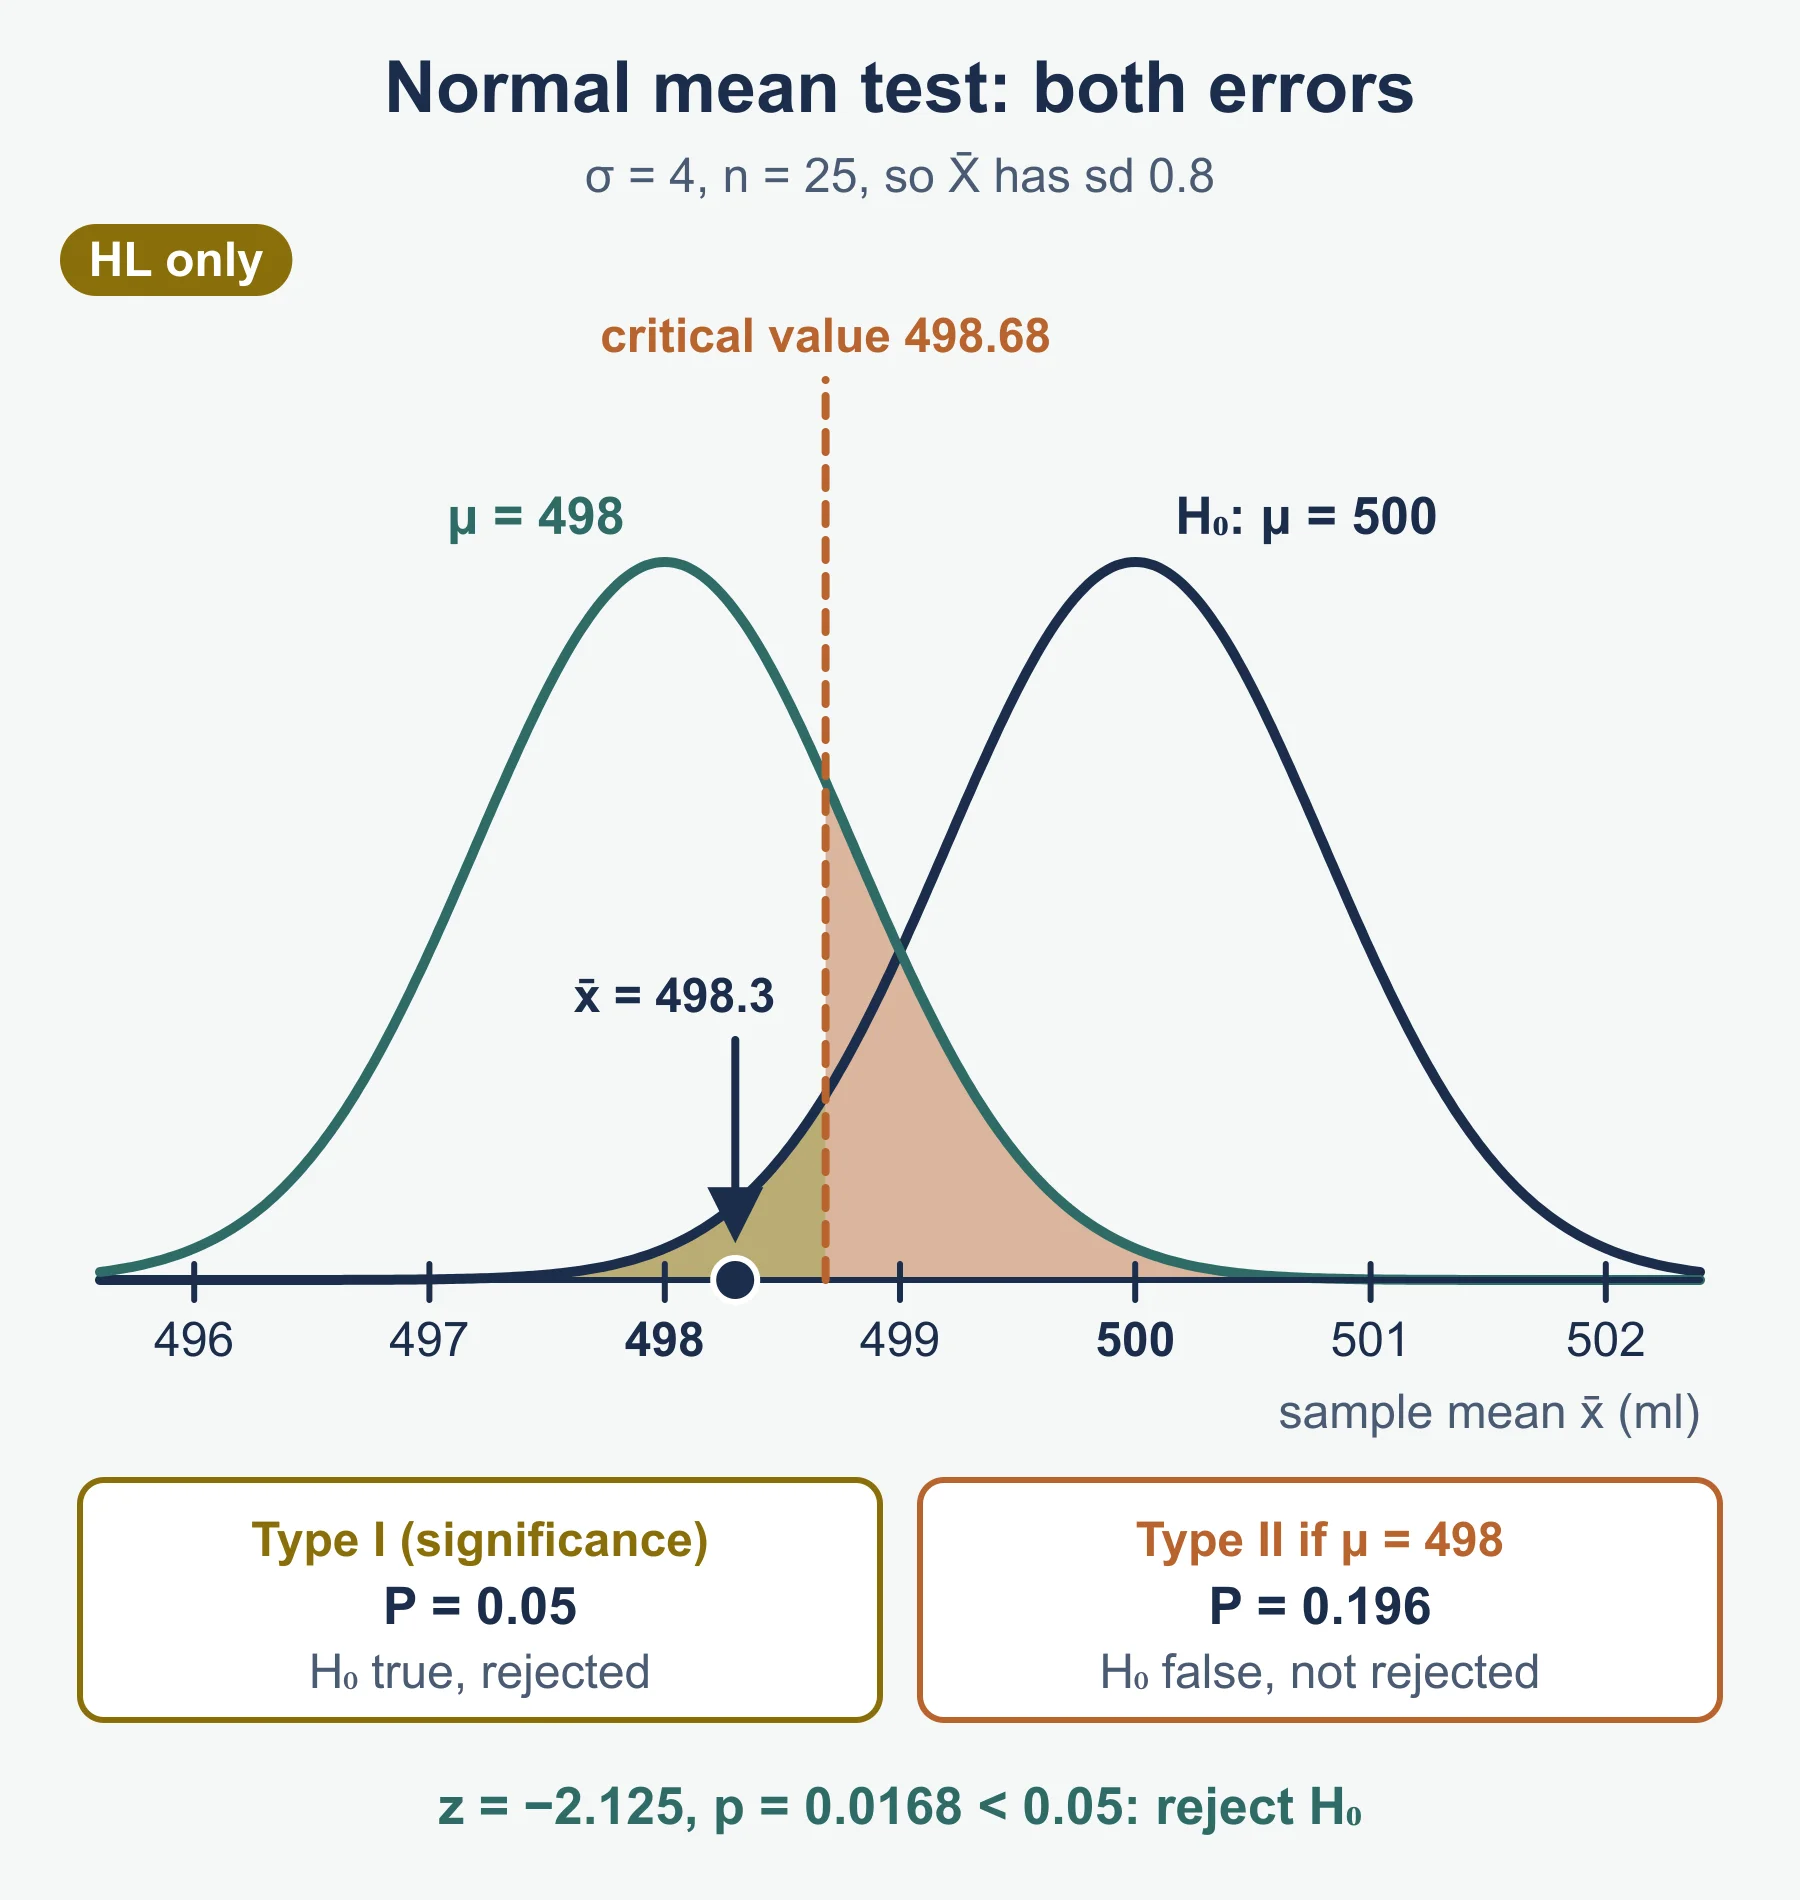
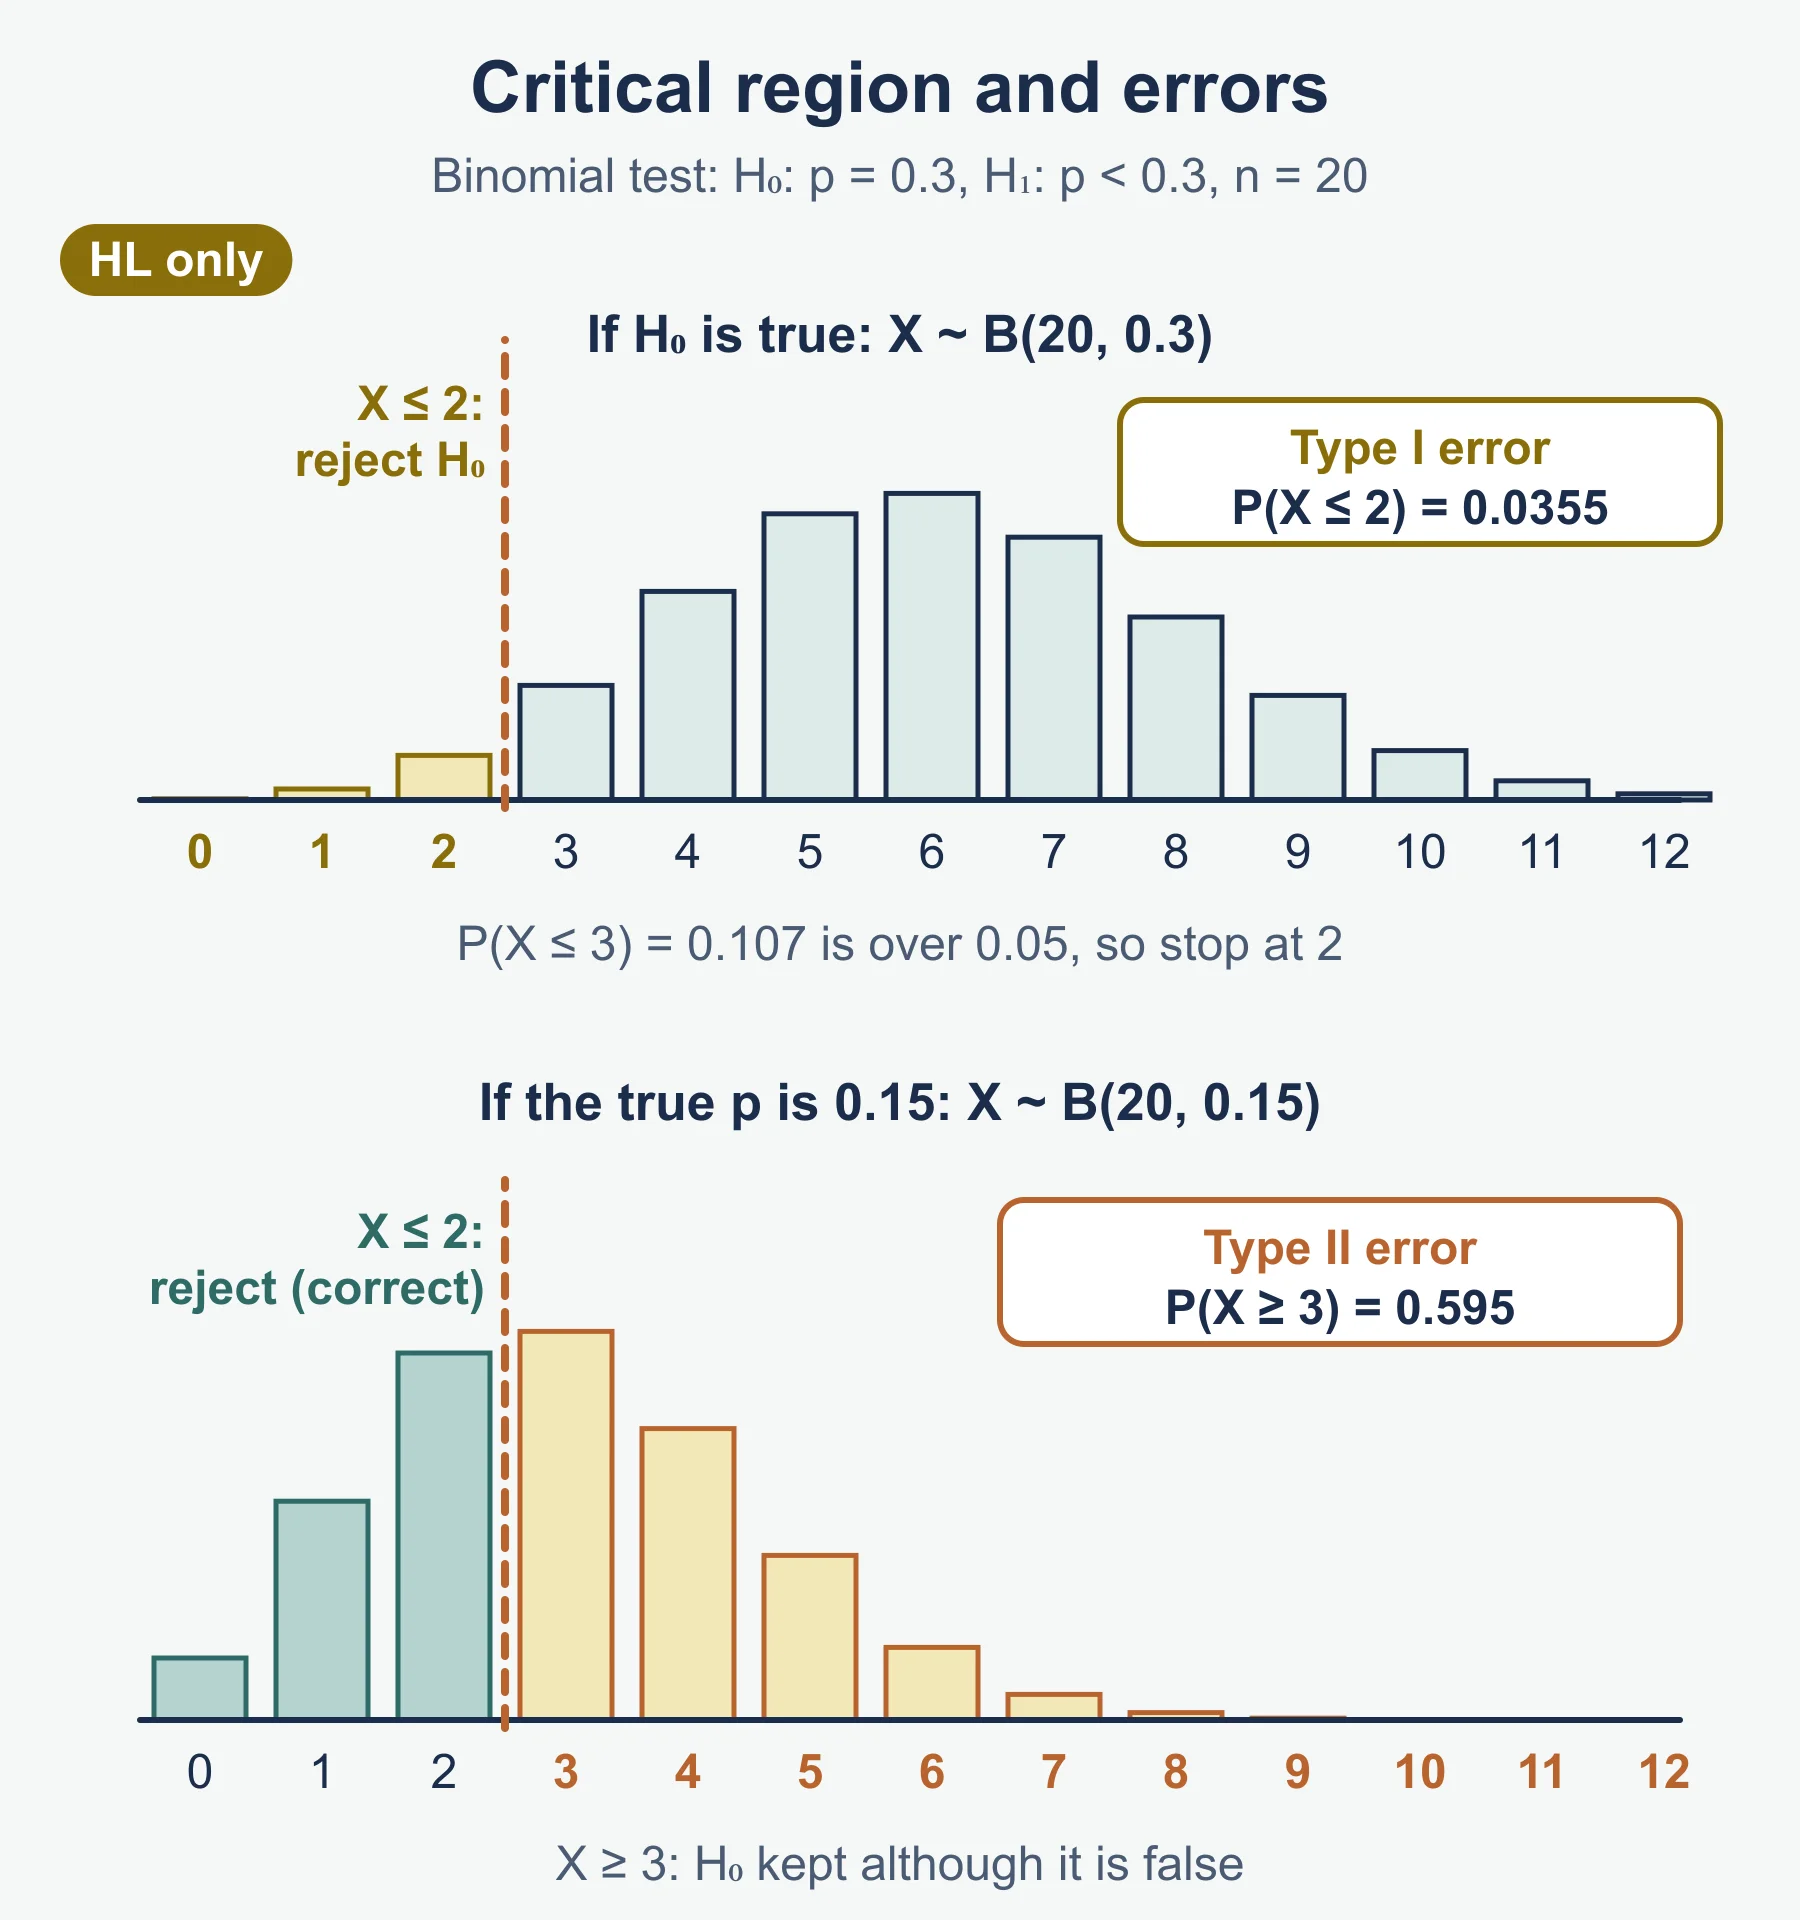
- Type I error: reject H₀ when H₀ is true.
- Type II error: accept H₀ when H₀ is false.
Markov chains (4.19)
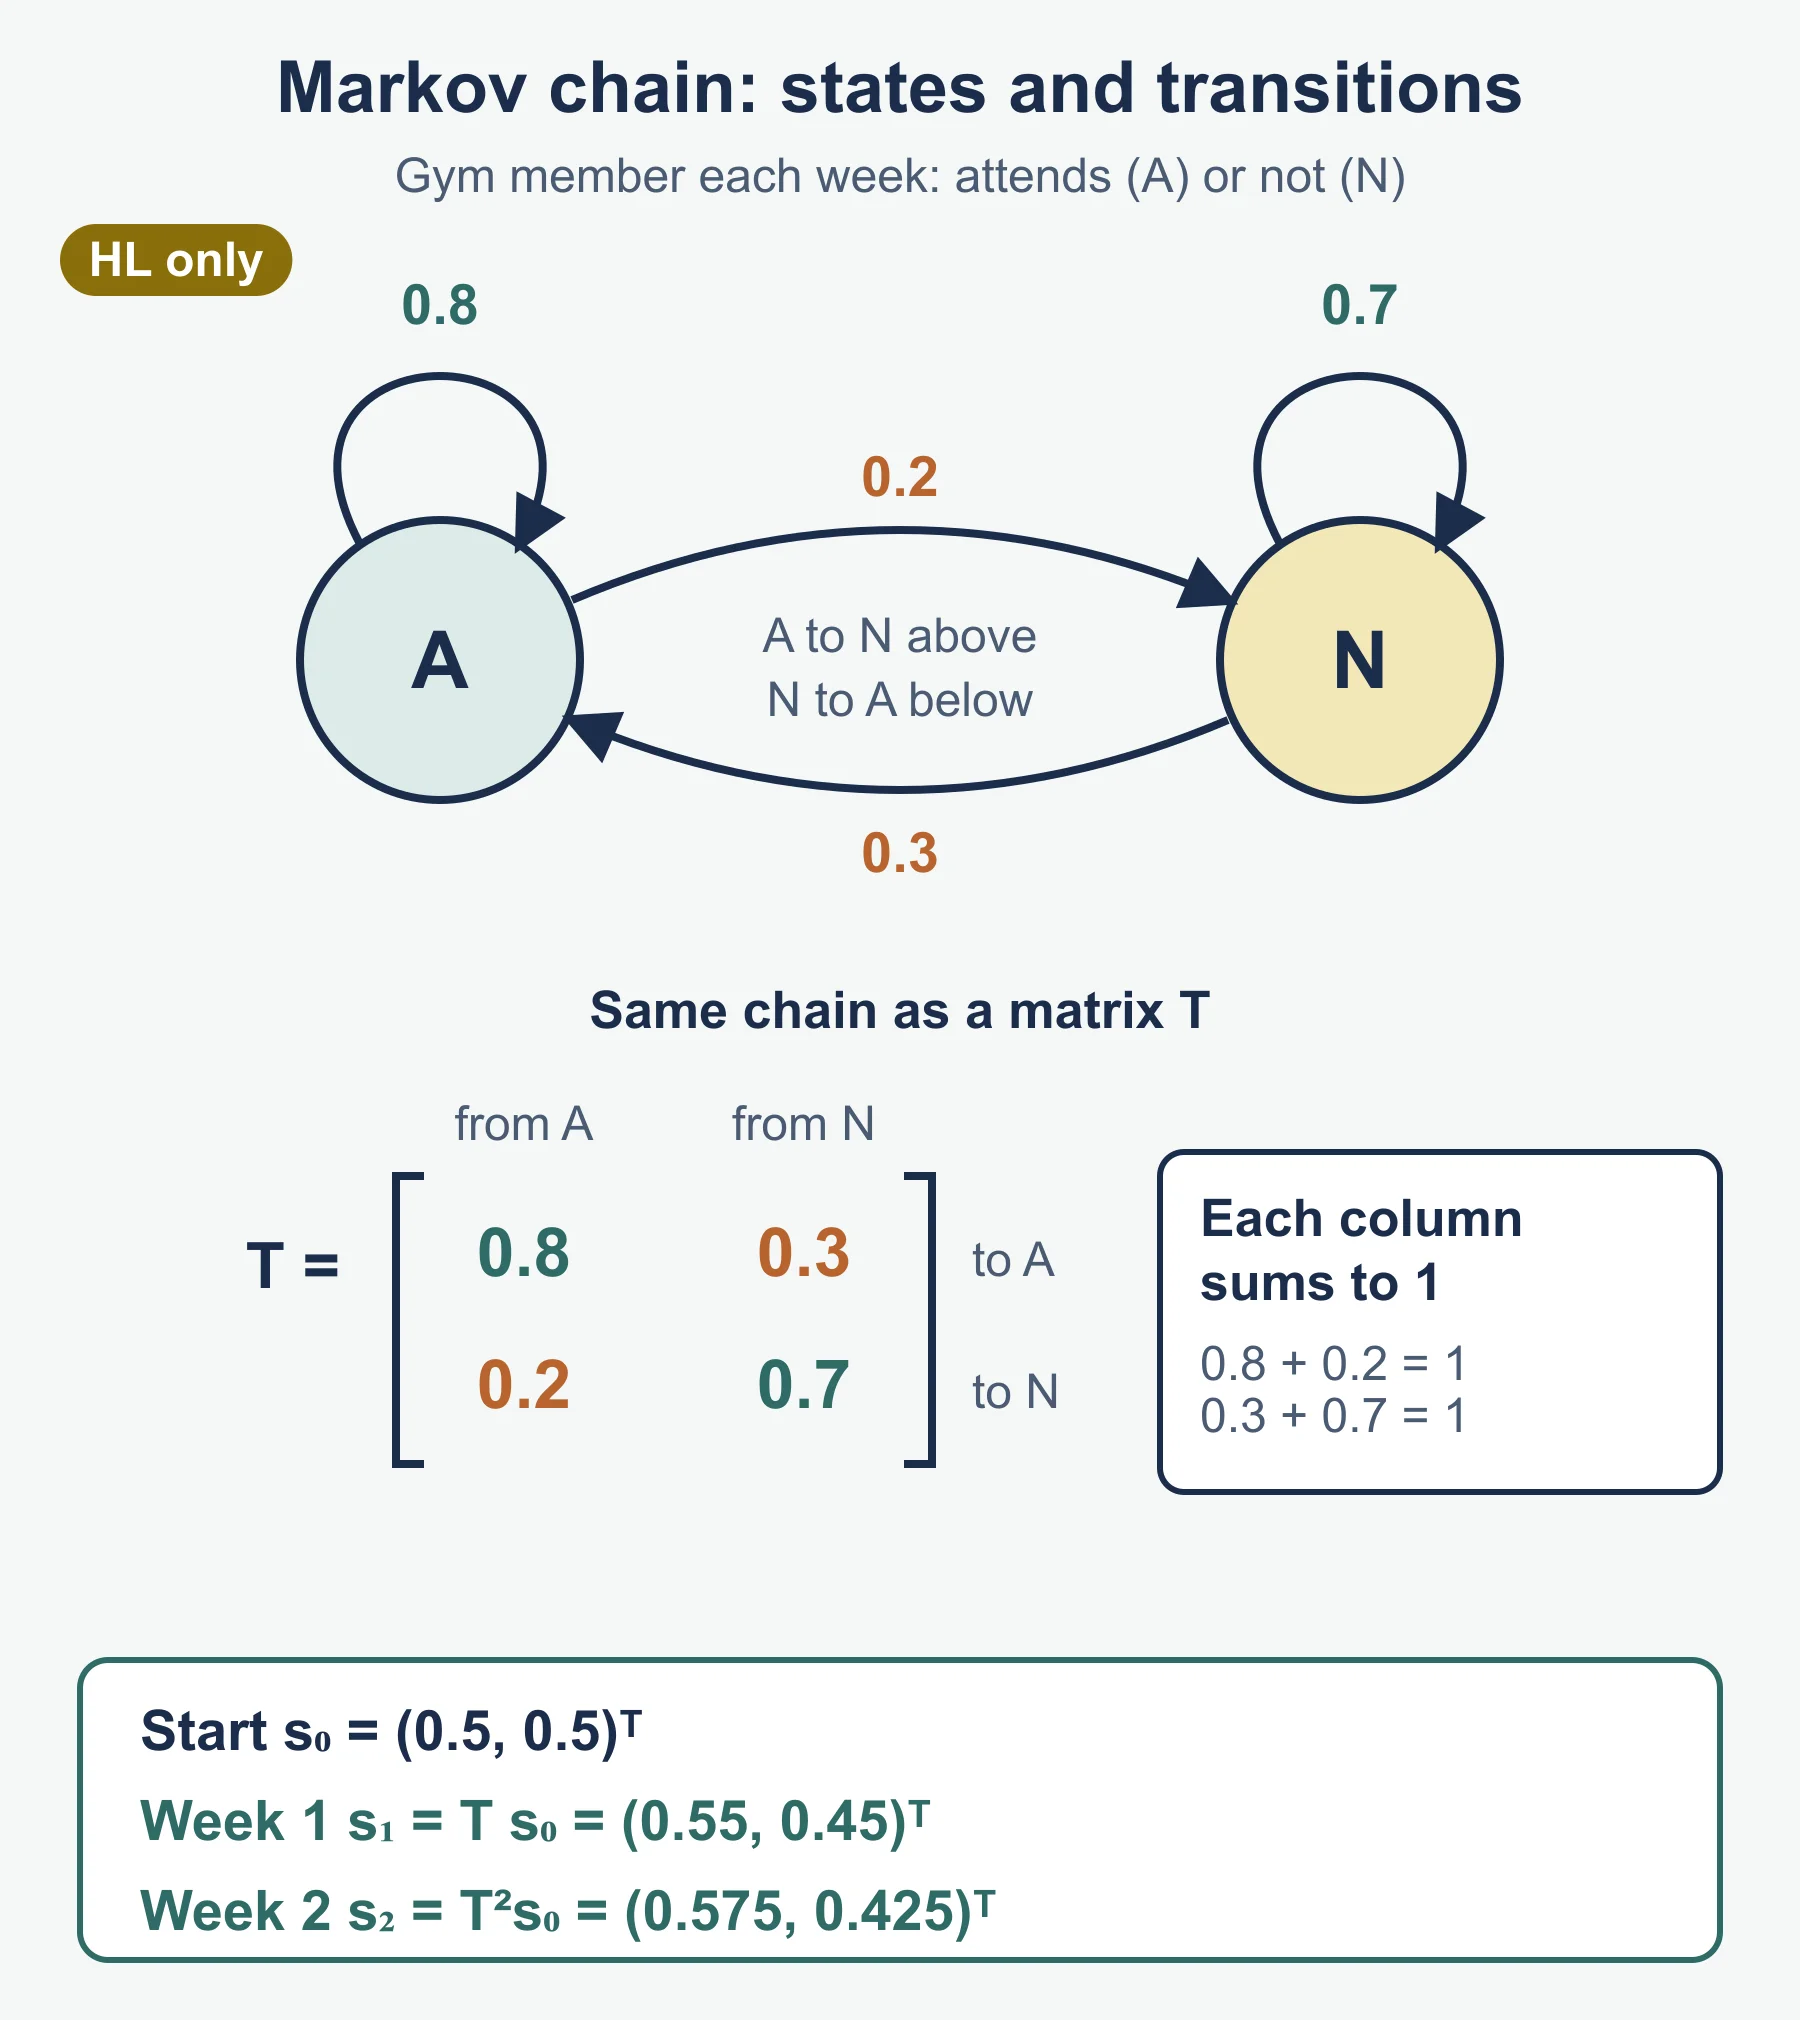
- Transition matrix T: Tᵢⱼ = P(moving from state j to state i). Columns sum to 1.
- Initial state matrix s₀: column of starting probabilities.
- Regular chain: some power of T has all entries positive.
- Steady state s: Ts = s, entries sum to 1. It is the eigenvector for eigenvalue 1, scaled so its entries add to 1.
Formulas
| Result | Formula |
|---|---|
| χ² goodness of fit df | categories − 1 − parameters estimated |
| Sum of square residuals | SSres = Σ(yᵢ − ŷᵢ)² |
| Linear model only | R² = r² |
| Sample mean (normal population) | X̄ ~ N(μ, σ²/n) |
| z statistic | z = (x̄ − μ)/(σ/√n) |
| State after n steps | sₙ = Tⁿs₀ |
| Steady state | Ts = s, sum of entries = 1 |
| Normal test, σ known | P(Type I) = significance level |
Method in steps
χ² goodness of fit with estimated parameters
- State H₀ (the data fit the named distribution) and H₁.
- Estimate the parameter(s) from the data, for example the mean for a Poisson model.
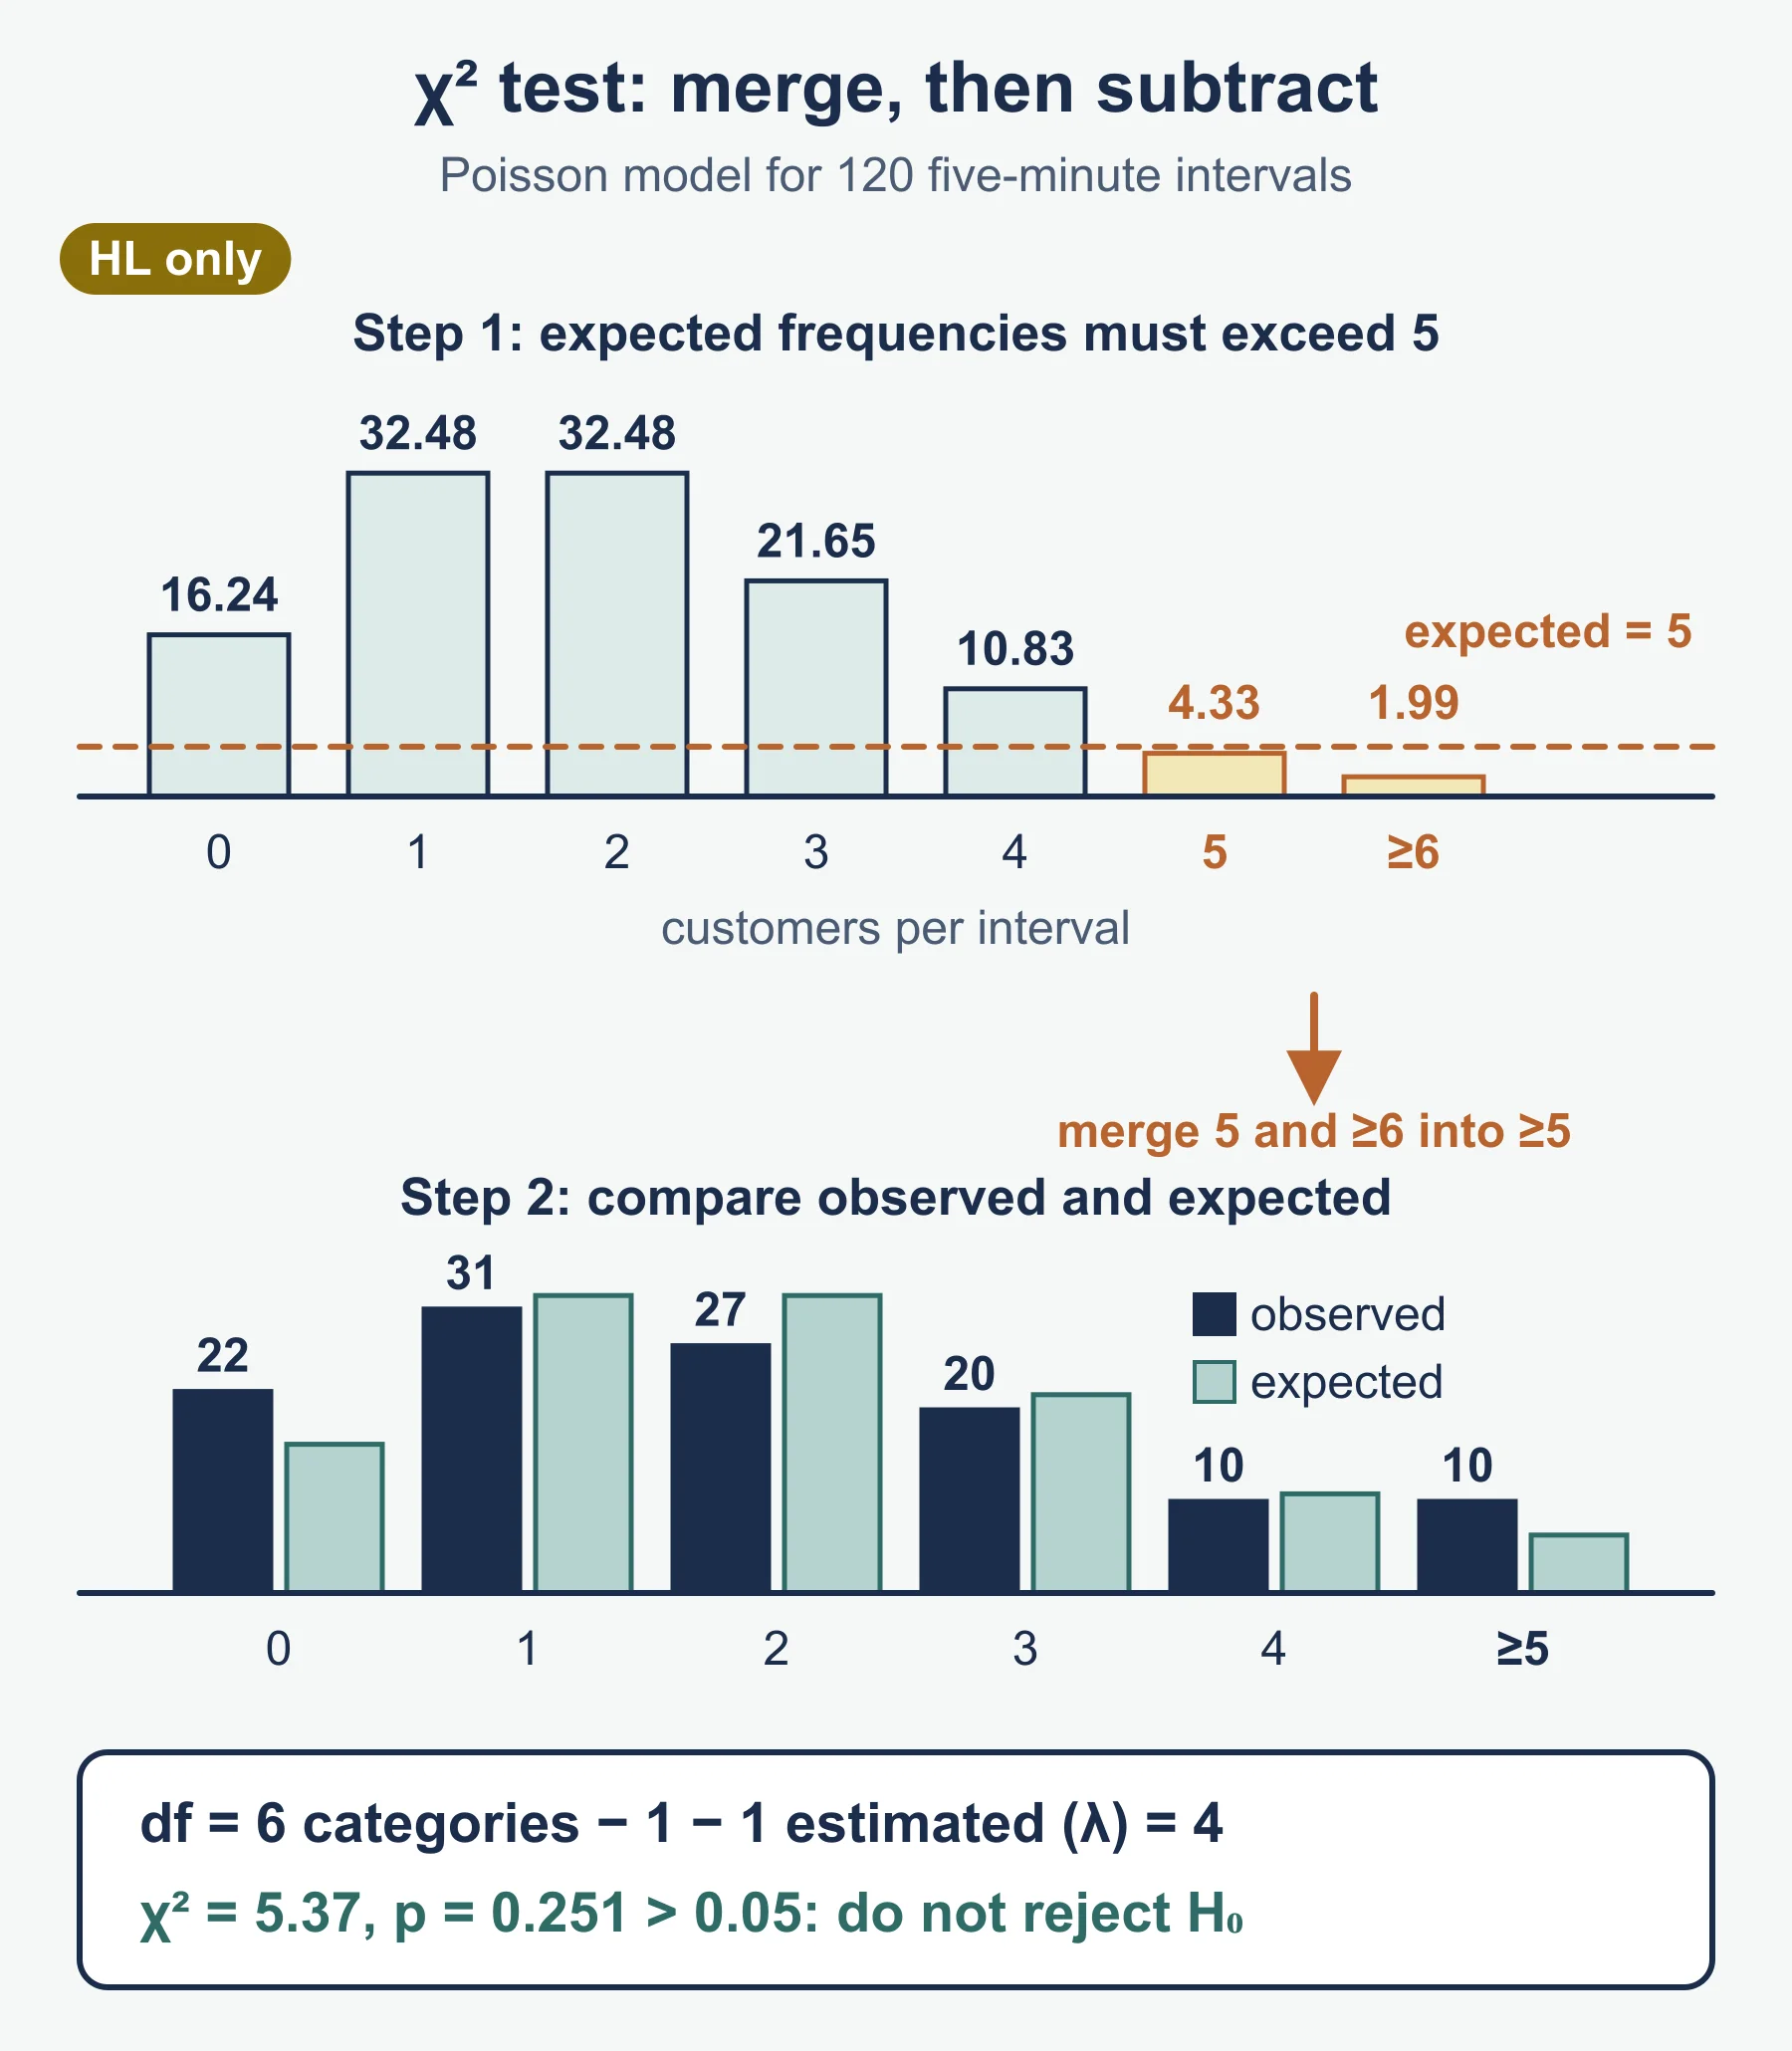
- Find the expected frequencies. Merge neighbouring categories until every expected frequency is greater than 5.
- df = categories − 1 − parameters estimated.
- Use technology for χ² and the p-value, setting df yourself. Compare with the significance level and conclude in context.
Discrete critical region (binomial or Poisson, one-tailed)
- Write H₀, H₁ and the distribution under H₀.
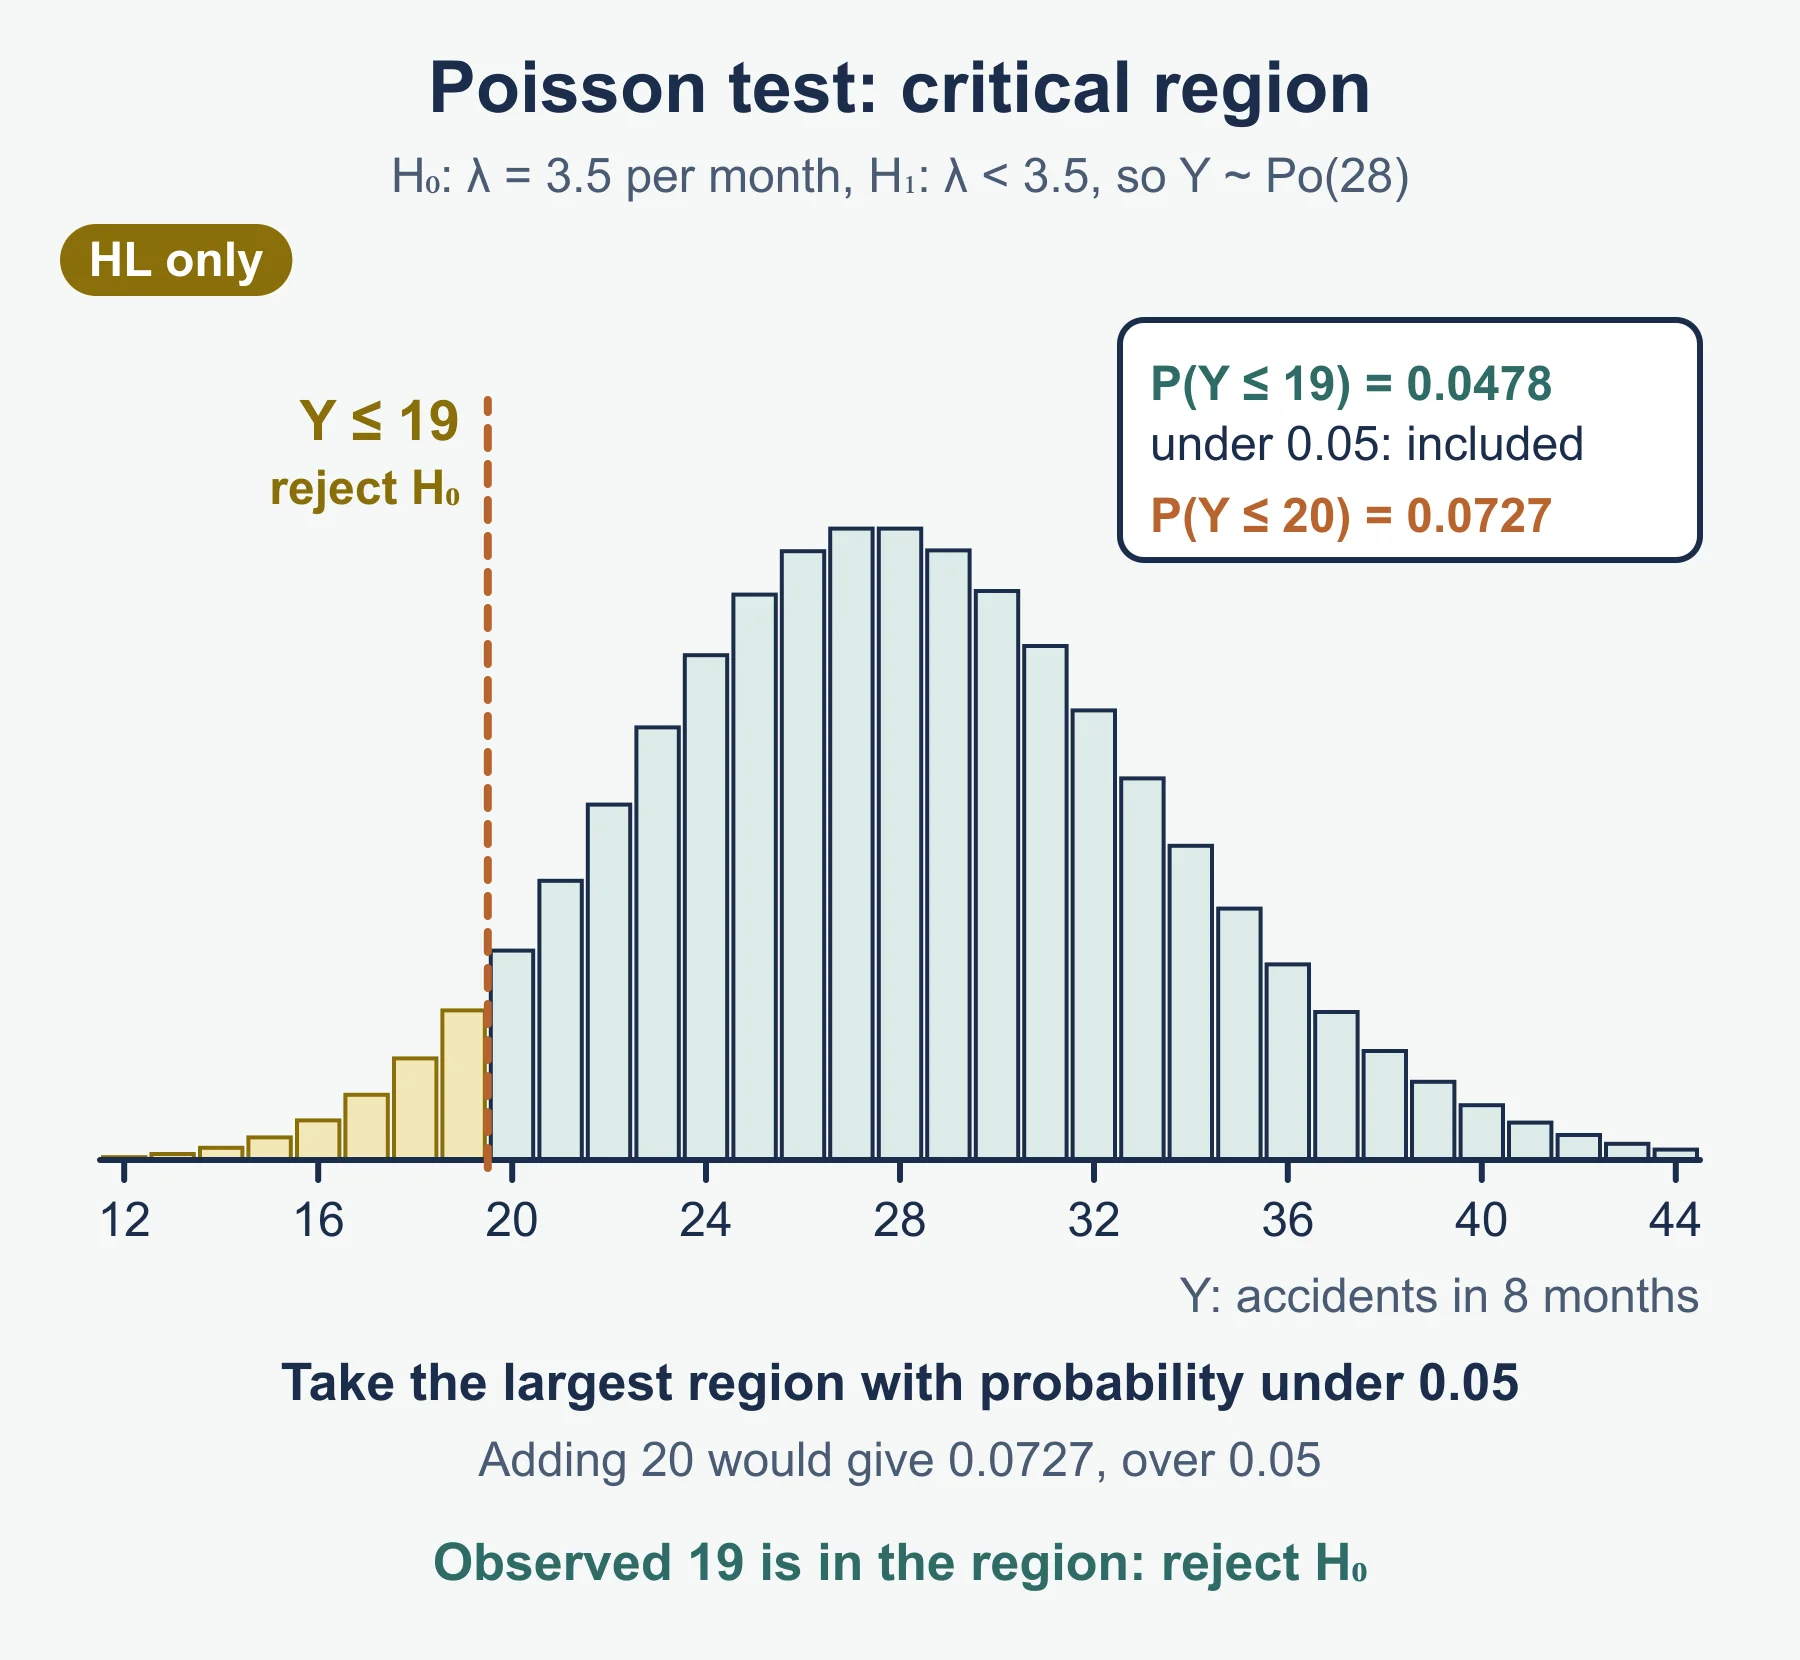
- For H₁: p < p₀, find the largest c with P(X ≤ c) below the significance level. For H₁: p > p₀, find the smallest c with P(X ≥ c) below it.
- State the critical region and quote the probability either side of c.
- P(Type I) = P(X in critical region | H₀).
- P(Type II) = P(X not in critical region | the stated true value).
Normal mean test
- σ known → z-test. σ unknown → t-test, whatever the sample size.
- Matched pairs: find the differences, then do a one-sample test on them.
- Quote the statistic and p-value, compare, and conclude in context.
Steady state by equations
- Write Ts = s as equations. Drop one (they are dependent).
- Add the equation “entries sum to 1”.
- Solve. Give exact fractions if the question asks for them.
Small worked reminders
- Merging: Po(2) with n = 120 gives expected 4.33 for x = 5 and 1.99 for x ≥ 6. Merge them into “≥ 5” (6.32).
- df: a normal model with μ and σ estimated and 6 categories after merging has df = 6 − 1 − 2 = 3.
- SSres: model y = x² + x + 3 on (1, 5), (2, 9), (3, 14), (4, 22) gives residuals 0, 0, −1, −1, so SSres = 2.
- Binomial: H₀: p = 0.3, H₁: p < 0.3, n = 20, 5%. P(X ≤ 2) = 0.0355 and P(X ≤ 3) = 0.107, so the critical region is X ≤ 2.
- Poisson over time: 3.5 per month for 8 months → Po(28) for the total.
- Markov: T with columns (0.8, 0.2) and (0.3, 0.7), s₀ = (0.5, 0.5)ᵀ gives s₁ = (0.55, 0.45)ᵀ. The steady state is (3/5, 2/5)ᵀ.
Must-know distinctions
- Reliability vs validity: consistent vs measuring the right thing. A scale that always reads 2 kg heavy is reliable but not valid.
- Test-retest vs parallel forms: same test twice vs two equivalent versions.
- Content vs criterion-related validity: covers the whole topic vs agrees with an established measure.
- SSres vs R²: SSres depends on the units of y. R² is a proportion, so it has no units.
- R² vs r: R² = r² only for a linear model. r has a sign; R² does not.
- z vs t: σ known vs σ unknown.
- Continuous vs discrete tests: for the normal test P(Type I) equals the significance level. For binomial and Poisson tests it is at most the significance level.
- Type I vs Type II: wrongly reject vs wrongly accept H₀.
- Row vs column convention: IB uses columns summing to 1 and sₙ = Tⁿs₀ with s₀ a column.
Quick self-test
- After merging there are 7 categories, and a binomial p was estimated from the data. Find the degrees of freedom.
- What is wrong with the question “Do you exercise rarely, sometimes or often?” How would you fix it?
- A class sits the same test twice, a month apart, and the scores are compared. Which reliability test is this?
- A linear model has r = −0.85. Find R² and interpret it.
- A model’s residuals are 0.3, −0.5, 0.1 and 0.4. Find SSres.
- X ~ N(μ, 6²). A sample of 16 has x̄ = 53.2. Test H₀: μ = 50 against H₁: μ > 50 at 5%.
- Write down the critical value for an upper-tailed z-test at the 1% level.
- Under H₀, X ~ B(15, 0.4), with H₁: p < 0.4 at 5%. Find the critical region and P(Type I).
- Under H₀, X ~ Po(9), with H₁: λ > 9 at 5%. Find the critical region and P(Type I).
- T has columns (0.9, 0.1) and (0.4, 0.6), and s₀ = (0, 1)ᵀ. Find s₁.
- For the T in question 10, find the exact steady state.
Answers
- df = 7 − 1 − 1 = 5.
- The categories are vague and mean different things to different people. Ask “How many times did you exercise last week?” with ranges that do not overlap (0, 1–2, 3–4, 5 or more).
- Test-retest.
- R² = 0.85² = 0.7225. About 72% of the variability in y is accounted for by the linear model.
- 0.09 + 0.25 + 0.01 + 0.16 = 0.51.
- z = (53.2 − 50)/(6/4) = 2.13, p = 0.0164 < 0.05. Reject H₀: there is evidence that μ > 50.
- 2.33 (2.326).
- P(X ≤ 2) = 0.0271 < 0.05 and P(X ≤ 3) = 0.0905 > 0.05. Critical region X ≤ 2, and P(Type I) = 0.0271.
- P(X ≥ 15) = 0.0415 < 0.05 and P(X ≥ 14) = 0.0739 > 0.05. Critical region X ≥ 15, and P(Type I) = 0.0415.
- s₁ = T s₀ = (0.4, 0.6)ᵀ.
- 0.1a = 0.4b with a + b = 1, so s = (4/5, 1/5)ᵀ.
Where marks are usually lost
- Merging χ² categories because of a small observed frequency instead of a small expected one.
- Leaving df as categories − 1 after estimating a mean or proportion from the data.
- Defining reliability and validity the wrong way round, or naming a test without saying what it compares.
- Choosing a model on R² alone, with no comment on context or extrapolation.
- Giving R² as a percentage without saying “of the variability in y”.
- Using a z-test with a sample standard deviation.
- Stating a discrete critical region without the probabilities that justify c.
- Finding P(Type II) with the H₀ parameter instead of the stated true value.
- Writing T with rows summing to 1, or finding s₀T instead of Ts₀.
- Giving a decimal steady state when the question asks for an exact answer.
Frequently asked questions
How many degrees of freedom are there in a χ² goodness of fit test with estimated parameters? Degrees of freedom = number of categories after merging − 1 − number of parameters estimated from the data. Estimating a Poisson mean costs 1, and estimating a normal μ and σ costs 2.
What is the difference between reliability and validity? Reliability means the method gives consistent results when repeated, while validity means it measures what it claims to measure. A scale that always reads 2 kg heavy is reliable but not valid.
What is the difference between a Type I and a Type II error? A Type I error is rejecting H₀ when H₀ is true. A Type II error is accepting H₀ when H₀ is false.
Is R² the same as r²? Only for a linear model. R² is the proportion of the variability in y accounted for by any fitted model and has no sign, while Pearson’s r has a sign and applies to linear relationships.
Official syllabus
International Baccalaureate Organization, Diploma Programme, Mathematics: applications and interpretation guide, first assessment 2021, syllabus sections AHL 4.12, 4.13, 4.18 and 4.19.
Get free revision emails (optional)
Occasional emails with practice questions, worked explanations and links to free resources for the qualification and subjects you choose. No spam, and you can unsubscribe from any email. The free tools on this site never need an email.
Related resources
-
Study guides
IB DP Mathematics: Applications and Interpretation – Data collection, non-linear regression, hypothesis tests and Markov chains (HL) Study Guide
IB Maths AI HL study guide: data collection, reliability and validity, non-linear regression and R², hypothesis tests, Type I/II errors, Markov chains.
Mathematics: Applications and Interpretation · International Baccalaureate · IB
Read guide -
Practice questions
IB DP Mathematics: Applications and Interpretation – Data collection, non-linear regression, hypothesis tests and Markov chains (HL) Practice Questions
12 original IB Maths AI HL questions on survey design, χ² tests, regression, hypothesis tests and Markov chains, with mark-by-mark worked answers.
Mathematics: Applications and Interpretation · International Baccalaureate · IB
Try questions -
Study guides
IB DP Mathematics: Applications and Interpretation – Differential equations, slope fields, Euler's method and phase portraits (HL) Study Guide
HL study guide for IB DP Maths AI differential equations: separation of variables, slope fields, Euler's method and phase portraits, worked in full.
Mathematics: Applications and Interpretation · International Baccalaureate · IB
Read guide
Related articles
-
teaching
A Level tuition in Dubai: Cambridge or Pearson Edexcel International A Level?
Schools in Dubai and Abu Dhabi teach either Cambridge International AS & A Level or Pearson Edexcel International A Level. How the two are structured, why it matters for tuition, and how online classes from Lahore work.
9 October 2026
-
curriculum guides
Choosing subjects at IGCSE and A Level
How subject choices at 14 and 16 affect university options later, and how to keep pathways open without overloading a timetable.
28 July 2026
Studying this with a teacher
Working through Mathematics: Applications and Interpretation IB?
This page is free and stays free. If you would rather be taught it, Marlbridge runs Mathematics: Applications and Interpretation classes one-to-one, online in your own time zone. The first trial class is free. WhatsApp replies within an hour (8am–11pm Pakistan time, every day); email the same day.
IB Mathematics: Applications and Interpretation teachers at Marlbridge

