
Study Guides
IB DP Mathematics: Applications and Interpretation – Sampling, data presentation and summary statistics Study Guide
Study guide to sampling methods, outliers, histograms, cumulative frequency, box plots, mean and standard deviation for IB DP Maths AI SL and HL.
- Level
- IB
- Topic
- Sampling, data presentation and summary statistics
- Author
- Marlbridge Academic Team
- Updated
- Reviewed by
- Muhammad Ghazali Siddiqui (what this means)
Aligned to International Baccalaureate IB Diploma Programme Mathematics: Applications and Interpretation (DP Mathematics: Applications and Interpretation), First assessments for SL and HL—2021. Official subject brief .
Syllabus page (what it covers and how it is assessed): IB Diploma Programme Mathematics: Applications and Interpretation.
Syllabus points this page covers
DP Mathematics: Applications and Interpretation
- 4.1 Population, sample, sampling techniques, reliability and bias, interpretation of outliers
- 4.2 Presentation of data: frequency distributions, histograms, cumulative frequency graphs, box-and-whisker diagrams
- 4.3 Measures of central tendency and dispersion; effect of constant changes on data; quartiles
Found an error? Report a correction.
Need help with this topic? Request a free trial class for IB Diploma Programme Mathematics: Applications and Interpretation (DP Mathematics: Applications and Interpretation).
This study guide teaches sampling, data presentation and summary statistics for IB Diploma Programme Mathematics: Applications and Interpretation. It is aligned to the IB Mathematics: applications and interpretation guide, first assessment 2021, and covers syllabus sections 4.1, 4.2 and 4.3, which are common content for SL and HL. It follows the IB guide for first assessment 2021, which remains the examined syllabus until the new course is first assessed in May 2029, so it applies to the May and November 2026, 2027 and 2028 sessions.
Every paper in this course is “technology required”, and at SL the data set is treated as the population unless the question says otherwise. You find standard deviations on your GDC, but you must know what each statistic means.
Useful links: the course hub, the printable syllabus checklist, the revision notes for this unit and the practice questions for this unit. The statistics and probability overview gives the big picture of the strand; this page goes section by section. Correlation and regression continue in the correlation and hypothesis testing guide.
What this unit covers
| Syllabus section | What you must be able to do | SL/HL |
|---|---|---|
| 4.1 | Use the words population, sample, random sample, discrete and continuous; judge reliability of data and bias in sampling; deal with missing data and recording errors; identify and interpret outliers; describe simple random, convenience, systematic, quota and stratified sampling | SL and HL |
| 4.2 | Present data in frequency tables and histograms (equal class intervals); draw and read cumulative frequency graphs for median, quartiles, percentiles, range and IQR; draw box and whisker diagrams and use them to compare distributions | SL and HL |
| 4.3 | Find mean, median and mode; estimate the mean of grouped data with mid-interval values; state the modal class; find IQR, standard deviation and variance; describe the effect of adding or multiplying by a constant; find quartiles of discrete data | SL and HL |
Section 4.1: Populations, samples and sampling
Key words
- Population: every member of the group you want to know about.
- Sample: the members you actually collect data from.
- Random sample: every member of the population has an equal chance of being chosen.
- Discrete data: can only take separate values, usually counts (number of siblings, goals scored).
- Continuous data: can take any value in a range and is measured (time, mass, height).
Reliability and bias
A sample is biased if some members of the population are more likely to be chosen than others, so the results do not represent the population. A survey on a running club’s website about the exercise habits of a whole town is biased: people who run are over-represented.
Data can also be unreliable because of:
- missing data, such as a blank age box on a form. You can leave that response out of calculations that need age, and say so. You should not invent a value.
- recording errors, such as a height of 1.72 m typed as 172 in a list in metres. Check whether a value is possible in context before using it.
Sampling techniques
| Method | How it works | Main weakness |
|---|---|---|
| Simple random | Number the population and choose with a random number generator | Needs a full list; may miss small groups by chance |
| Convenience | Use whoever is easy to reach | Very likely to be biased |
| Systematic | Choose a random start, then every k-th member of a list | Biased if the list has a repeating pattern |
| Quota | Set a number to collect from each group, then fill it with anyone available | Not random within each group |
| Stratified | Split into groups (strata) and take a random sample from each, in proportion to group size | Needs to know the size of every group |
Worked example 1: stratified and systematic sampling
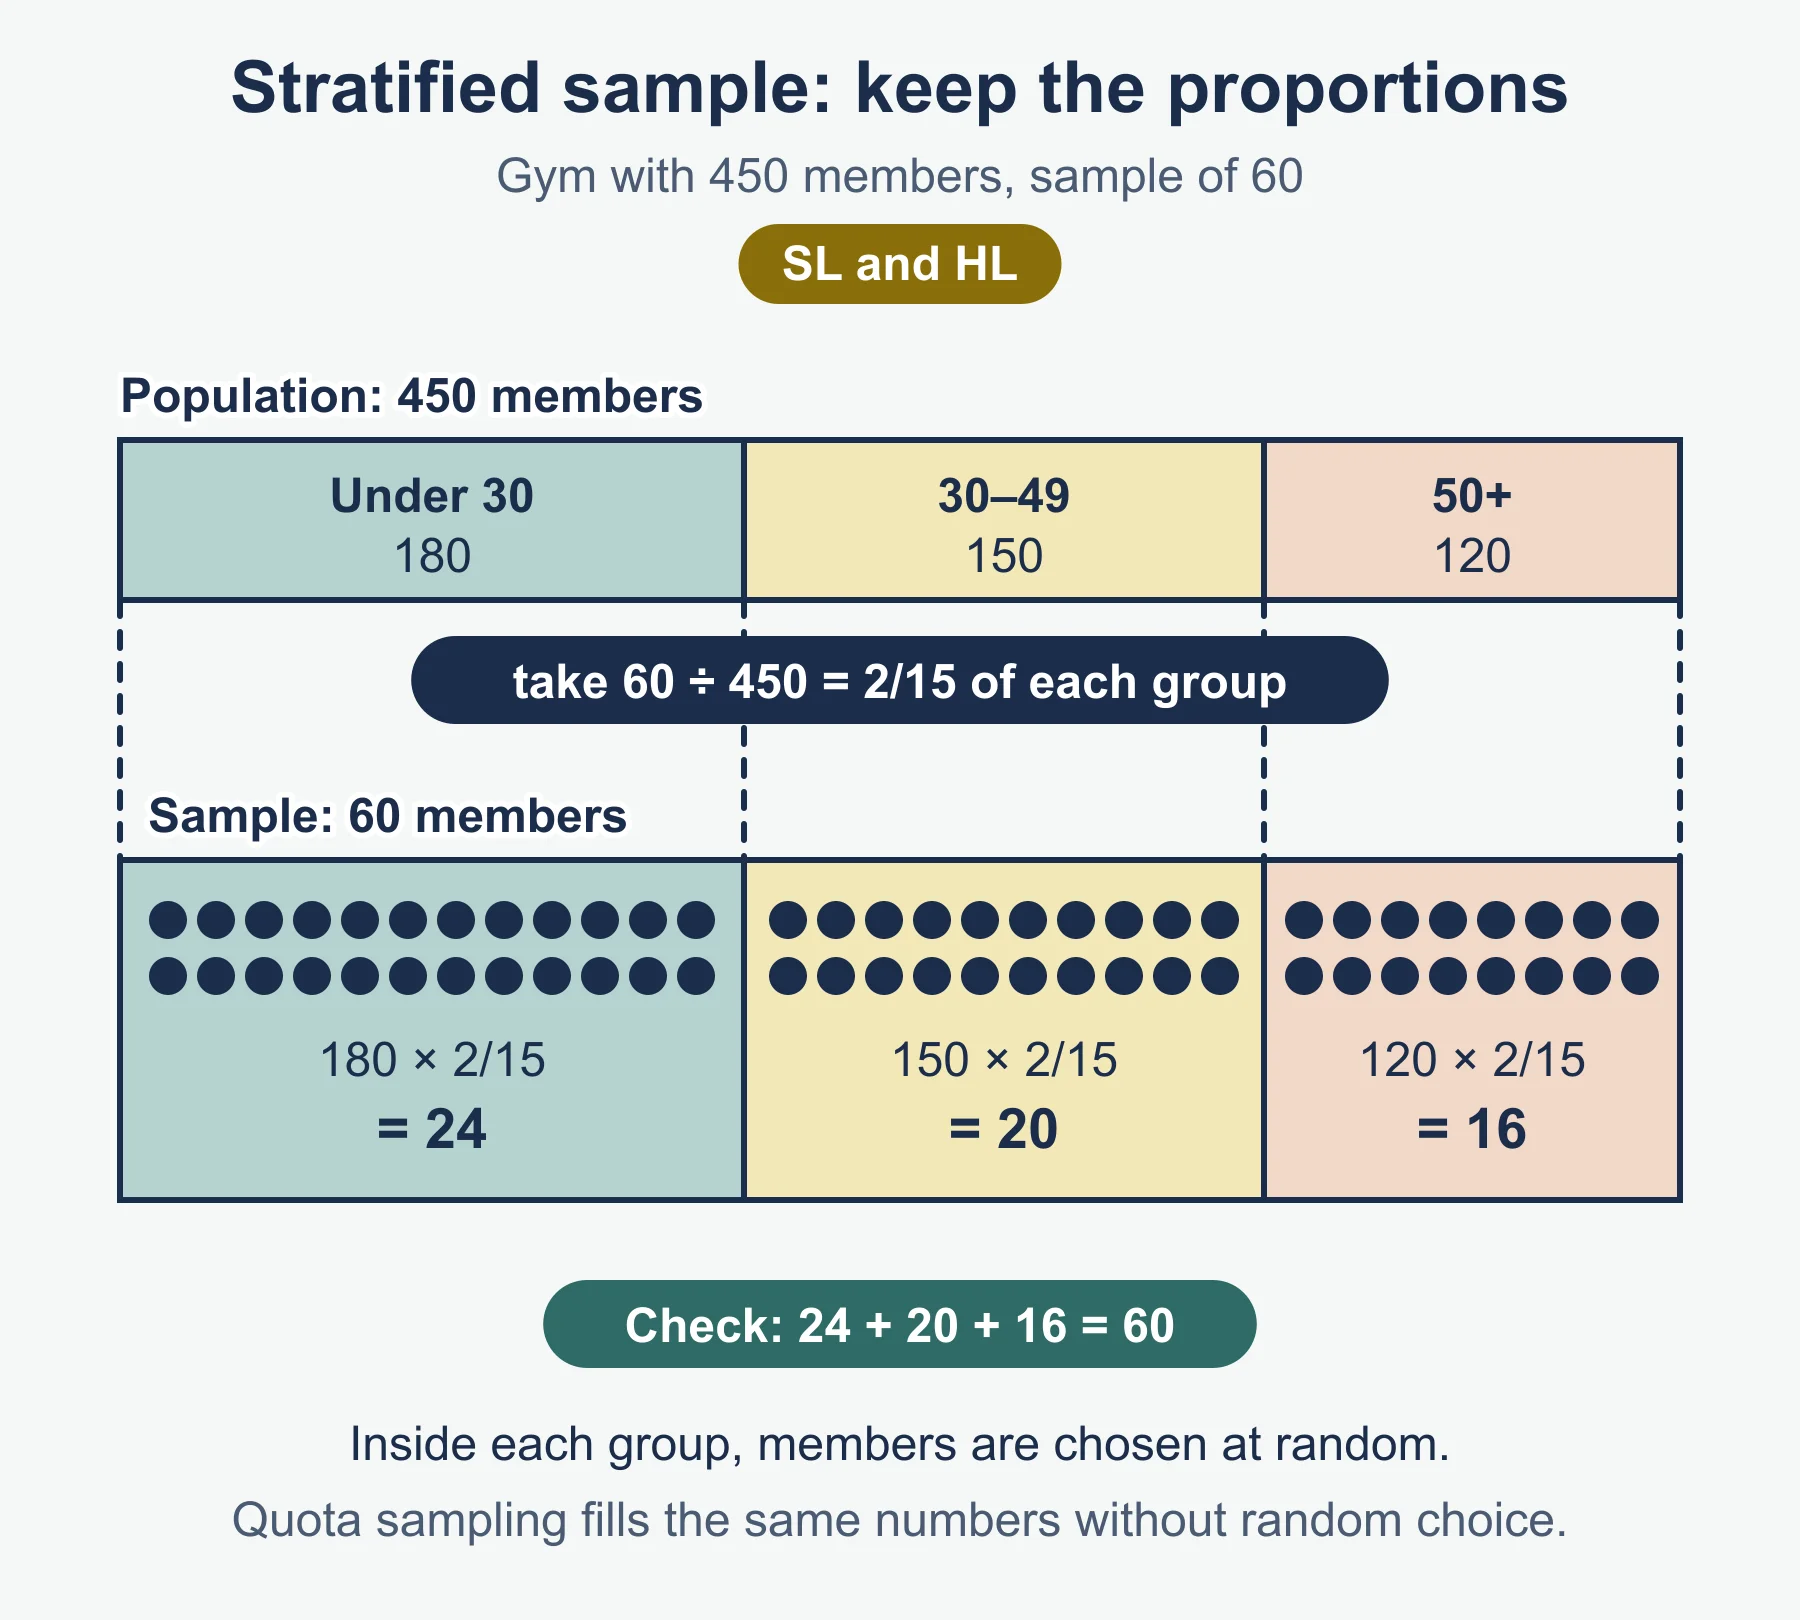
A gym has 450 members: 180 aged under 30, 150 aged 30–49 and 120 aged 50 or over. The manager wants a stratified sample of 60.
Fraction sampled = 60/450 = 2/15
Under 30:  180 × 2/15 = 24
30–49:     150 × 2/15 = 20
50+:       120 × 2/15 = 16
Check:     24 + 20 + 16 = 60
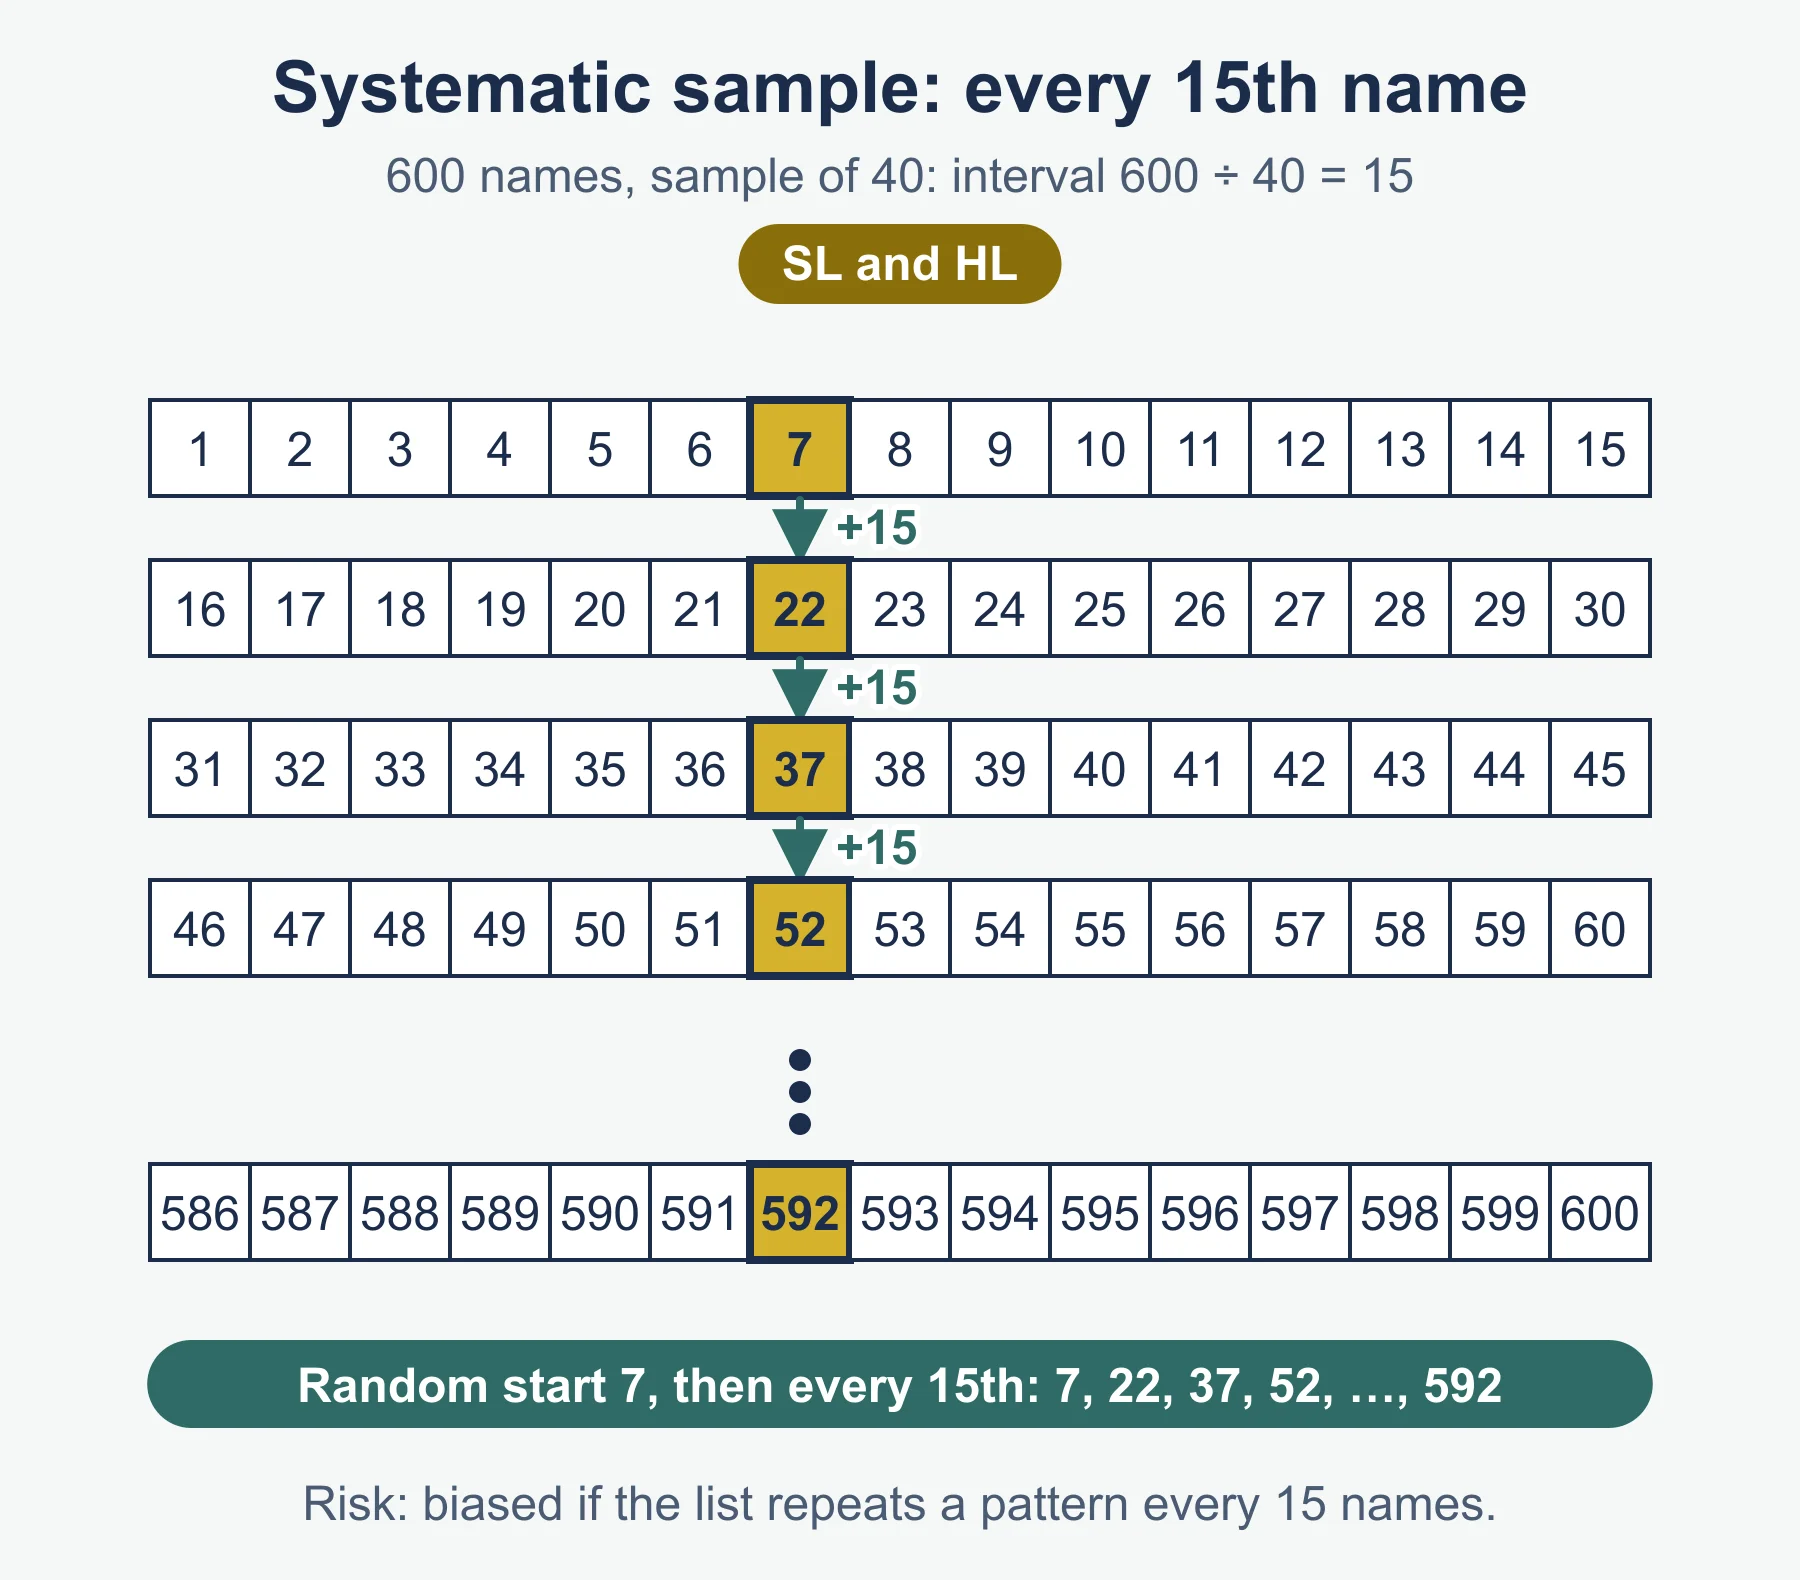
For a systematic sample of 40 from a list of 600 names, the interval is 600 ÷ 40 = 15. Choose a random start between 1 and 15, then take every 15th name.
Outliers
The guide defines an outlier as a data item more than 1.5 × IQR from the nearest quartile:
lower boundary = Q₁ − 1.5 × IQR
upper boundary = Q₃ + 1.5 × IQR
An outlier is not automatically wrong. It may be a valid, unusual value that you keep, or an error that you correct or remove. Give a reason tied to the context.
Section 4.2: Presenting data
Frequency tables and histograms
The guide says class intervals will be given as inequalities without gaps, for example 10 ≤ t < 20. You only need frequency histograms with equal class intervals: the height of each bar is the frequency and the bars touch. Frequency density histograms are not required.
Cumulative frequency graphs
Cumulative frequency is a running total. Plot each running total against the upper boundary of its class, start at zero at the lower boundary of the first class, and join the points with a smooth curve or straight lines.
For n data items, read across from:
- n/2 for the median
- n/4 for Q₁ and 3n/4 for Q₃
- p% of n for the p-th percentile
Then IQR = Q₃ − Q₁.
Worked example 2: grouped data and cumulative frequency
The times, t minutes, that 60 customers spent in a shop are shown.
| Time | Frequency | Cumulative frequency |
|---|---|---|
| 0 ≤ t < 10 | 6 | 6 |
| 10 ≤ t < 20 | 14 | 20 |
| 20 ≤ t < 30 | 22 | 42 |
| 30 ≤ t < 40 | 12 | 54 |
| 40 ≤ t < 50 | 6 | 60 |
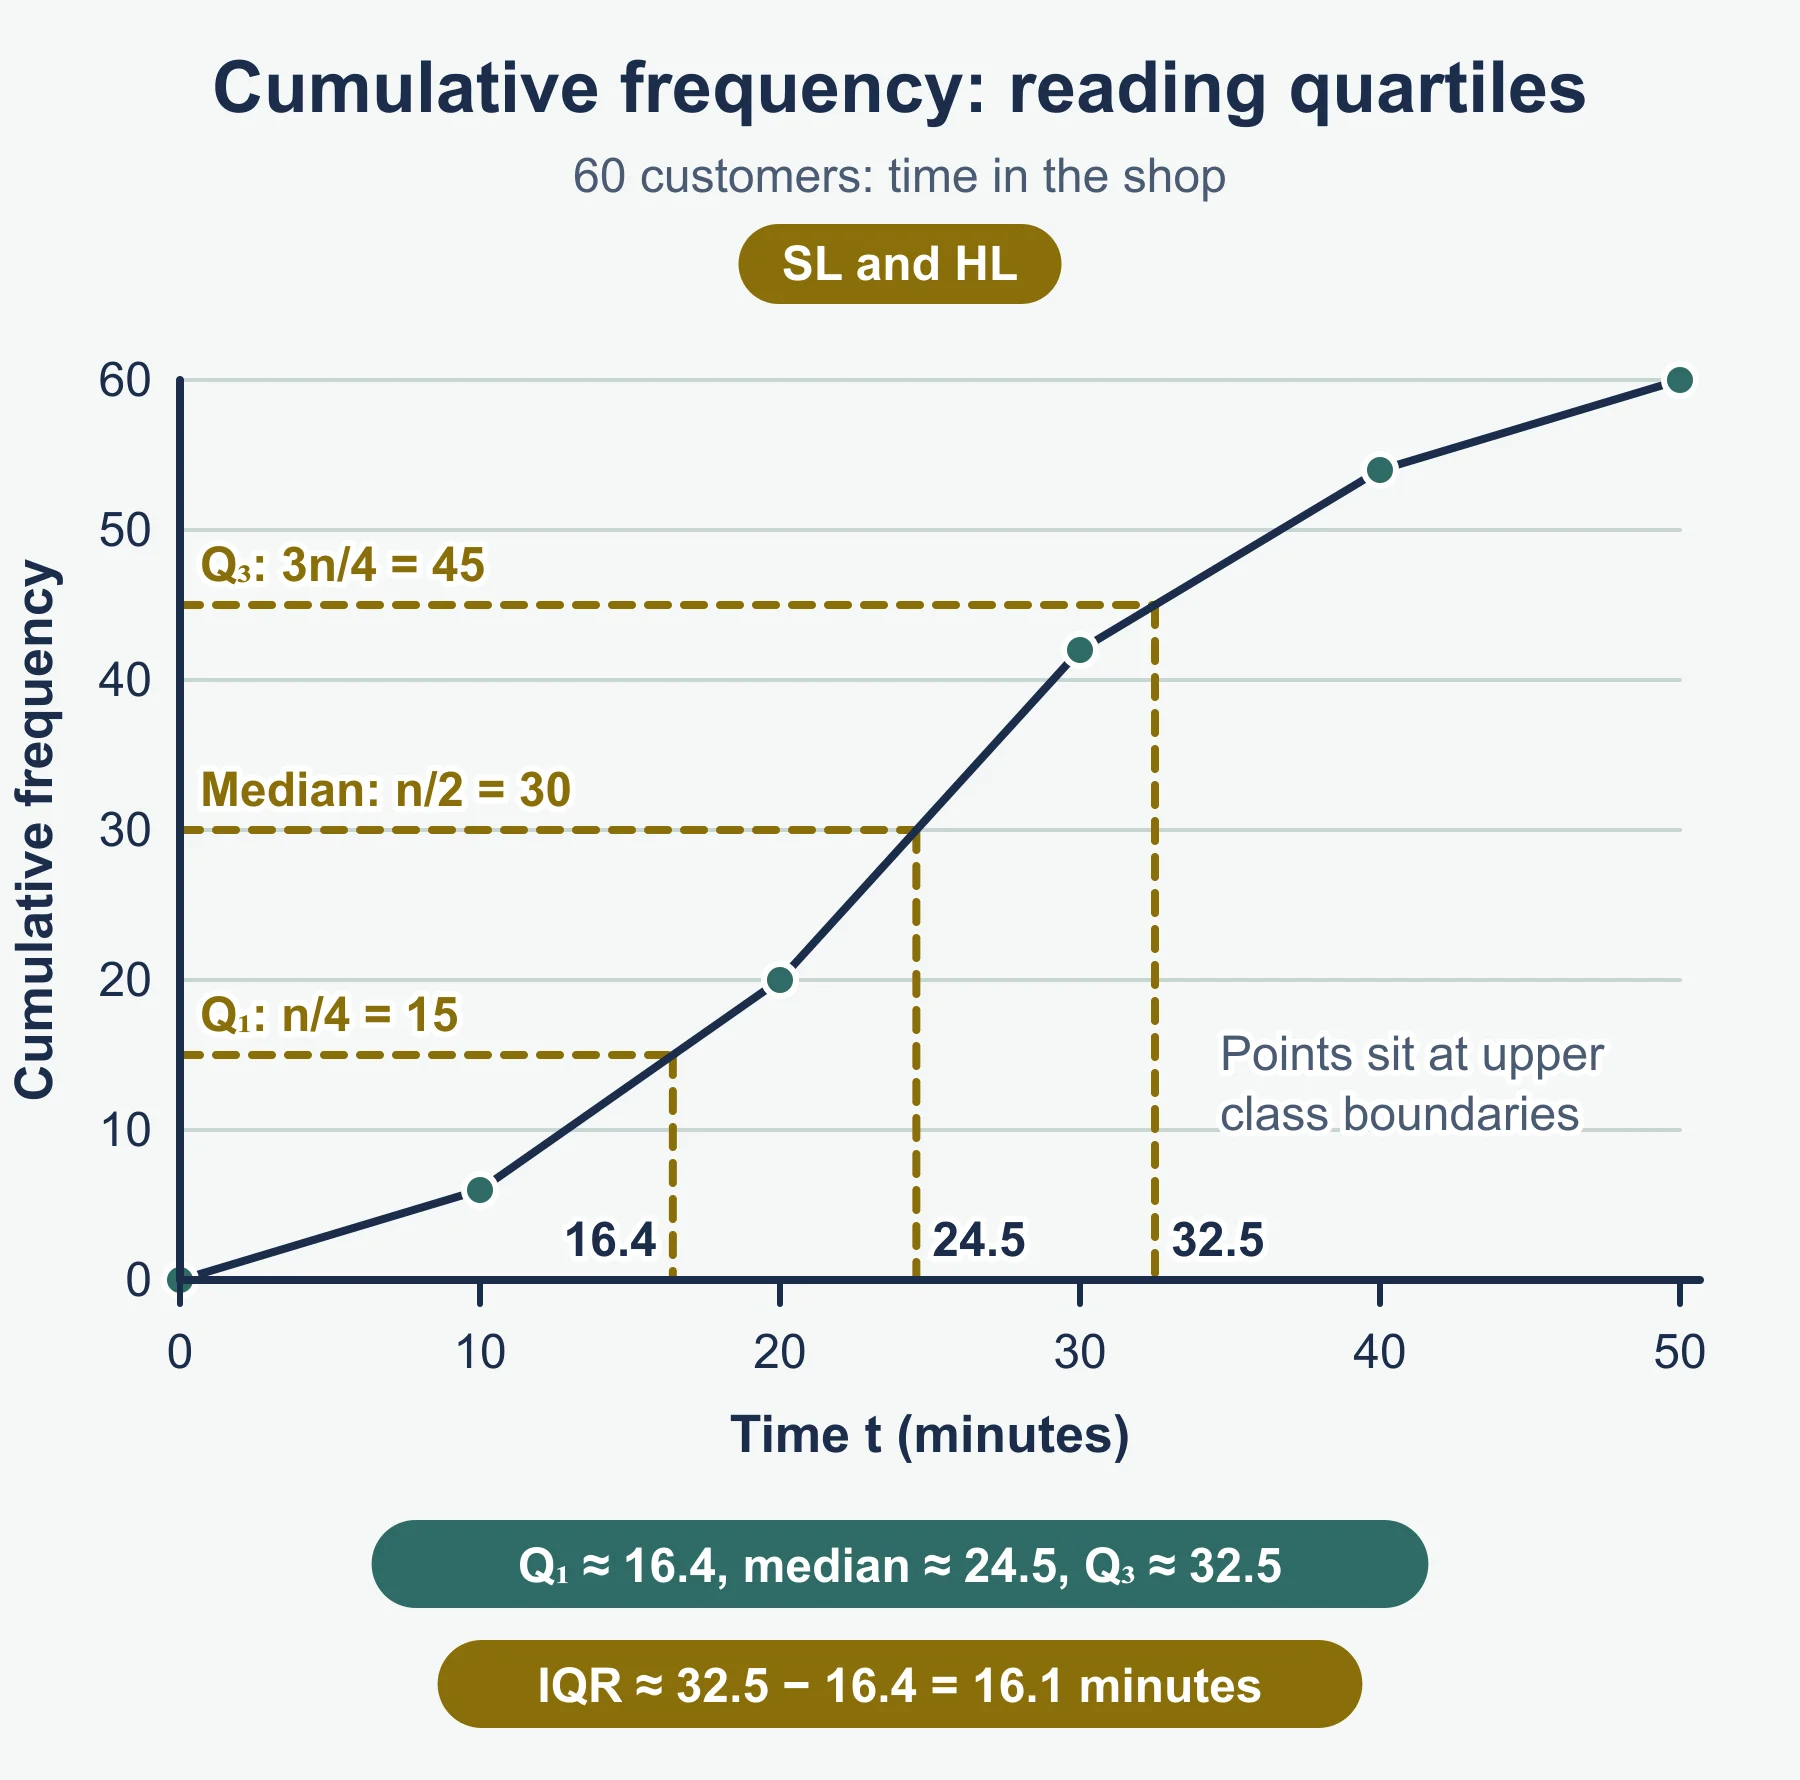
Plot (0, 0), (10, 6), (20, 20), (30, 42), (40, 54), (50, 60). Joining the points with straight lines gives these readings; a hand-drawn curve will give values close to them.
Median: 60/2 = 30th value, in 20 ≤ t < 30
        20 + (30 − 20)/22 × 10 = 24.5 minutes (3 s.f.)
Q₁:     15th value: 10 + (15 − 6)/14 × 10 = 16.4 minutes
Q₃:     45th value: 30 + (45 − 42)/12 × 10 = 32.5 minutes
IQR ≈ 32.5 − 16.4 = 16.1 minutes
90th percentile: 0.9 × 60 = 54th value → 40 minutes
More than 35 minutes: cumulative frequency at 35 is 48, so 60 − 48 = 12 customers
The modal class is 20 ≤ t < 30. The guide says you only find a modal class when the intervals are equal.
Box and whisker diagrams
A box and whisker diagram shows the minimum, Q₁, median, Q₃ and maximum. If there are outliers, the whisker stops at the most extreme value that is not an outlier, and each outlier is marked with a cross.
To compare two distributions, compare:
- a measure of centre (median), and
- a measure of spread (IQR or range),
and write each comparison in context. You can also comment on symmetry. The guide says a box and whiskers that are roughly symmetric about the median suggest the data may be normally distributed.
Worked example 3: outliers and a box plot
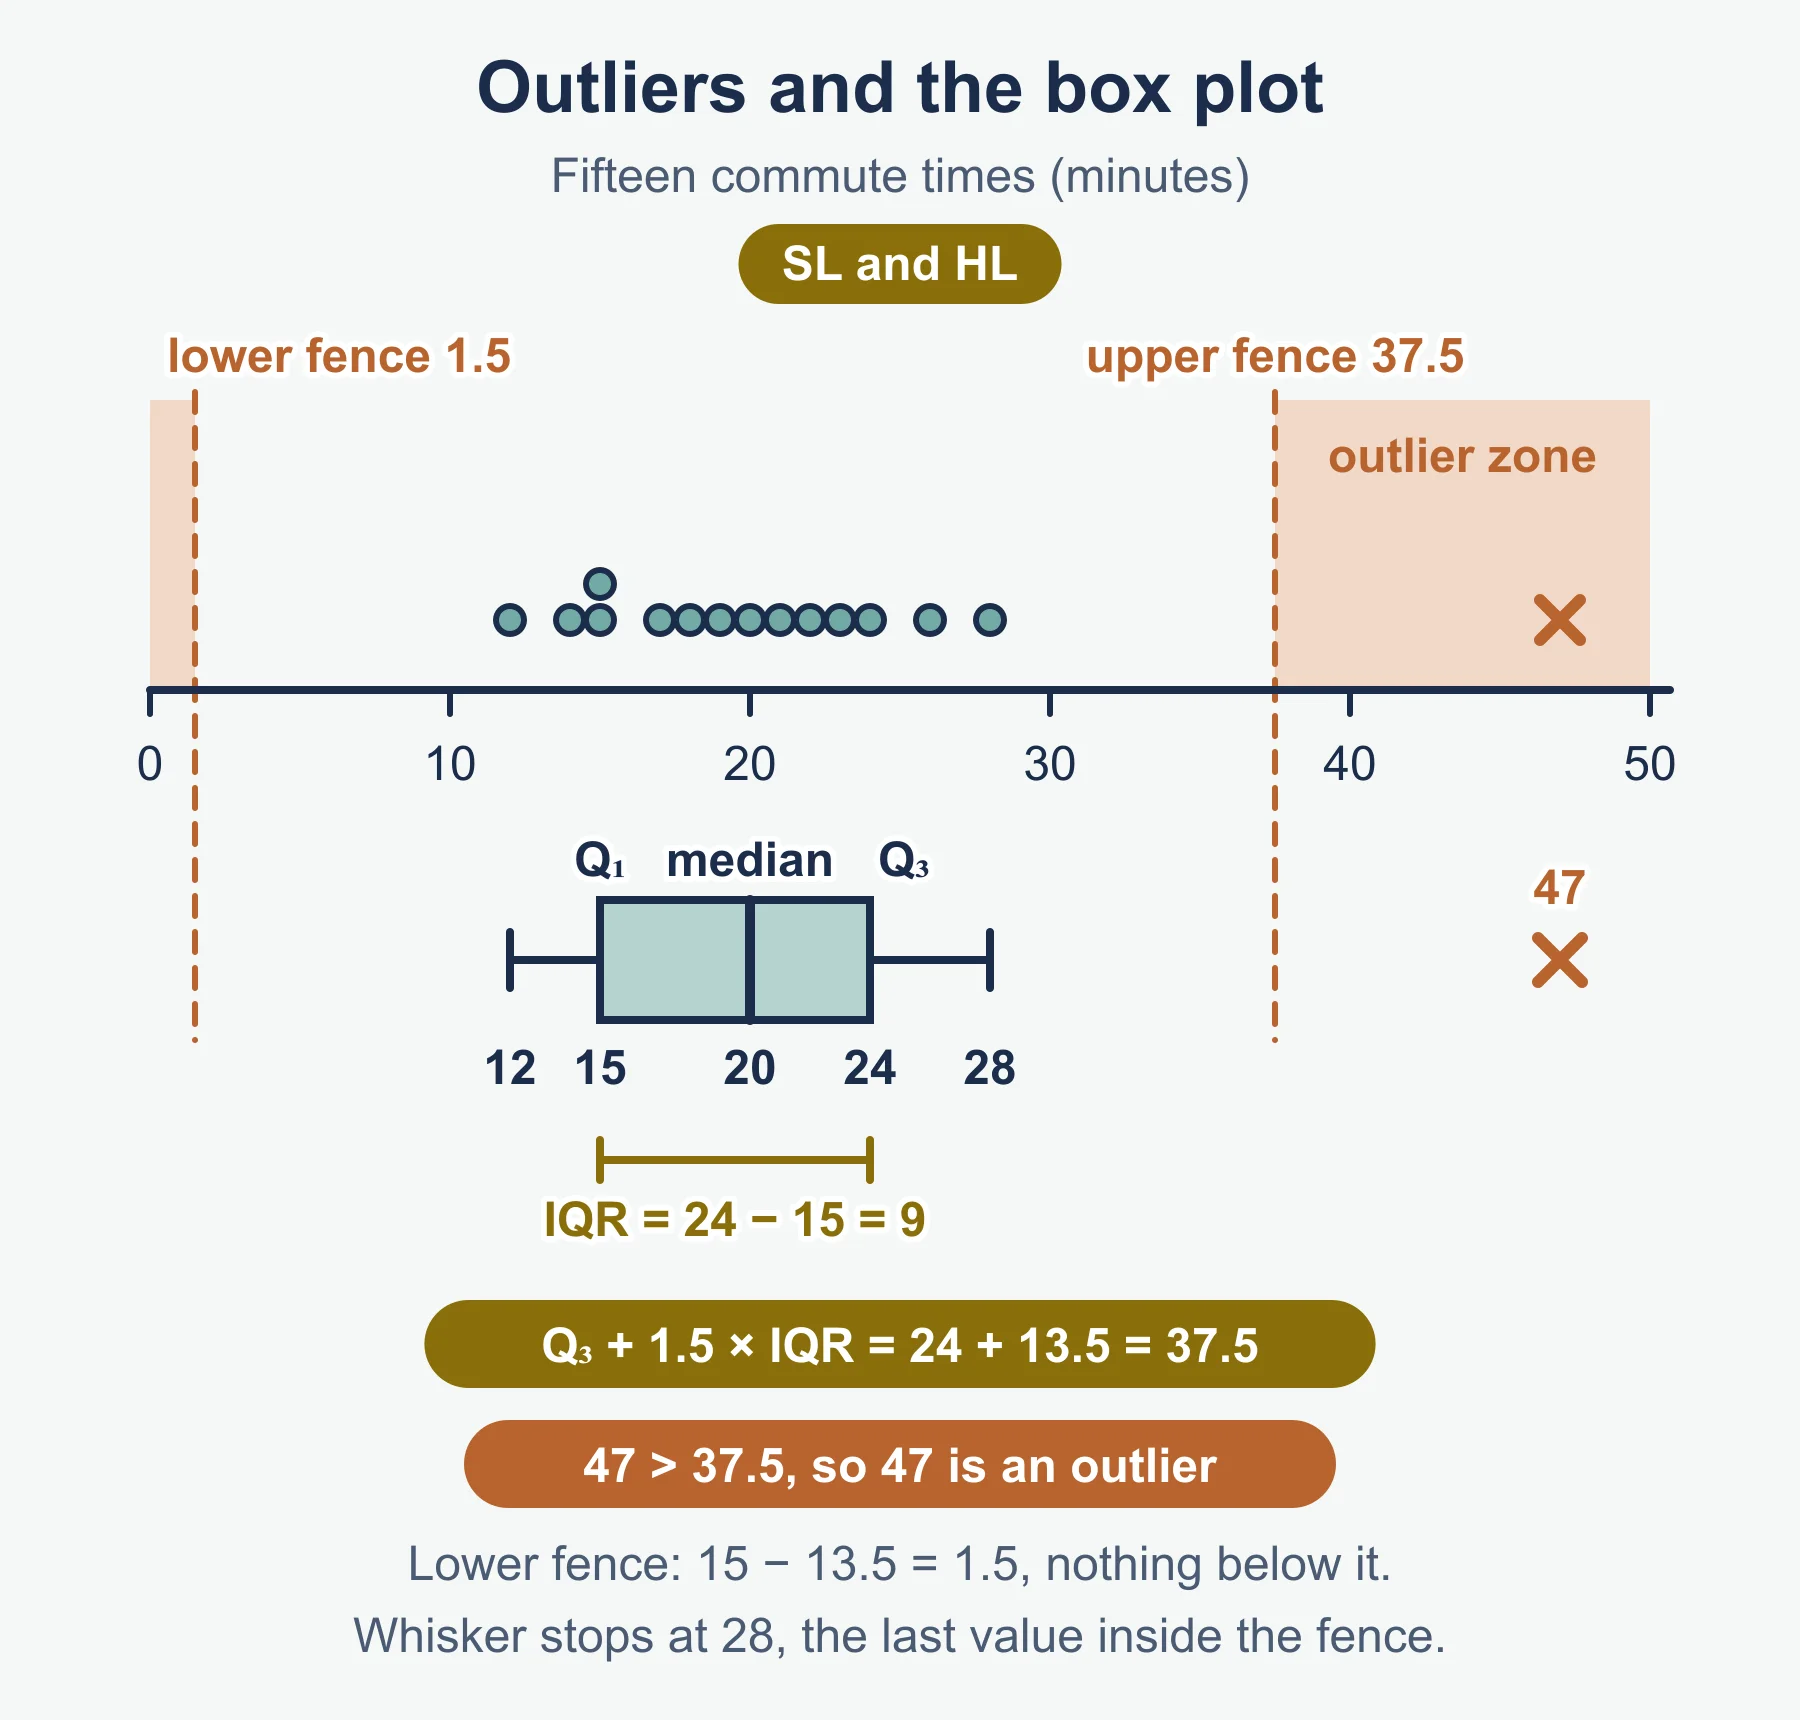
Fifteen commute times, in minutes:
12, 14, 15, 15, 17, 18, 19, 20, 21, 22, 23, 24, 26, 28, 47
Median = 8th value = 20
Lower half (first 7): 12, 14, 15, 15, 17, 18, 19 → Q₁ = 15
Upper half (last 7): 21, 22, 23, 24, 26, 28, 47 → Q₃ = 24
IQR = 24 − 15 = 9
1.5 × 9 = 13.5
Lower boundary = 15 − 13.5 = 1.5   (no value below this)
Upper boundary = 24 + 13.5 = 37.5  (47 > 37.5, so 47 is an outlier)
Draw the box from 15 to 24 with a line at 20, whiskers to 12 and 28, and a cross at 47. If that person’s train was delayed, 47 is valid and stays.
Section 4.3: Summary statistics
Measures of central tendency
- Mean: x̄ = Σx / n. For a frequency table, x̄ = Σfx / Σf.
- Median: the middle value once the data are in order; for n values it is the ((n + 1)/2)-th value.
- Mode: the most common value.
For grouped data you do not know the exact values, so use the mid-interval value of each class as x. The result is an estimate of the mean.
Shop example: mid-interval values 5, 15, 25, 35, 45
Σfx = 6(5) + 14(15) + 22(25) + 12(35) + 6(45) = 1480
x̄ ≈ 1480 / 60 = 24.7 minutes (3 s.f.)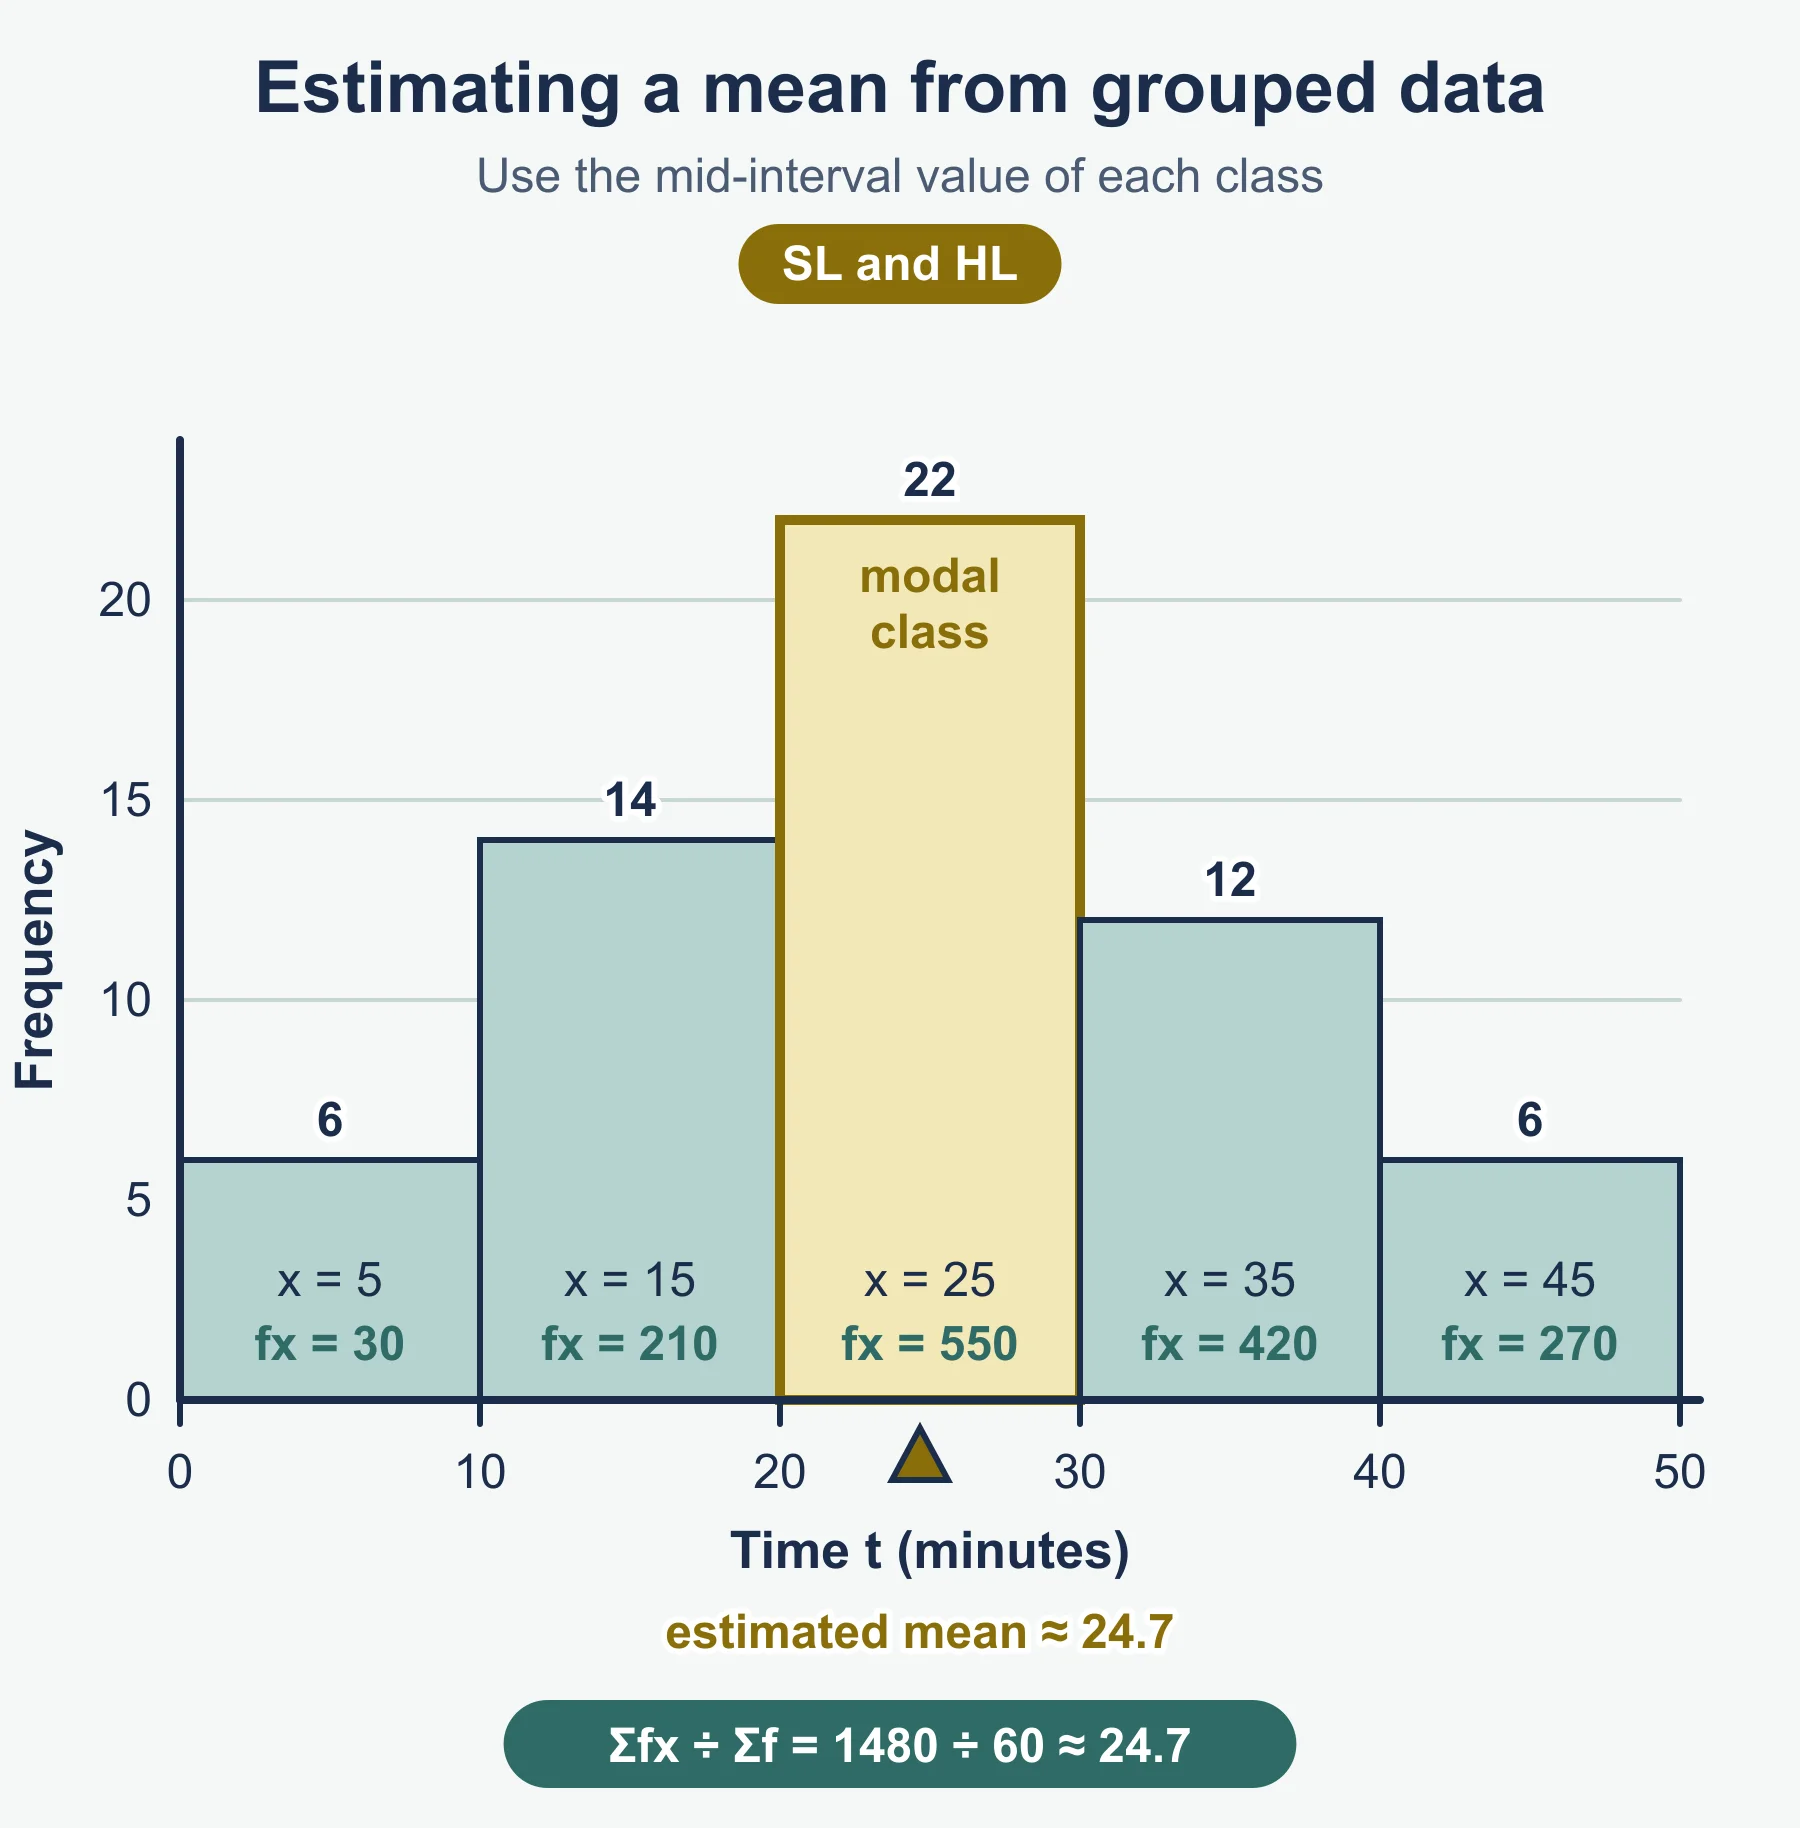
Measures of dispersion
- Range = maximum − minimum
- IQR = Q₃ − Q₁; not affected by outliers
- Standard deviation, σ: the typical distance of values from the mean
- Variance = σ², the square of the standard deviation
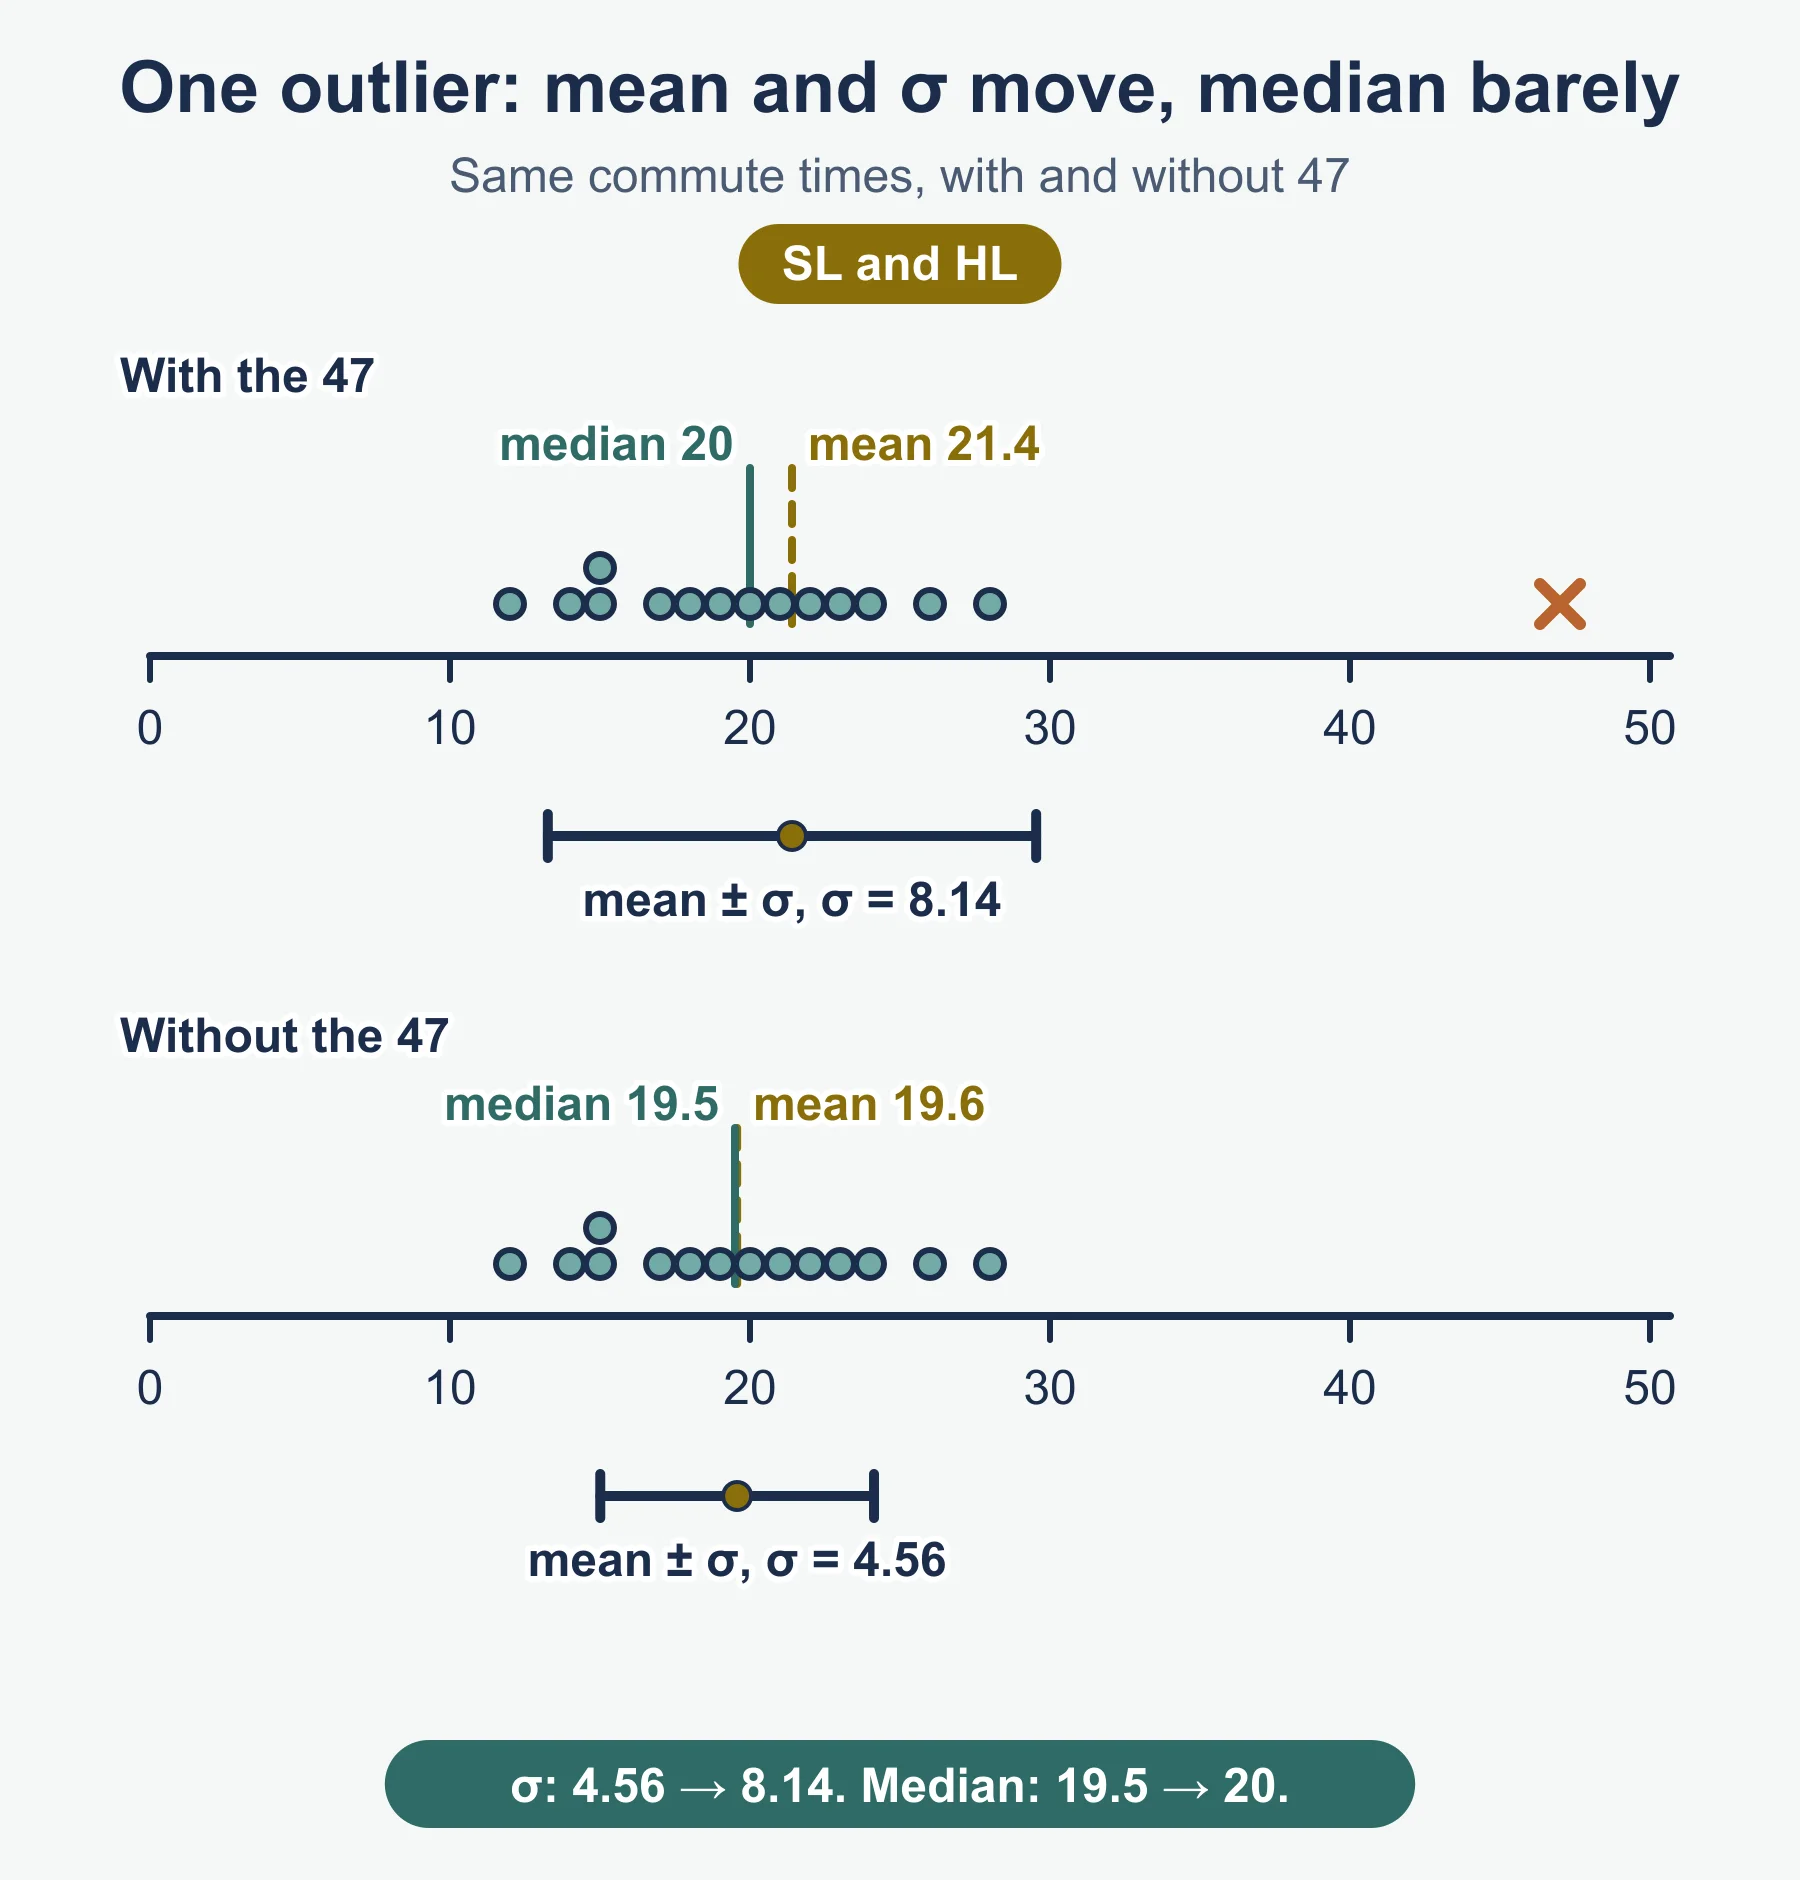
The guide says standard deviation and variance are found using only technology. For the commute data, the GDC gives x̄ = 21.4 and σ = 8.14 minutes (3 s.f.). Without the 47 they become 19.6 and 4.56, so one outlier nearly doubles σ. The median only moves from 20 to 19.5. This is why the median and IQR are often better summaries when there are outliers.
Using your GDC
- Enter data in a list, with frequencies in a second list.
- One-variable statistics gives x̄, σx, Sx, the minimum, Q₁, median, Q₃ and maximum.
- At SL, use σx, since the data set is treated as the population unless you are told otherwise.
- For grouped data, enter the mid-interval values with their frequencies.
Quartiles of discrete data
The guide expects you to find quartiles with technology, and to know that different methods exist, so a hand method and a GDC or spreadsheet may give slightly different values. The method used above (median of each half, leaving out the middle value when n is odd) is a common hand method; check it against what your own GDC gives for the same list.
Effect of constant changes
| Change to every data item | Mean | Standard deviation | Variance |
|---|---|---|---|
| Add or subtract k | ± k | unchanged | unchanged |
| Multiply by k (k > 0) | × k | × k | × k² |
Adding a constant shifts every value, so the spread does not change. Multiplying stretches the spread by the same factor. The median and quartiles change in the same way as the mean, and the IQR changes like the standard deviation.
Worked example 4: rescaled test marks
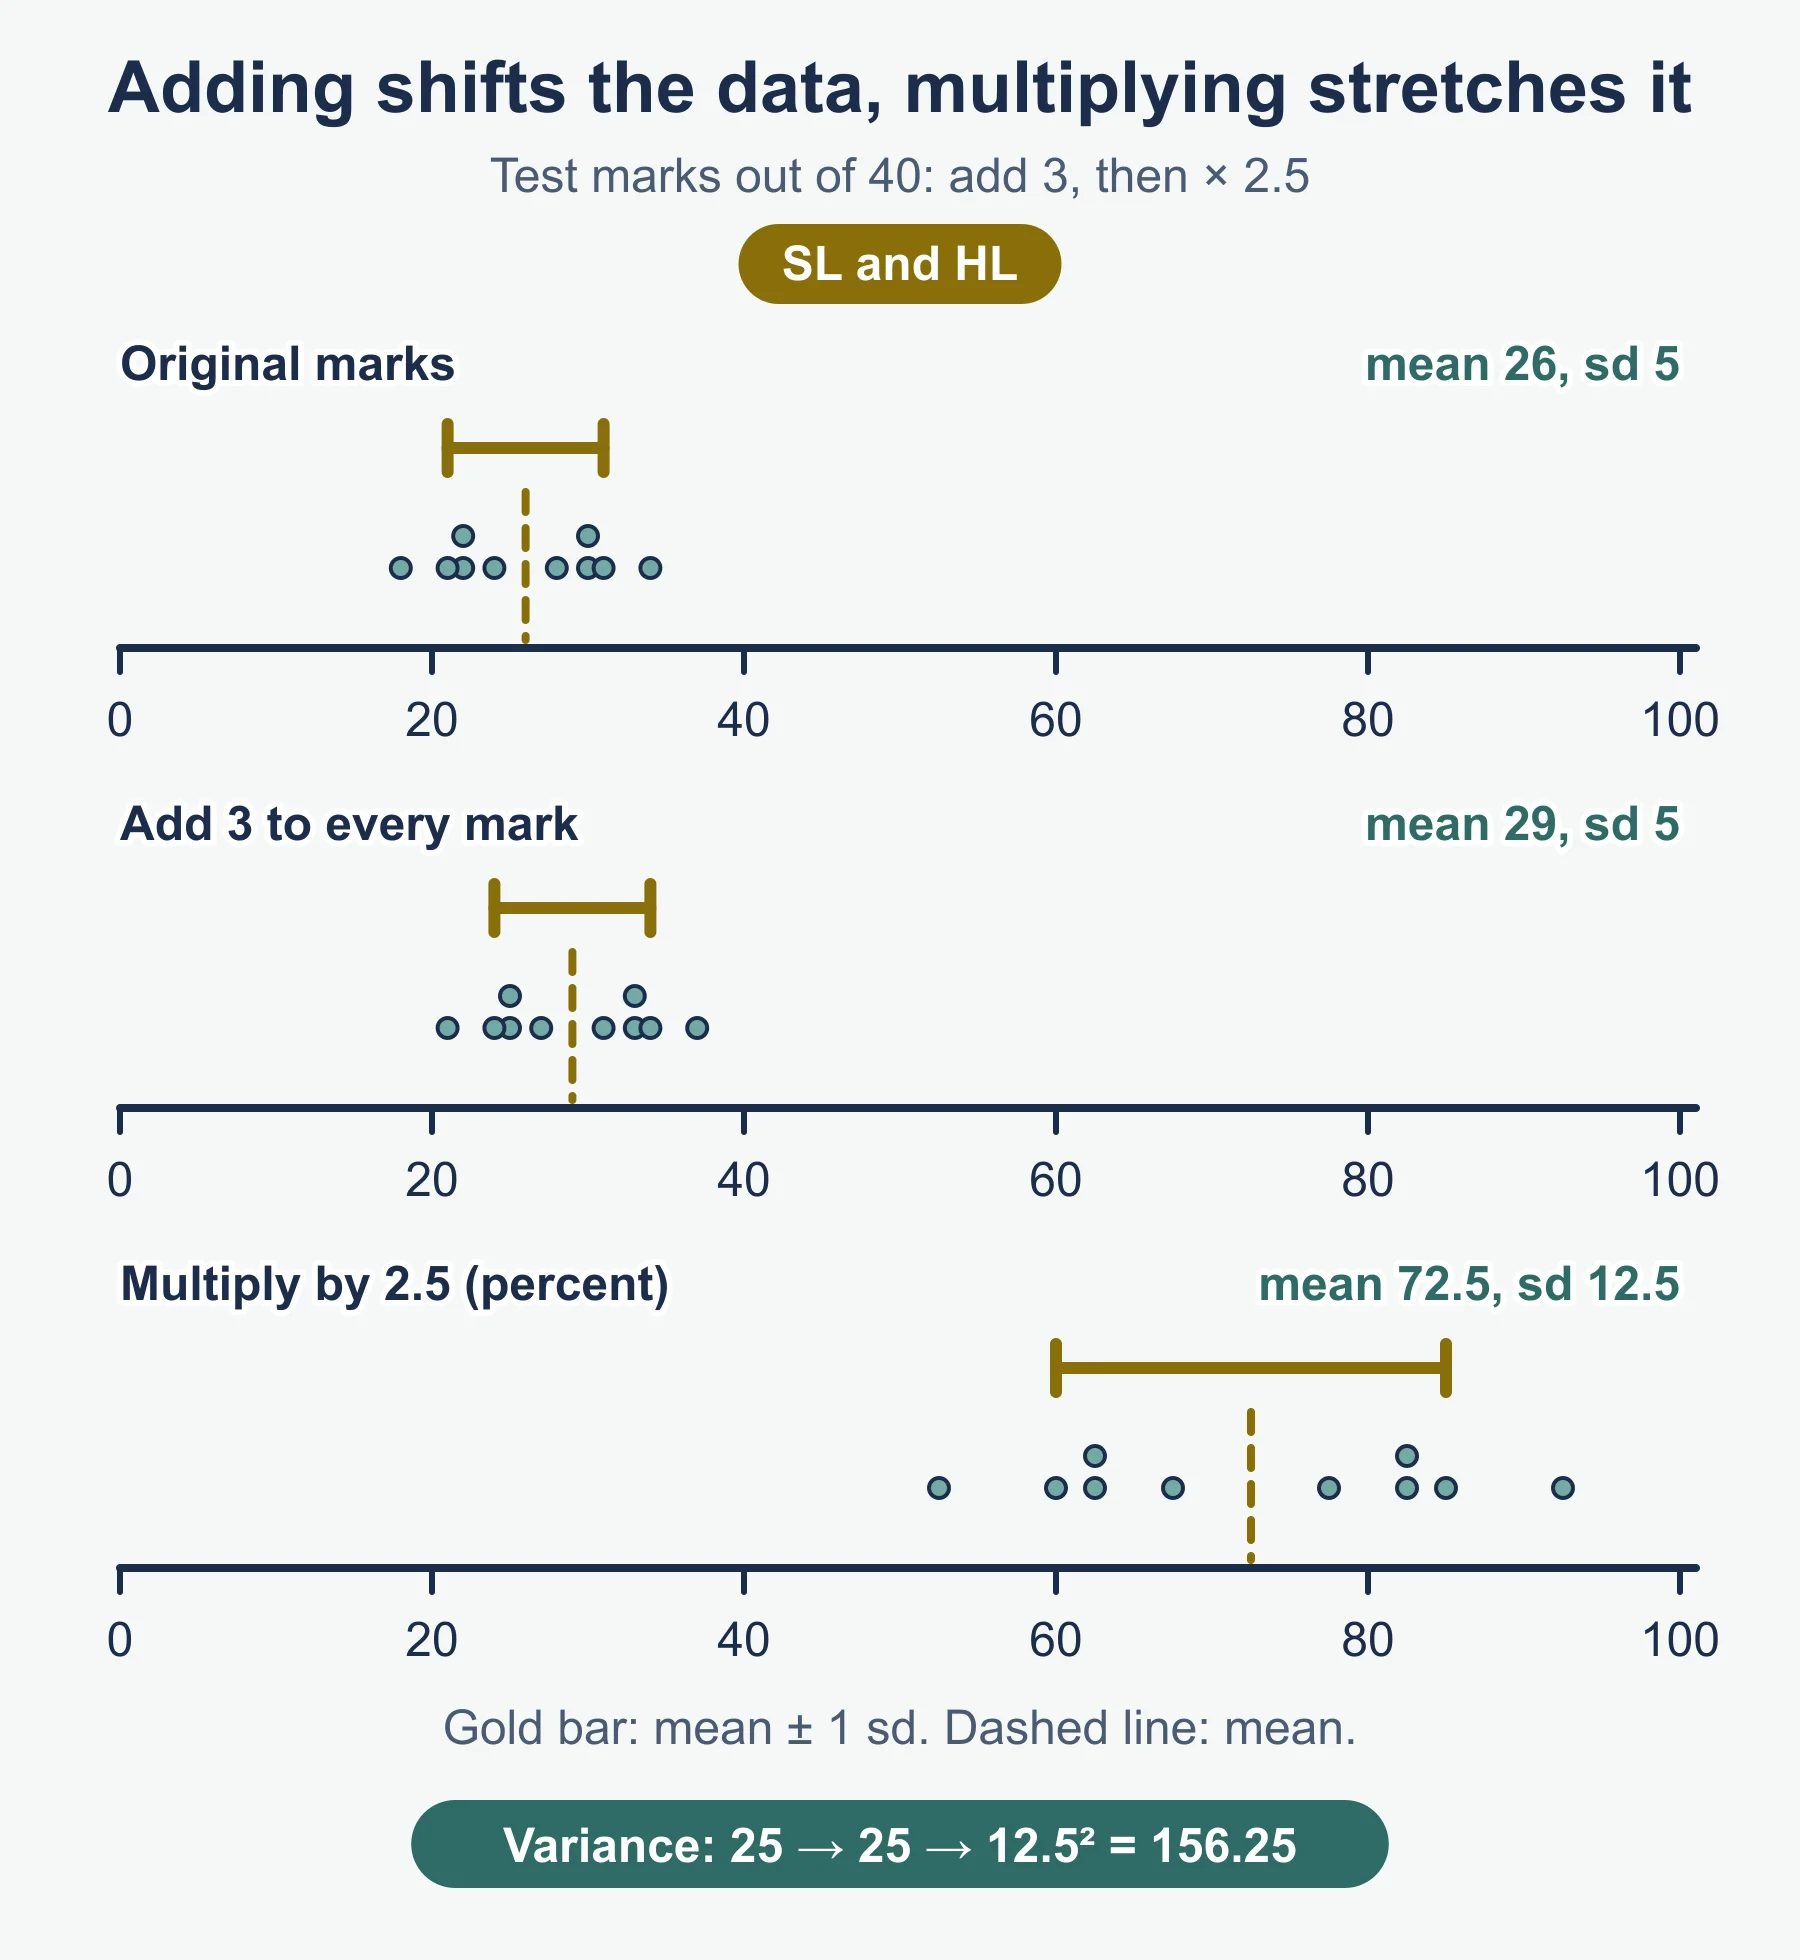
A test out of 40 has mean 26 and standard deviation 5. The teacher adds 3 marks to every script, then multiplies by 2.5 to turn marks into percentages.
Add 3:          mean = 29,           sd = 5
Multiply 2.5:   mean = 29 × 2.5 = 72.5%,  sd = 5 × 2.5 = 12.5%
Variance = 12.5² = 156.25
The order matters for the mean: adding 3 before scaling adds 7.5 percentage points to the mean.
Common errors
- Plotting cumulative frequency at the midpoint of each class instead of the upper boundary.
- Reading the median at the ((n + 1)/2)-th position on a cumulative frequency graph of grouped data; use n/2.
- Calling a value an outlier because it “looks far away” without calculating Q₁ − 1.5 × IQR and Q₃ + 1.5 × IQR.
- Drawing the whisker to the outlier instead of to the last value inside the boundary, or forgetting the cross.
- Using class boundaries or class widths instead of mid-interval values to estimate a mean.
- Saying adding a constant changes the standard deviation, or that multiplying by k multiplies the variance by k.
- Describing a stratified sample as a quota sample: in a stratified sample the members of each group are chosen at random.
Where to go next
Fix the definitions and methods with the revision notes, then test yourself with the practice questions. For paper formats and timing, read the exam preparation guide and the syllabus guide.
Frequently asked questions
What are the five sampling methods in IB Maths AI? The IB Maths AI guide lists simple random, convenience, systematic, quota and stratified sampling. Simple random and stratified sampling use random selection; convenience and quota sampling do not.
Is an outlier always a mistake? No. An outlier is a value more than 1.5 × IQR from the nearest quartile, and it may be a valid value or a recording error. Use the context to decide whether to keep it.
What should you do with missing data in a data set? Leave that response out of calculations that need the missing value and say that you have done so. You should not invent a value.
How do you choose the interval for a systematic sample? Divide the population size by the sample size to get k, choose a random start between 1 and k, then take every k-th member. For 40 from a list of 600, k = 15.
Official syllabus
International Baccalaureate Organization, Diploma Programme, Mathematics: applications and interpretation guide, first assessment 2021 – syllabus sections 4.1, 4.2 and 4.3.
Get free revision emails (optional)
Occasional emails with practice questions, worked explanations and links to free resources for the qualification and subjects you choose. No spam, and you can unsubscribe from any email. The free tools on this site never need an email.
Related resources
-
Practice questions
IB DP Mathematics: Applications and Interpretation – Sampling, data presentation and summary statistics Practice Questions
11 original questions with marked answers on sampling, outliers, cumulative frequency, box plots and summary statistics for IB DP Maths AI SL and HL.
Mathematics: Applications and Interpretation · International Baccalaureate · IB
Try questions -
Revision notes
IB DP Mathematics: Applications and Interpretation – Sampling, data presentation and summary statistics Revision Notes
Condensed revision notes on sampling, bias, outliers, cumulative frequency, box plots and summary statistics, with a self-test, for IB DP Maths AI.
Mathematics: Applications and Interpretation · International Baccalaureate · IB
Revise topic -
Study guides
IB DP Mathematics: Applications and Interpretation – Statistics and Probability
The IB DP Maths AI statistics and probability strand: descriptive statistics, probability, binomial and normal models, inference and how to interpret results.
Mathematics: Applications and Interpretation · International Baccalaureate · IB
Read guide
Related articles
-
teaching
A Level tuition in Dubai: Cambridge or Pearson Edexcel International A Level?
Schools in Dubai and Abu Dhabi teach either Cambridge International AS & A Level or Pearson Edexcel International A Level. How the two are structured, why it matters for tuition, and how online classes from Lahore work.
9 October 2026
-
curriculum guides
Choosing subjects at IGCSE and A Level
How subject choices at 14 and 16 affect university options later, and how to keep pathways open without overloading a timetable.
28 July 2026
Studying this with a teacher
Working through Mathematics: Applications and Interpretation IB?
This page is free and stays free. If you would rather be taught it, Marlbridge runs Mathematics: Applications and Interpretation classes one-to-one, online in your own time zone. The first trial class is free. WhatsApp replies within an hour (8am–11pm Pakistan time, every day); email the same day.
IB Mathematics: Applications and Interpretation teachers at Marlbridge

