
Study Guides
AQA GCSE Mathematics 8300: Statistics – Study Guide
Study guide for AQA GCSE Maths 8300 Statistics (S1-S6): sampling, charts, averages and spread, histograms, box plots and scatter graphs.
- Subject
- Mathematics
- Level
- GCSE
- Topic
- Statistics
- Author
- Marlbridge Academic Team
- Updated
- Reviewed by
- Sajawal Zahid (what this means)
Aligned to AQA GCSE Mathematics (8300), For first teaching 2015. Official specification .
Syllabus page (what it covers and how it is assessed): AQA GCSE Mathematics.
Syllabus topics and points this page is mapped to
8300
- 6 Statistics (topic-level mapping)
"Topic-level mapping" means this page belongs to that topic; it does not claim to cover every point in it.
Found an error? Report a correction.
Need help with this topic? Request a free trial class for GCSE Mathematics (8300).
This study guide teaches Topic 6, Statistics (specification references S1 to S6), of the AQA GCSE Mathematics (8300) specification, for teaching from September 2015 with exams from May/June 2017 (version 1.0). Statistics can be tested on any of the three papers at Foundation or Higher tier. Most of it is for both tiers. Histograms, cumulative frequency graphs (S3), box plots, quartiles and interquartile range (part of S4) are Higher tier only and are labelled below. Exams run every May/June and November.
Use it with the Statistics revision notes and the Statistics practice questions. The course hub is AQA GCSE Mathematics, the printable checklist lists every statement, and the free 10-minute diagnostics show where to start.
What this topic covers
| Spec | What you must be able to do | Tier |
|---|---|---|
| S1 | Infer properties of a population from a sample, knowing the limits of sampling | Both |
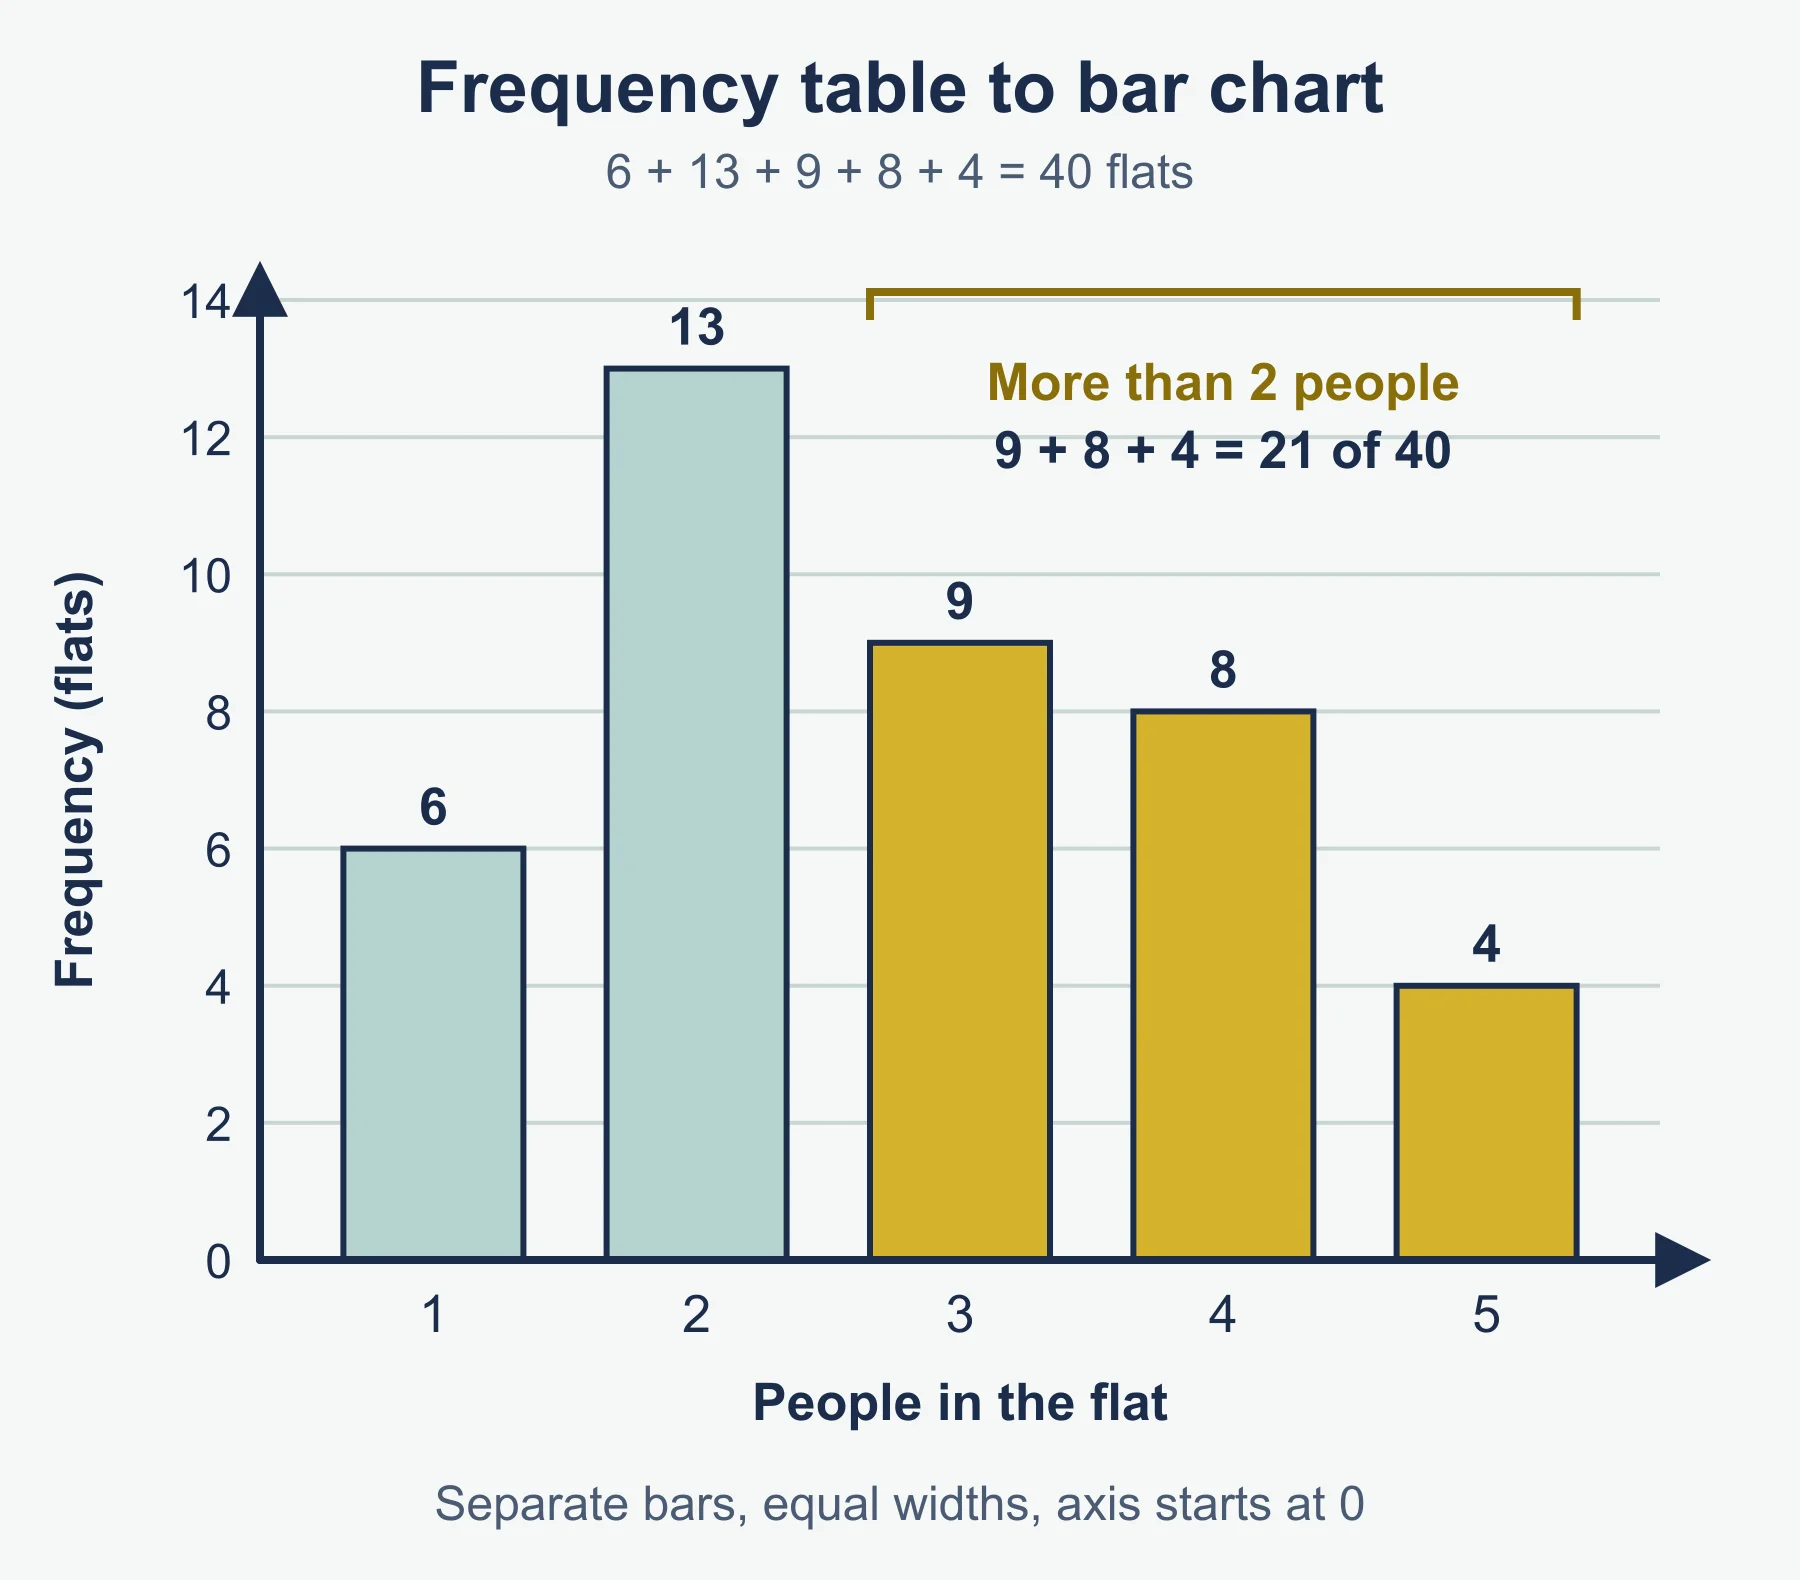
| S2 | Read and draw frequency tables, bar charts, pie charts, pictograms, vertical line charts, and tables and line graphs for time series; choose a suitable diagram | Both |
| S3 | Draw and interpret histograms (equal and unequal class widths) and cumulative frequency graphs | Higher tier only |
| S4 | Compare distributions using graphs, averages (mean, median, mode, modal class) and range, including outliers | Both |
| S4 | Box plots, quartiles and interquartile range | Higher tier only |
| S5 | Apply statistics to describe a population | Both |
| S6 | Scatter graphs, correlation, lines of best fit, interpolation and extrapolation; correlation is not causation | Both |
Probability and statistics together make up about 15% of the marks at both tiers.
Types of data
You must know these four terms (S4 notes):
- Primary data: you collect it yourself, e.g. your own survey.
- Secondary data: someone else collected it, e.g. a website or a published table.
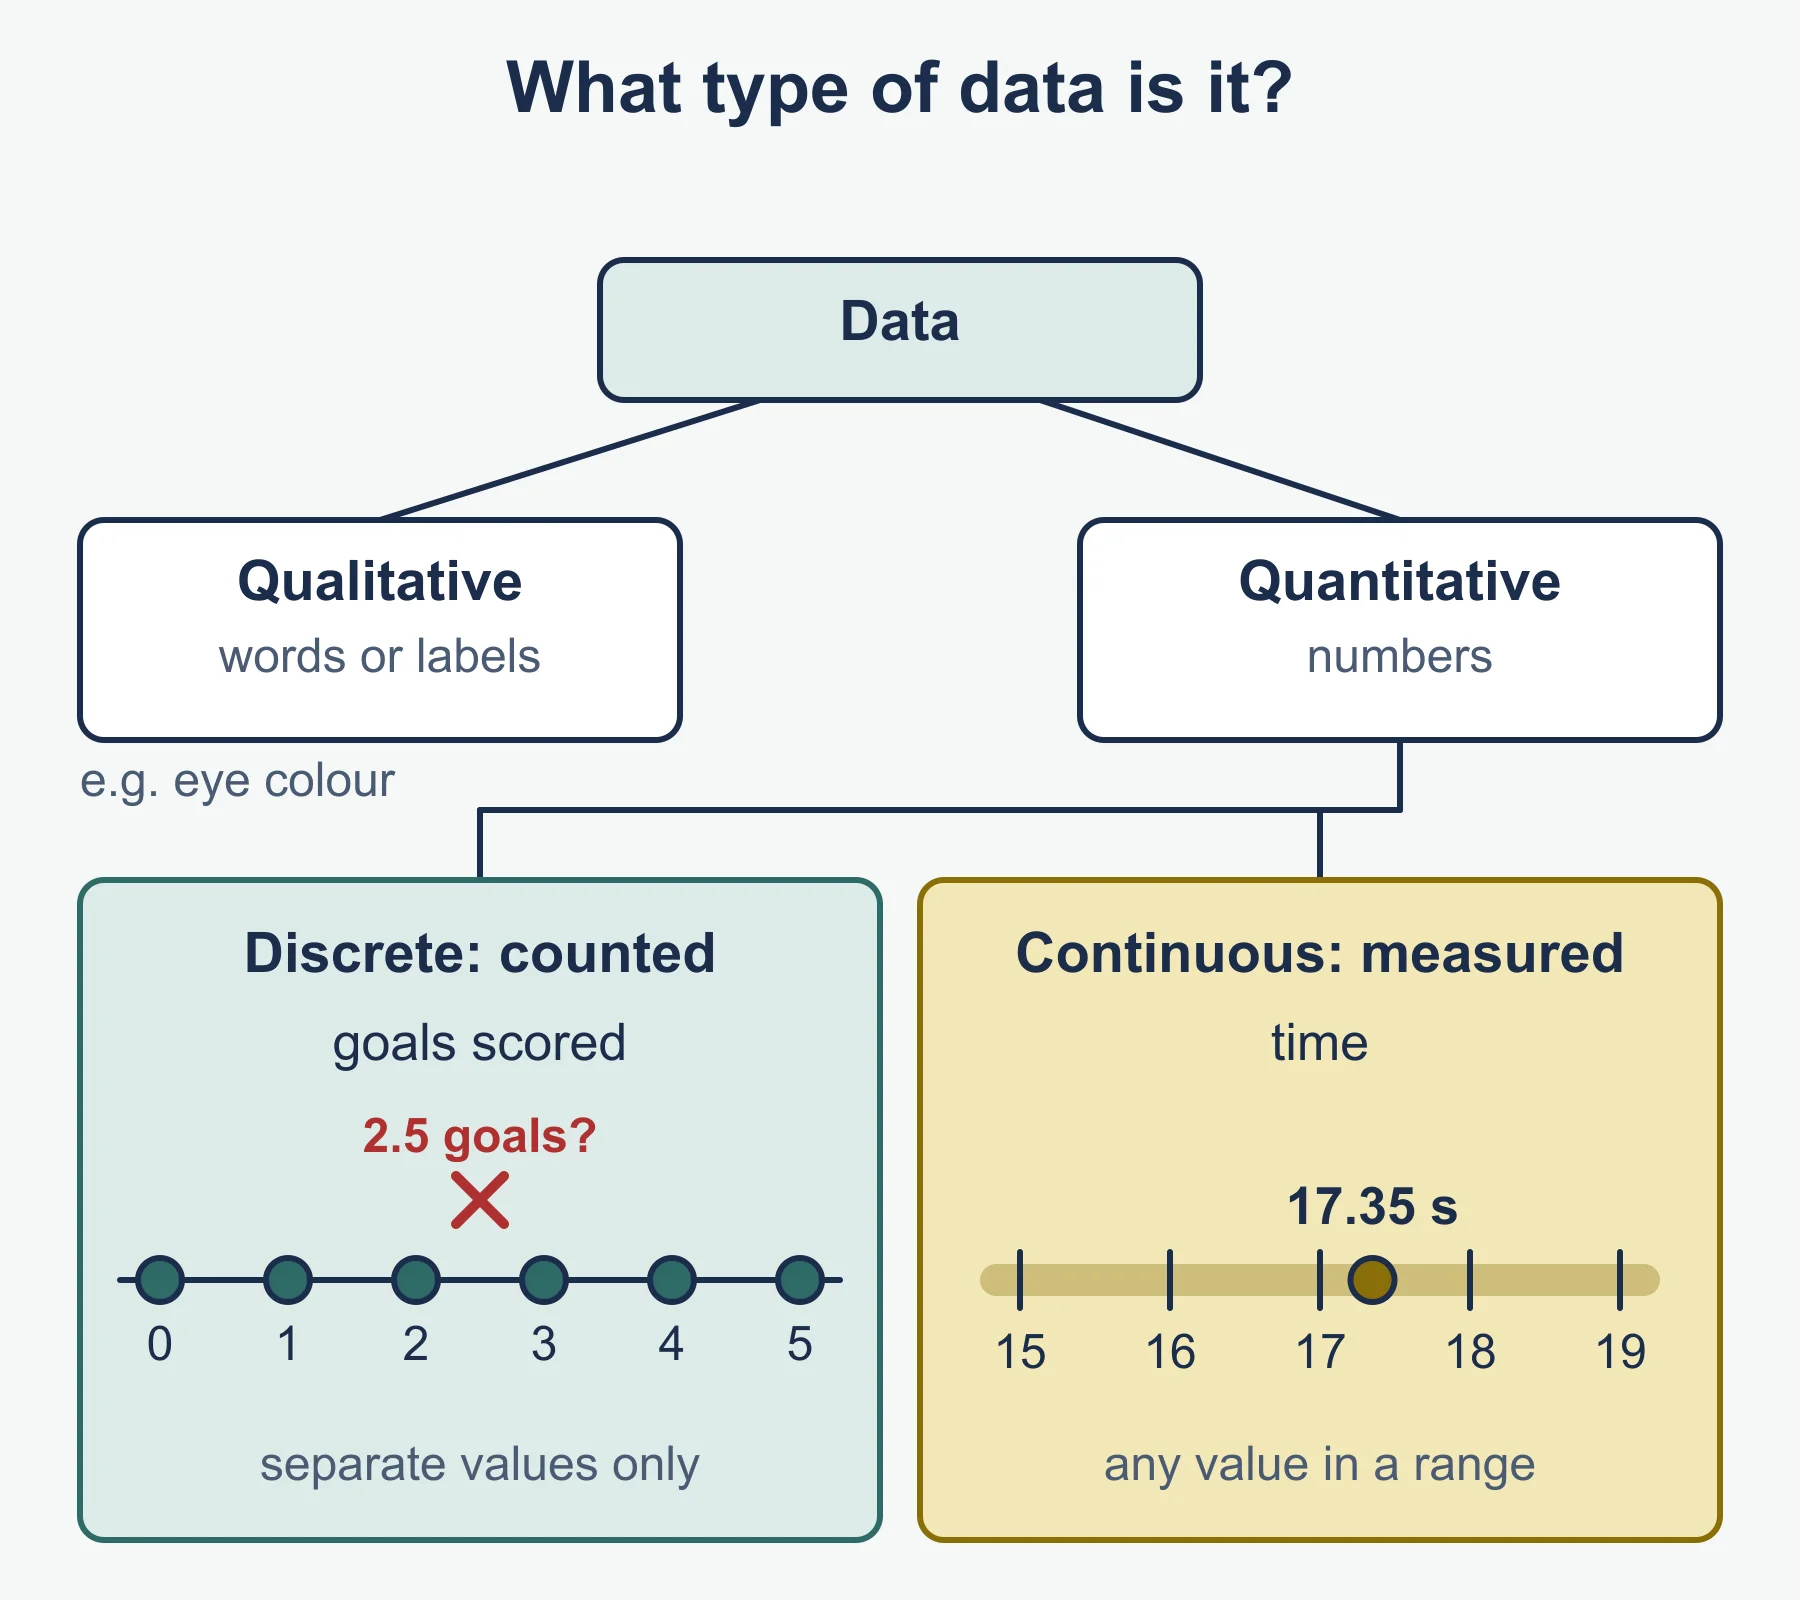
- Discrete data: can only take separate values, usually counts, e.g. number of siblings.
- Continuous data: measured, so it can take any value in a range, e.g. height, time, mass.
Populations and samples (S1, S5)
The population is the whole group you want to know about. A sample is the part you actually ask or measure. Sampling is quicker and cheaper, but a sample only gives an estimate.
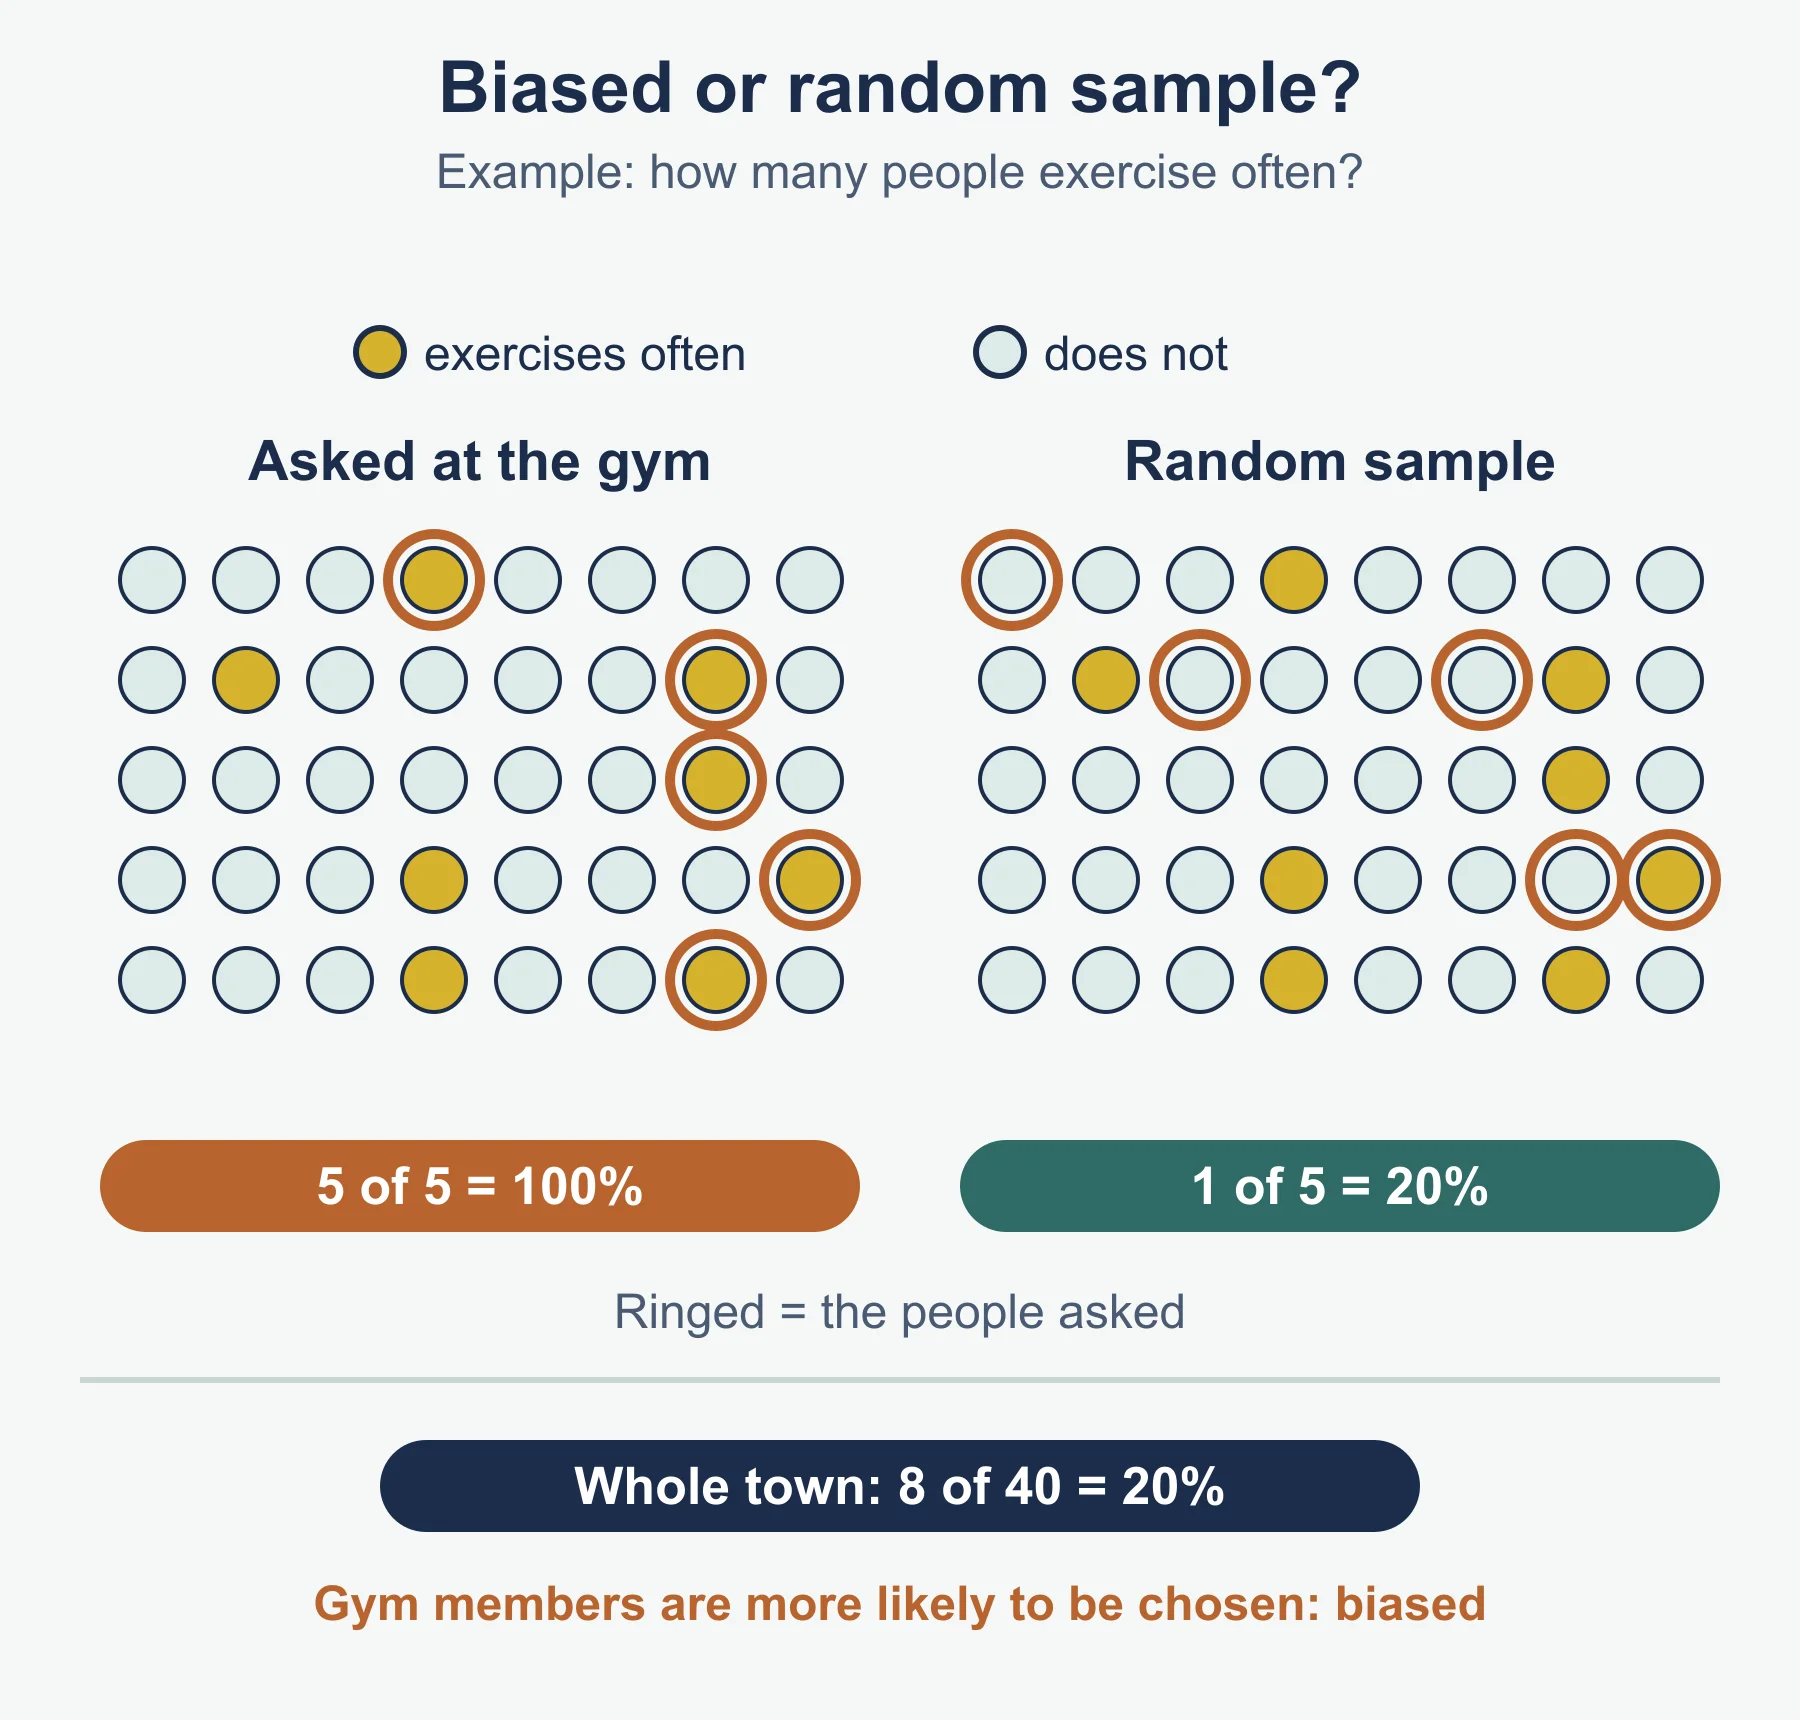
A sample is biased if some members of the population are more likely to be chosen than others. Asking people at a gym about exercise habits will overstate how much the town exercises. A random sample gives every member an equal chance. A larger random sample gives a more reliable estimate.
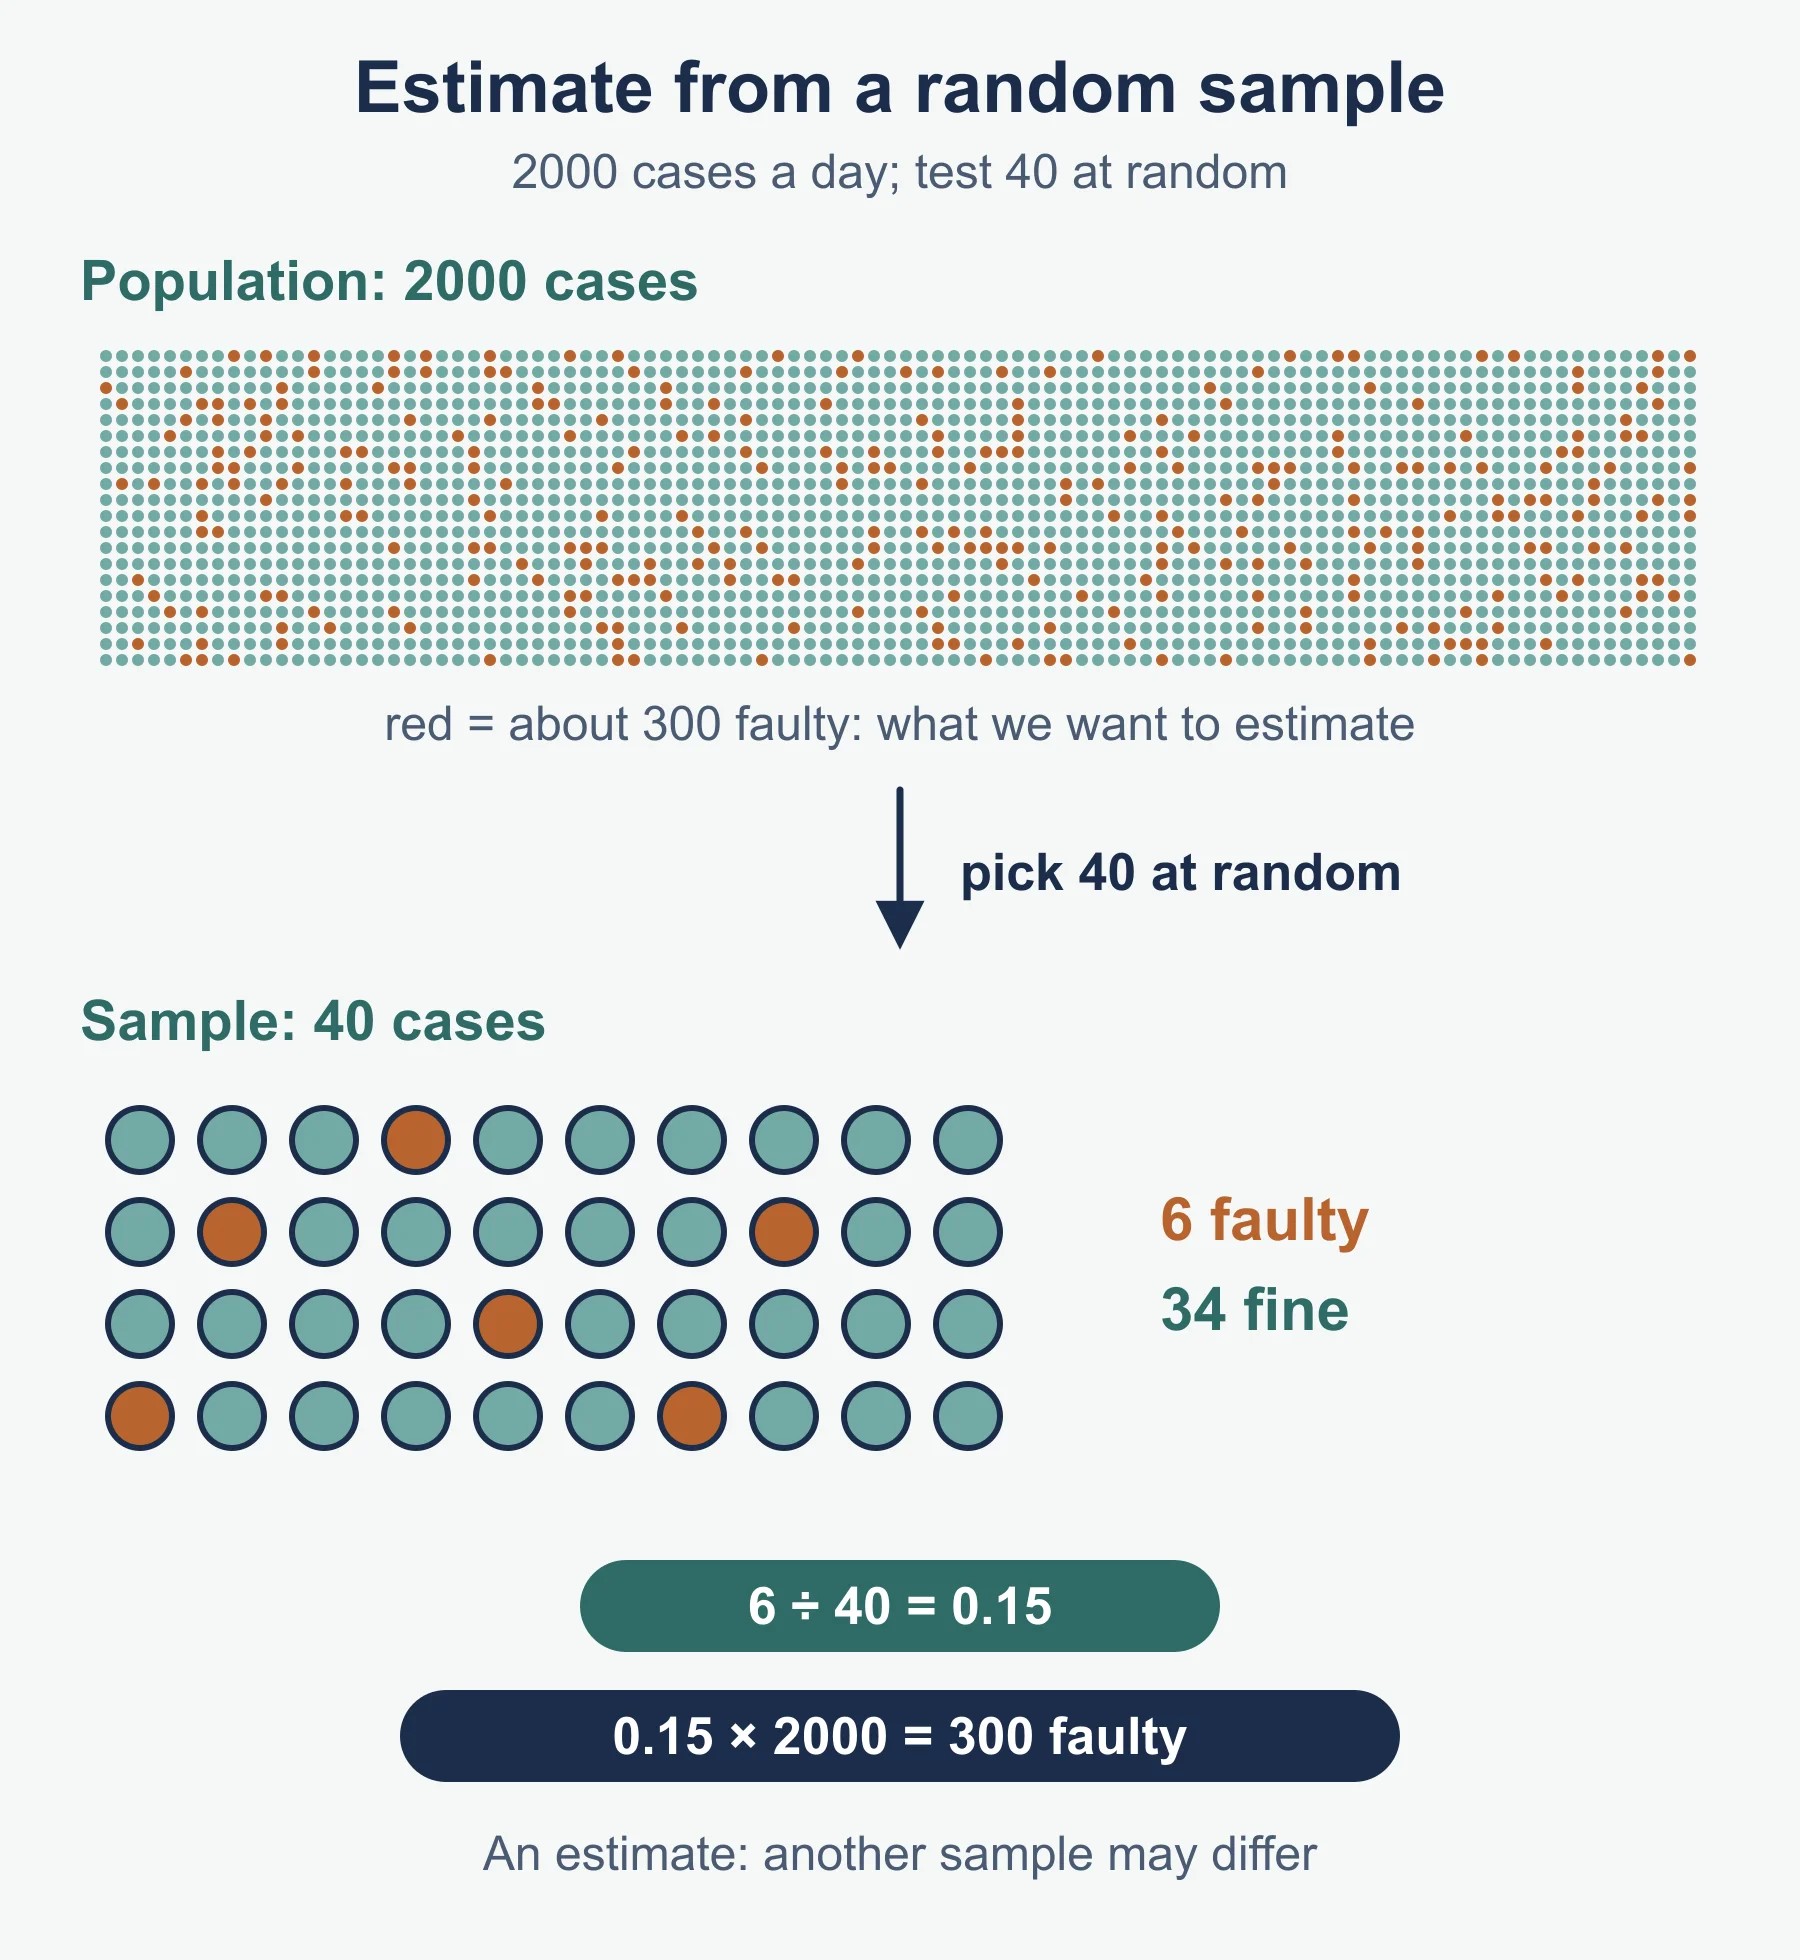
Worked example 1. A factory makes 2000 phone cases a day. A random sample of 40 has 6 faulty cases.
Proportion faulty in sample = 6/40 = 0.15
Estimate for the population = 0.15 × 2000 = 300 faulty cases
The answer is an estimate. A different sample of 40 could give a different answer.
Tables, charts and diagrams (S2)
| Diagram | Use it for |
|---|---|
| Bar chart | Categories (e.g. favourite sport); bars the same width with gaps |
| Pictogram | Categories; needs a key saying what one symbol stands for |
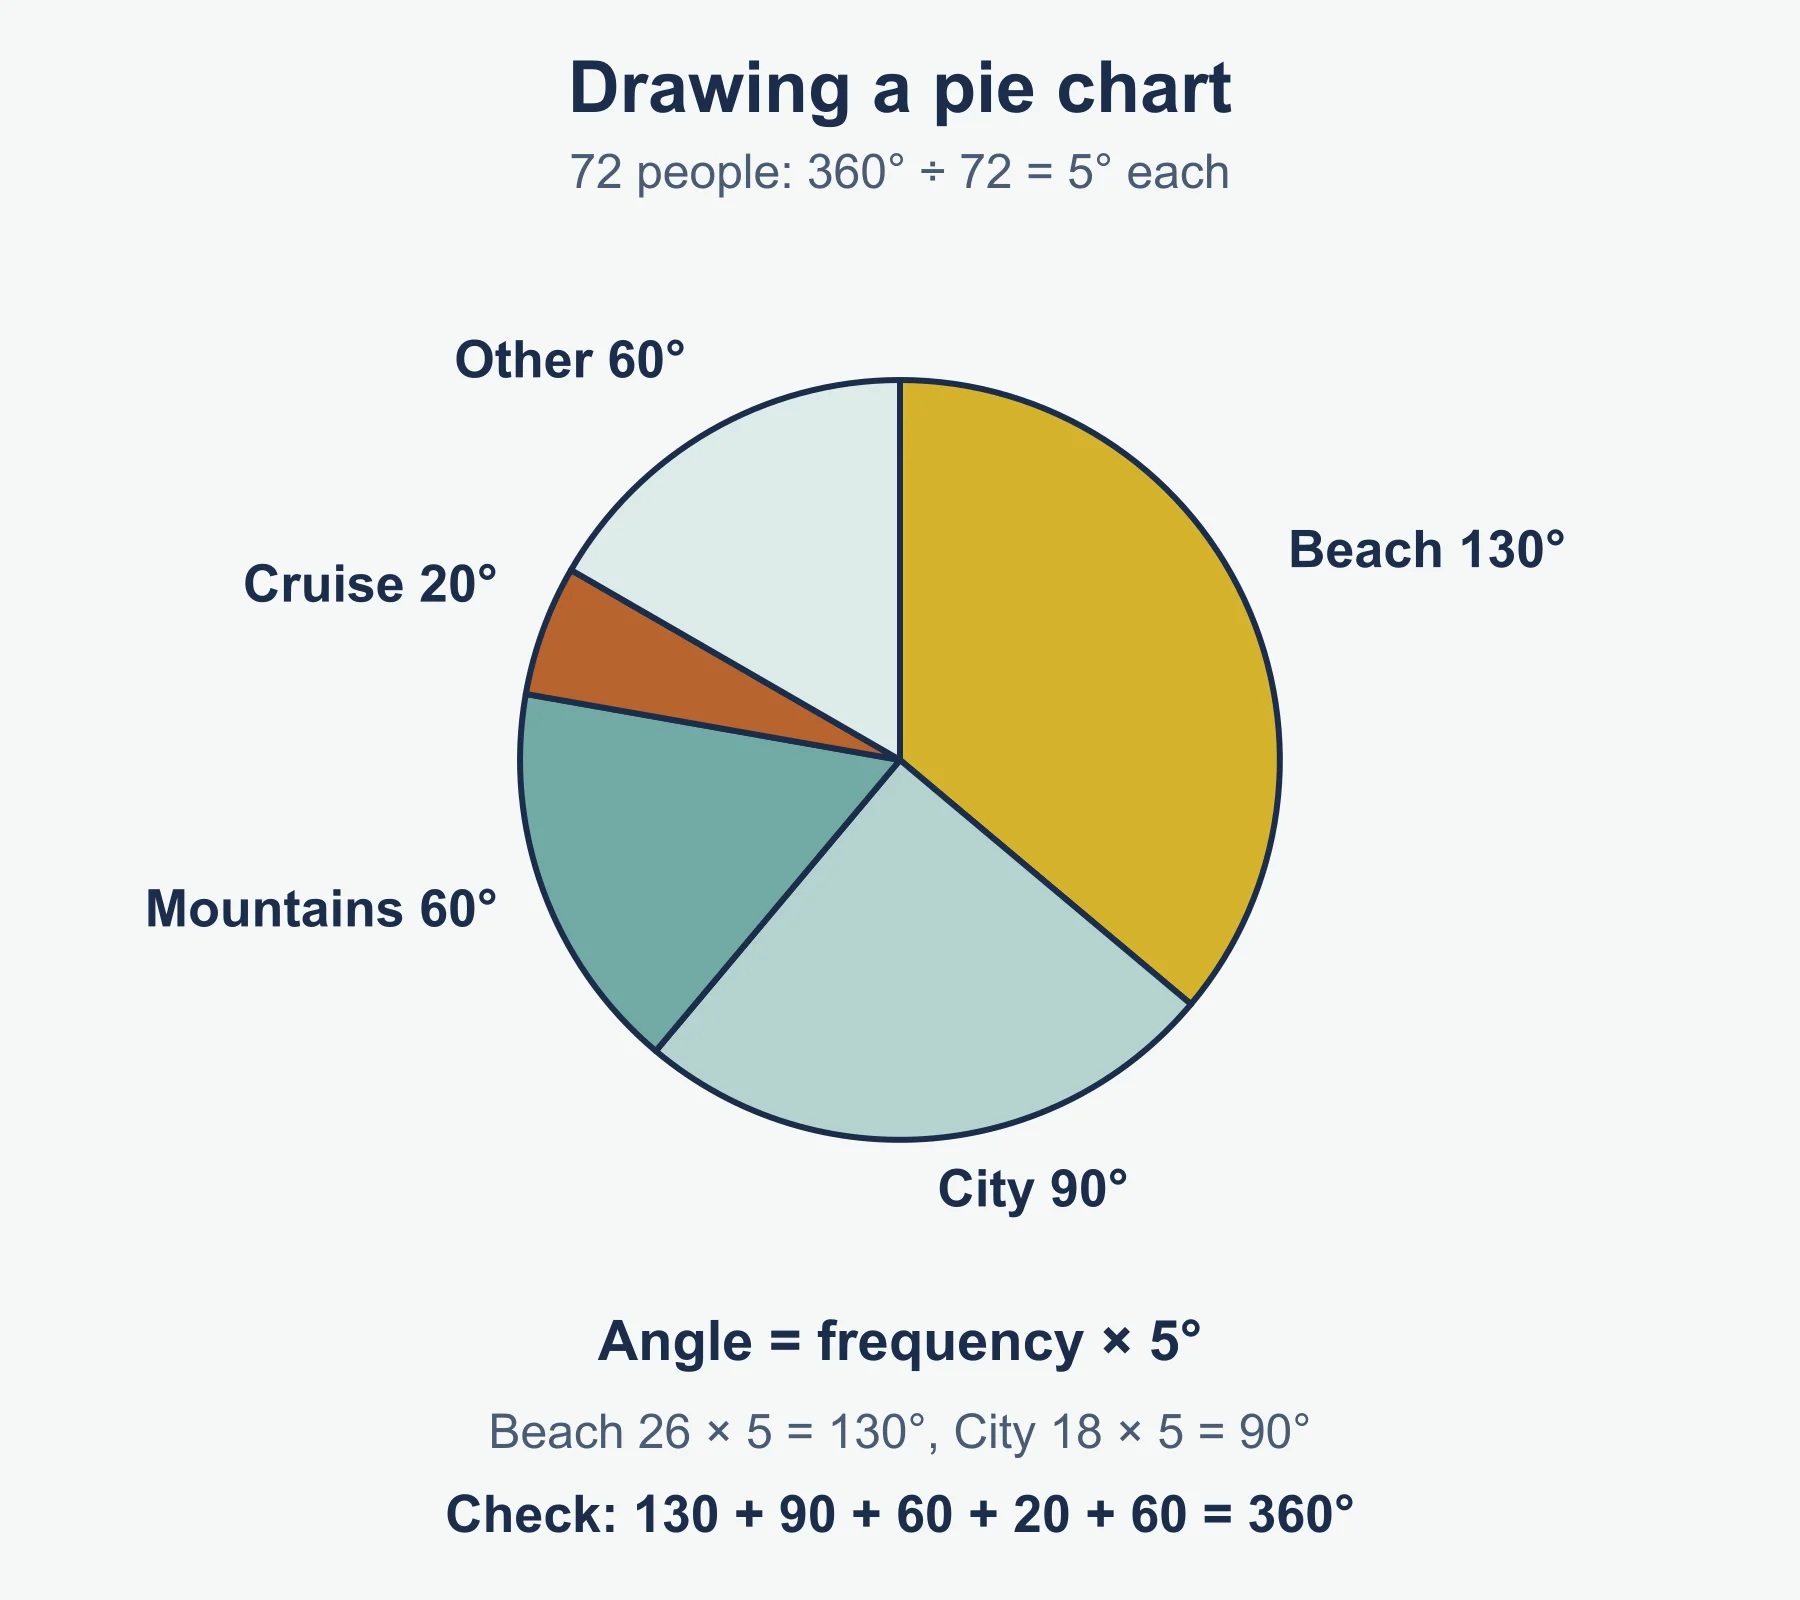
| Pie chart | Showing each category as a share of the whole |
| Vertical line chart | Ungrouped discrete data (e.g. shoe sizes) |
| Line graph | Time series: how a value changes over time |
Worked example 2 (pie chart). 72 people were asked how they travel to work: walk 18, bus 26, car 20, cycle 8.
Angle for one person = 360° ÷ 72 = 5°
Walk 18 × 5 = 90°,  Bus 26 × 5 = 130°,  Car 20 × 5 = 100°,  Cycle 8 × 5 = 40°
Check: 90 + 130 + 100 + 40 = 360°
A pie chart shows proportions, not totals. Two pie charts with the same angle can stand for different numbers of people if the totals are different.
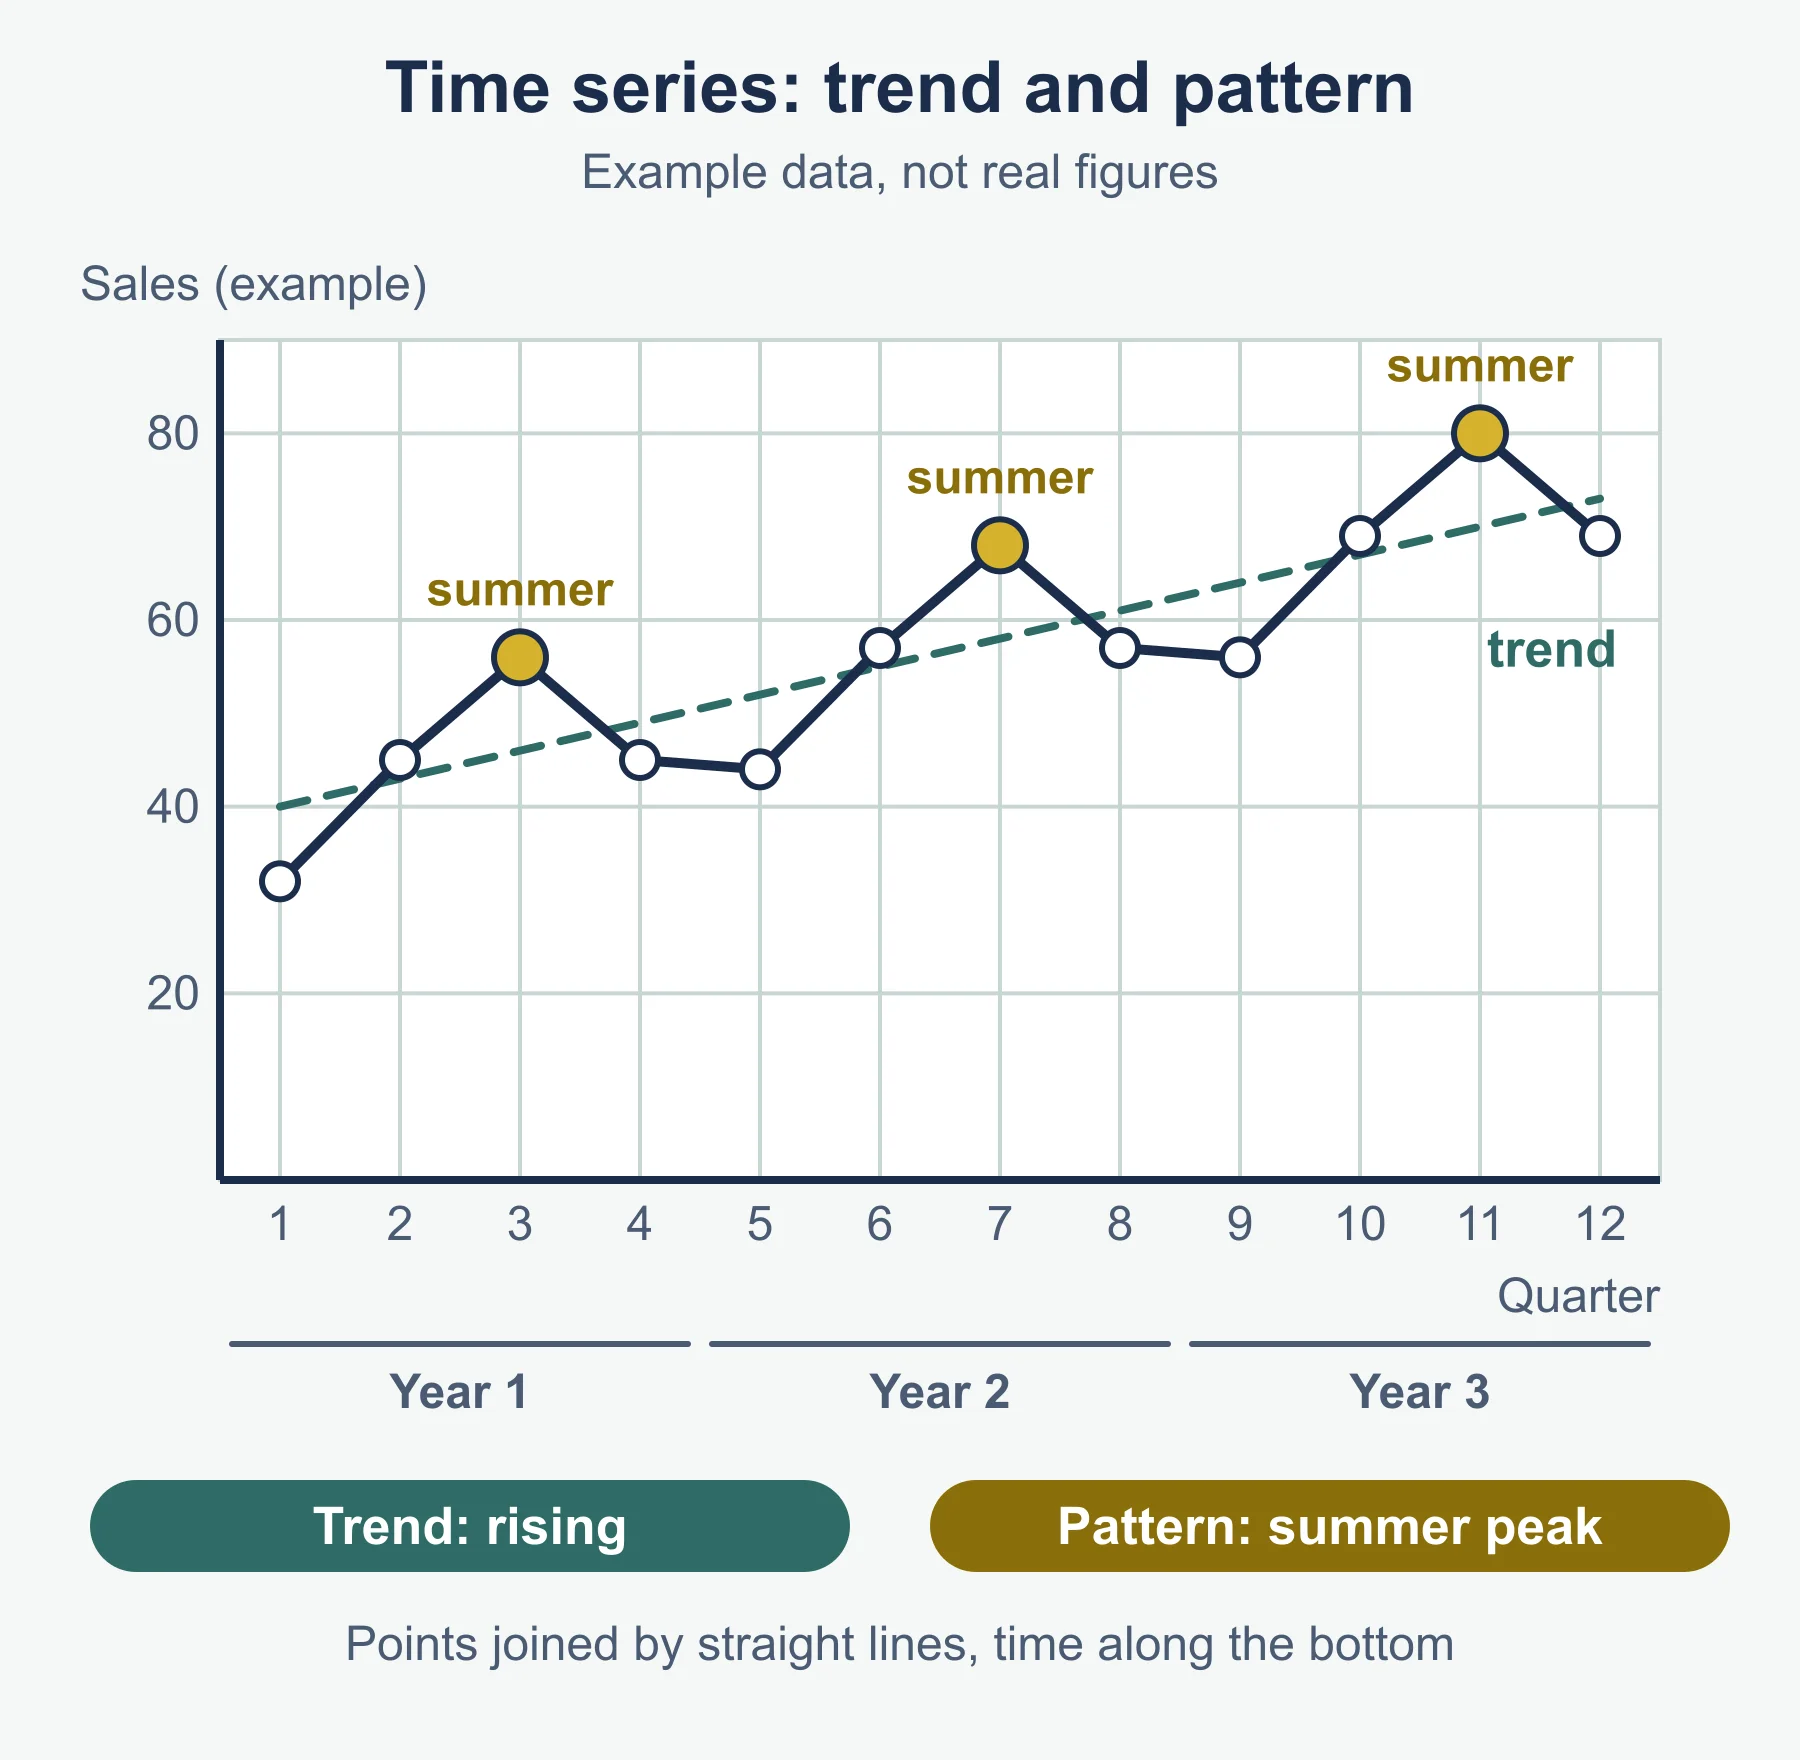
Time series. Plot time along the horizontal axis and join the points with straight lines. Describe the trend (the general rise or fall) and any repeating pattern, such as sales that peak every summer.
Averages and spread (S4)
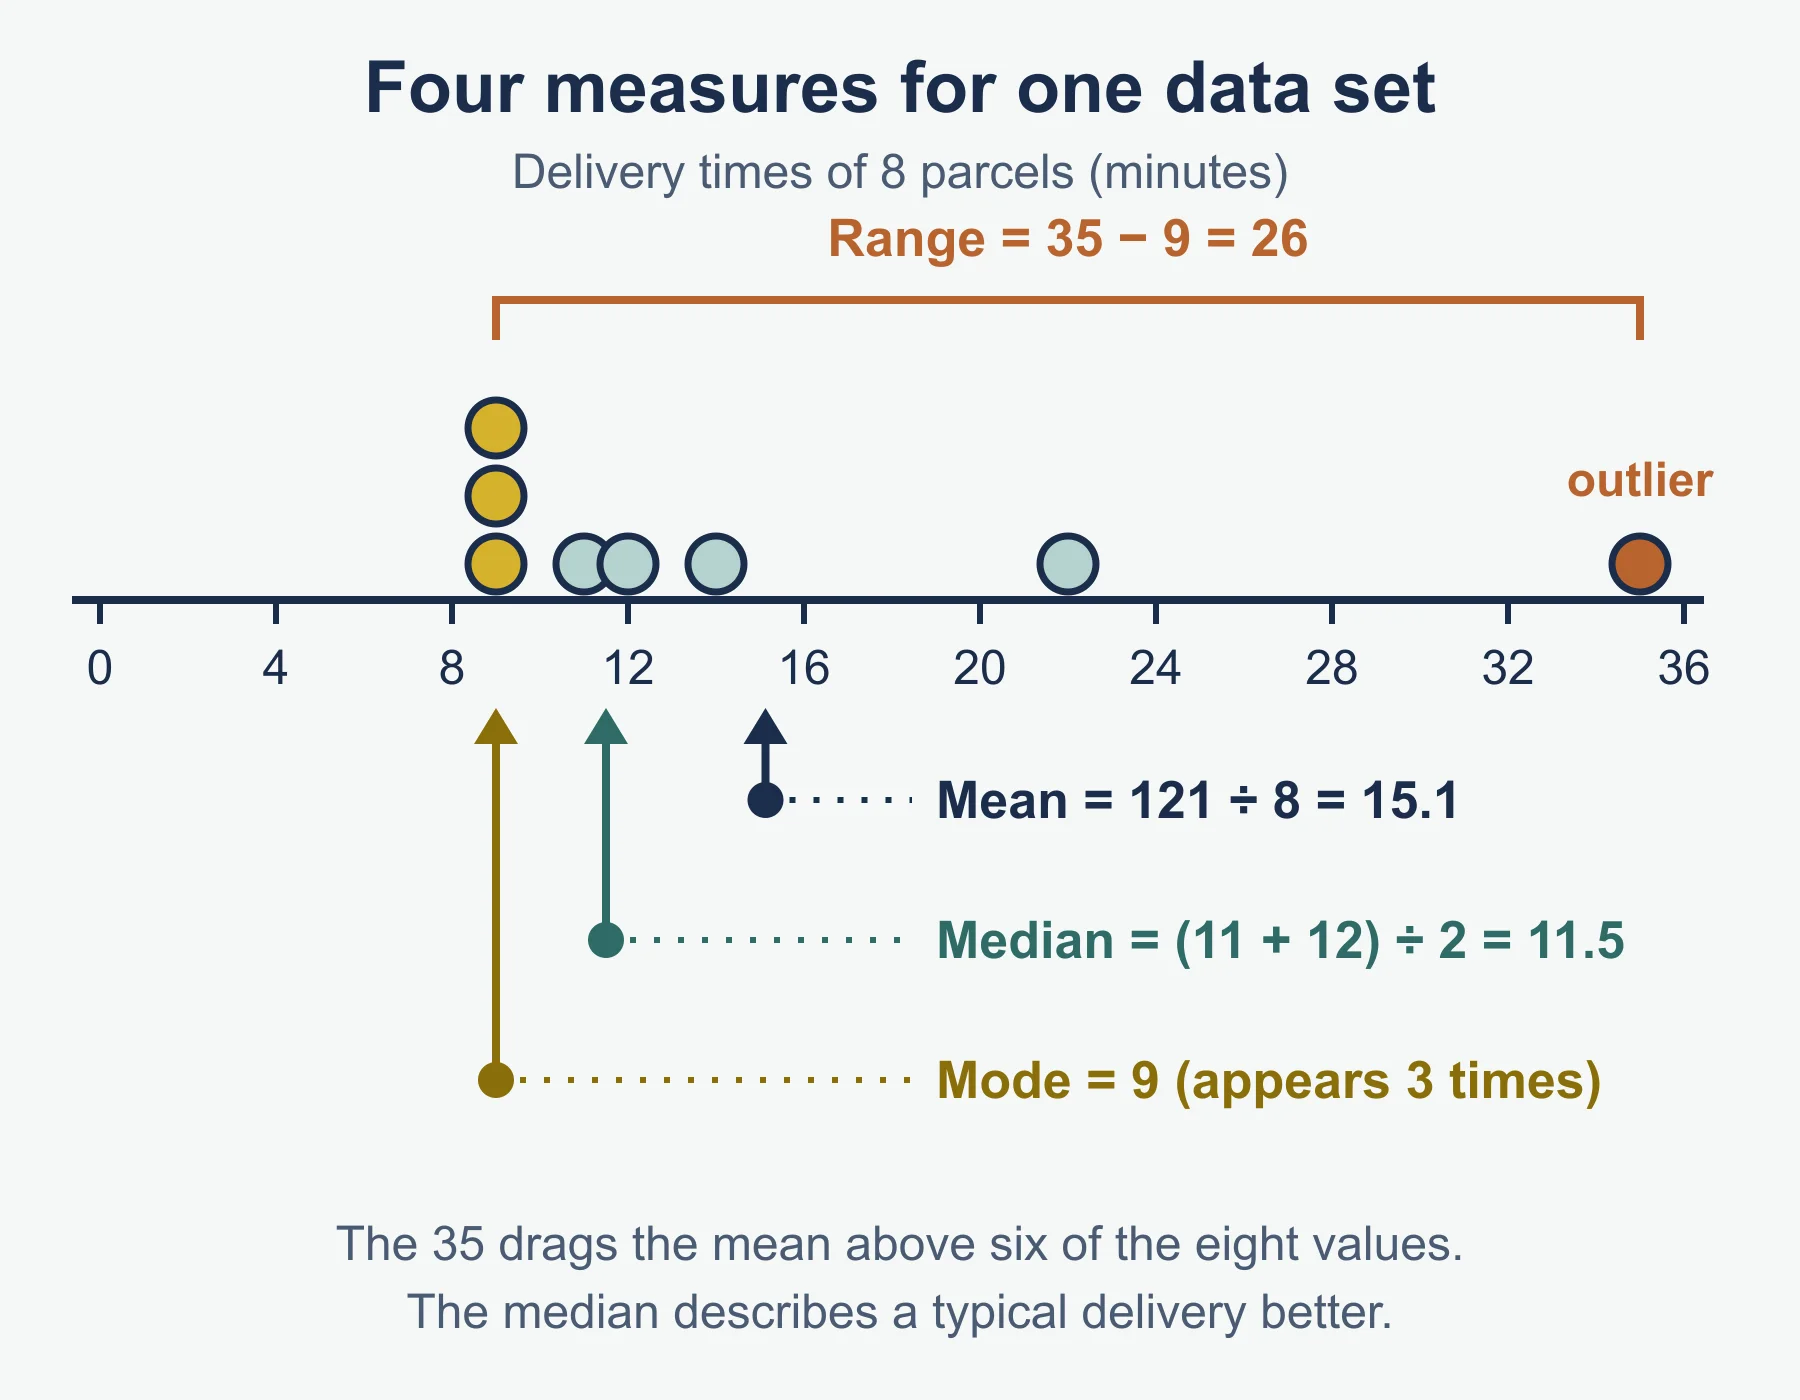
| Measure | How to find it |
|---|---|
| Mean | Total of values ÷ number of values |
| Median | Middle value when in order; position (n + 1)/2 |
| Mode | Most common value (or modal class for grouped data) |
| Range | Largest − smallest; a measure of spread |
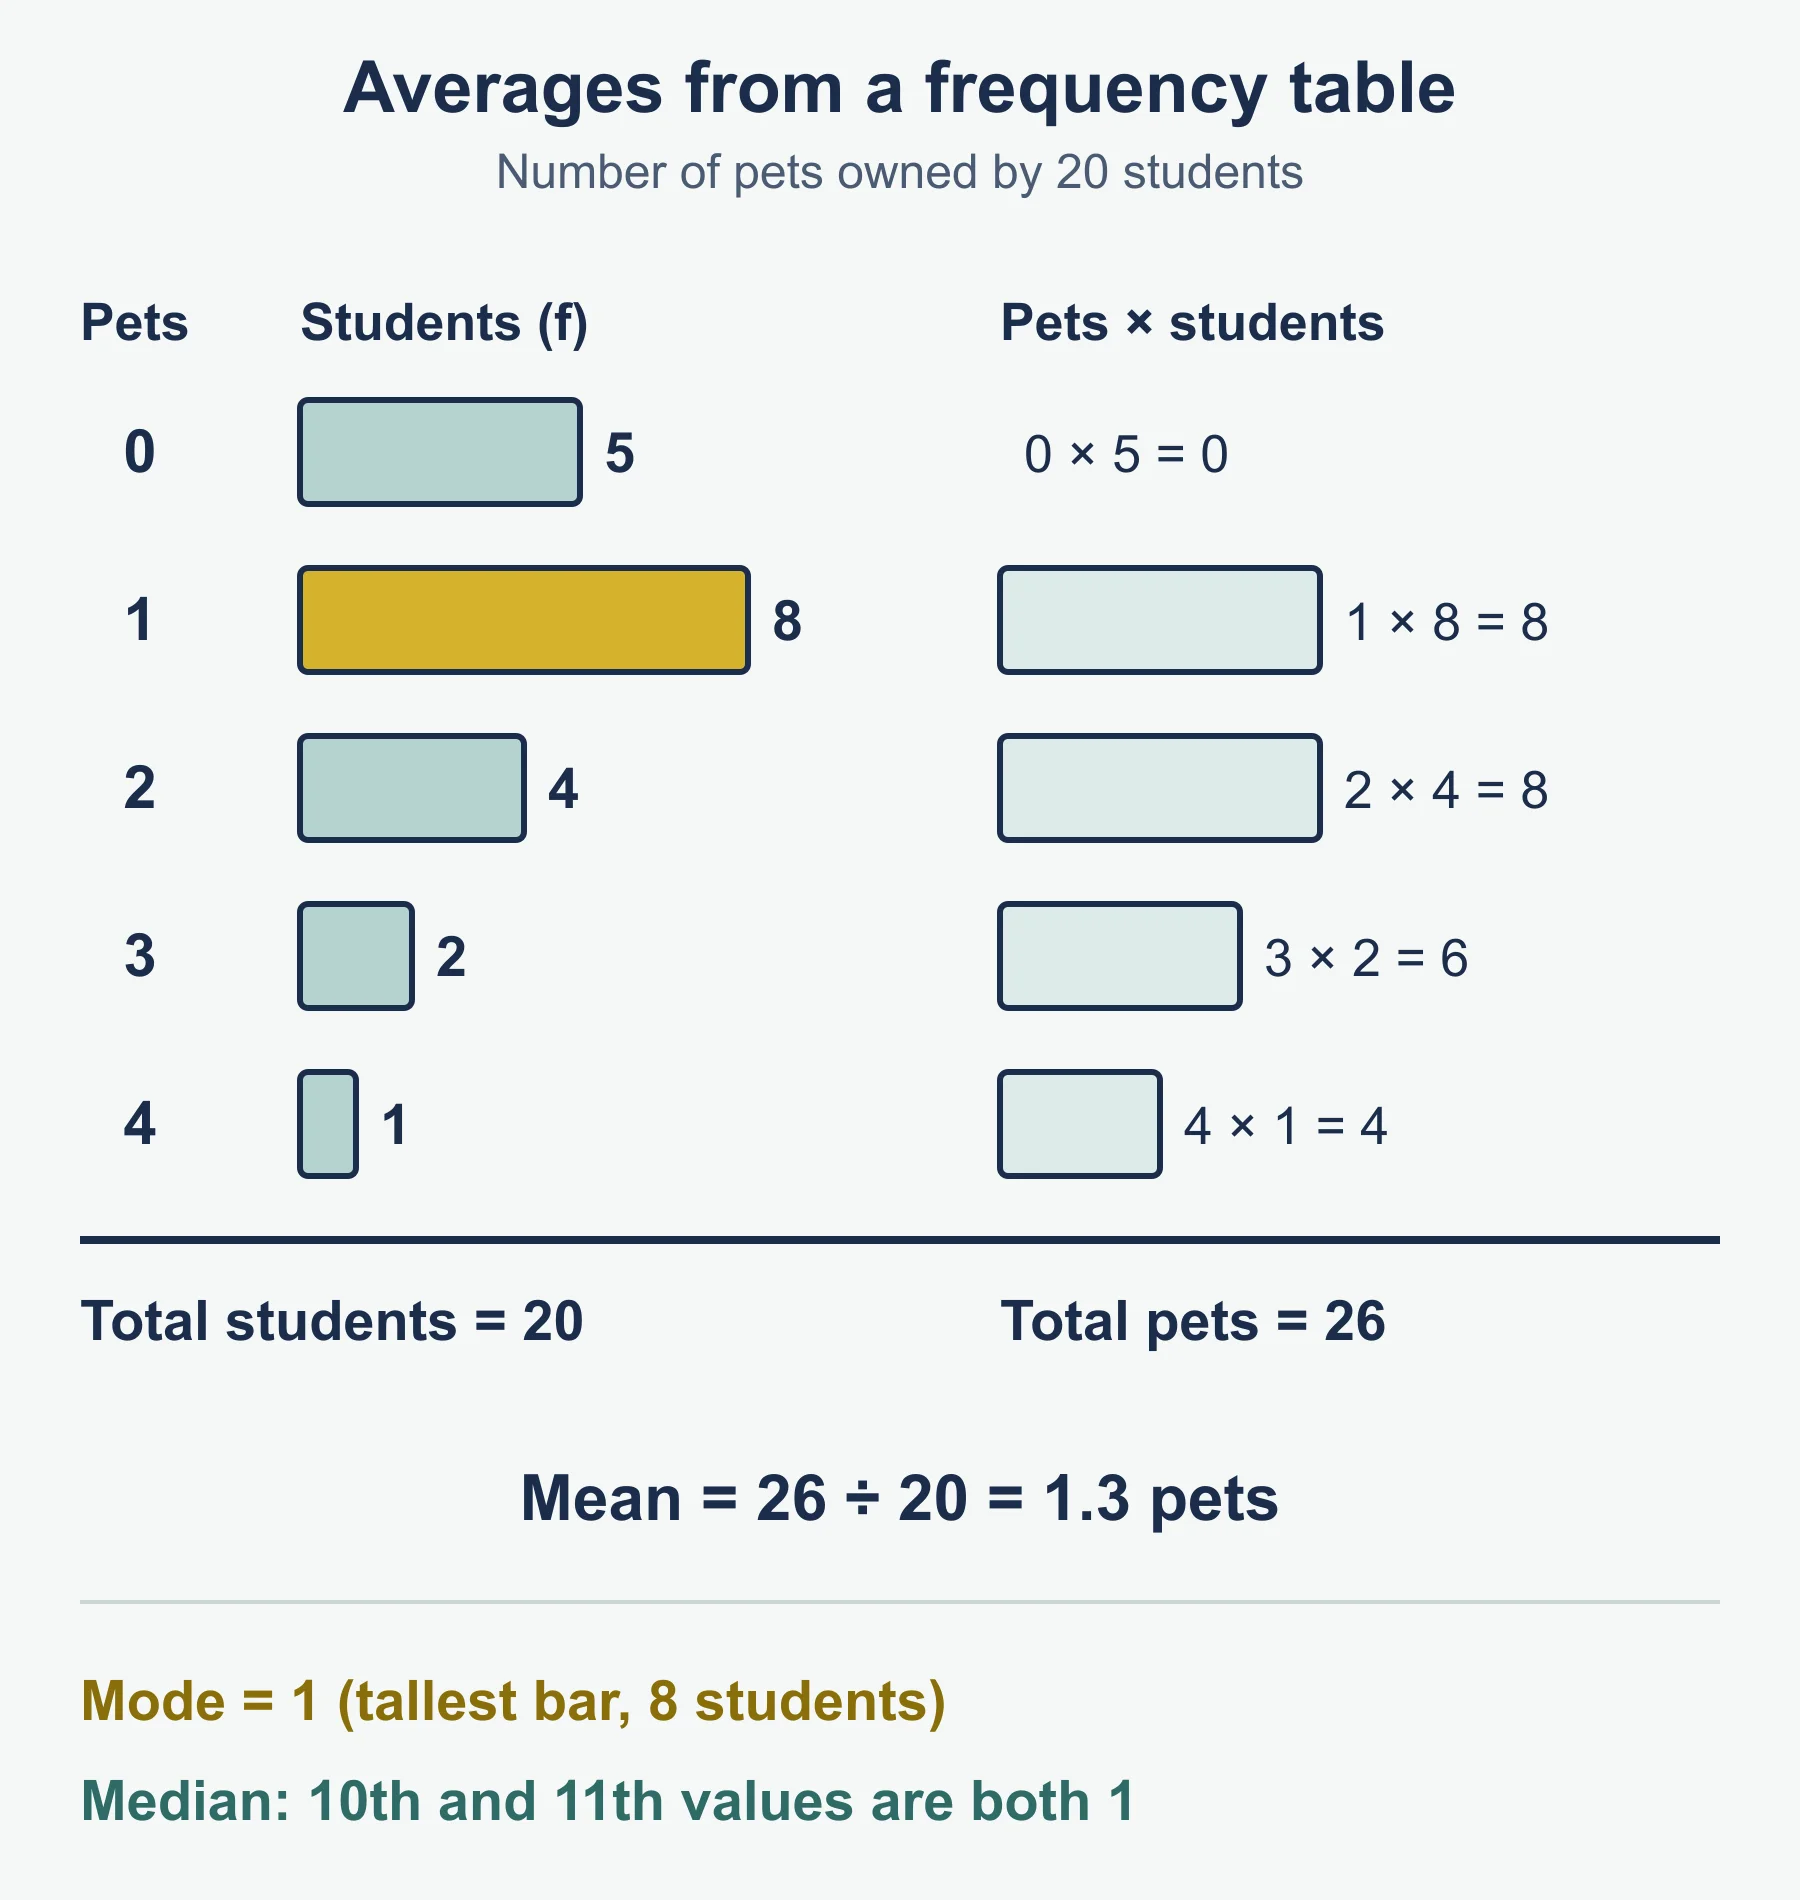
Worked example 3 (frequency table). Goals scored in 20 matches:
| Goals | 0 | 1 | 2 | 3 | 4 |
|---|---|---|---|---|---|
| Frequency | 4 | 7 | 5 | 3 | 1 |
Total goals = 0×4 + 1×7 + 2×5 + 3×3 + 4×1 = 30
Mean = 30 ÷ 20 = 1.5 goals
Median: position (20 + 1)/2 = 10.5, so between the 10th and 11th values.
Running totals 4, 11, ... so the 10th and 11th are both 1. Median = 1
Mode = 1 (highest frequency).  Range = 4 − 0 = 4
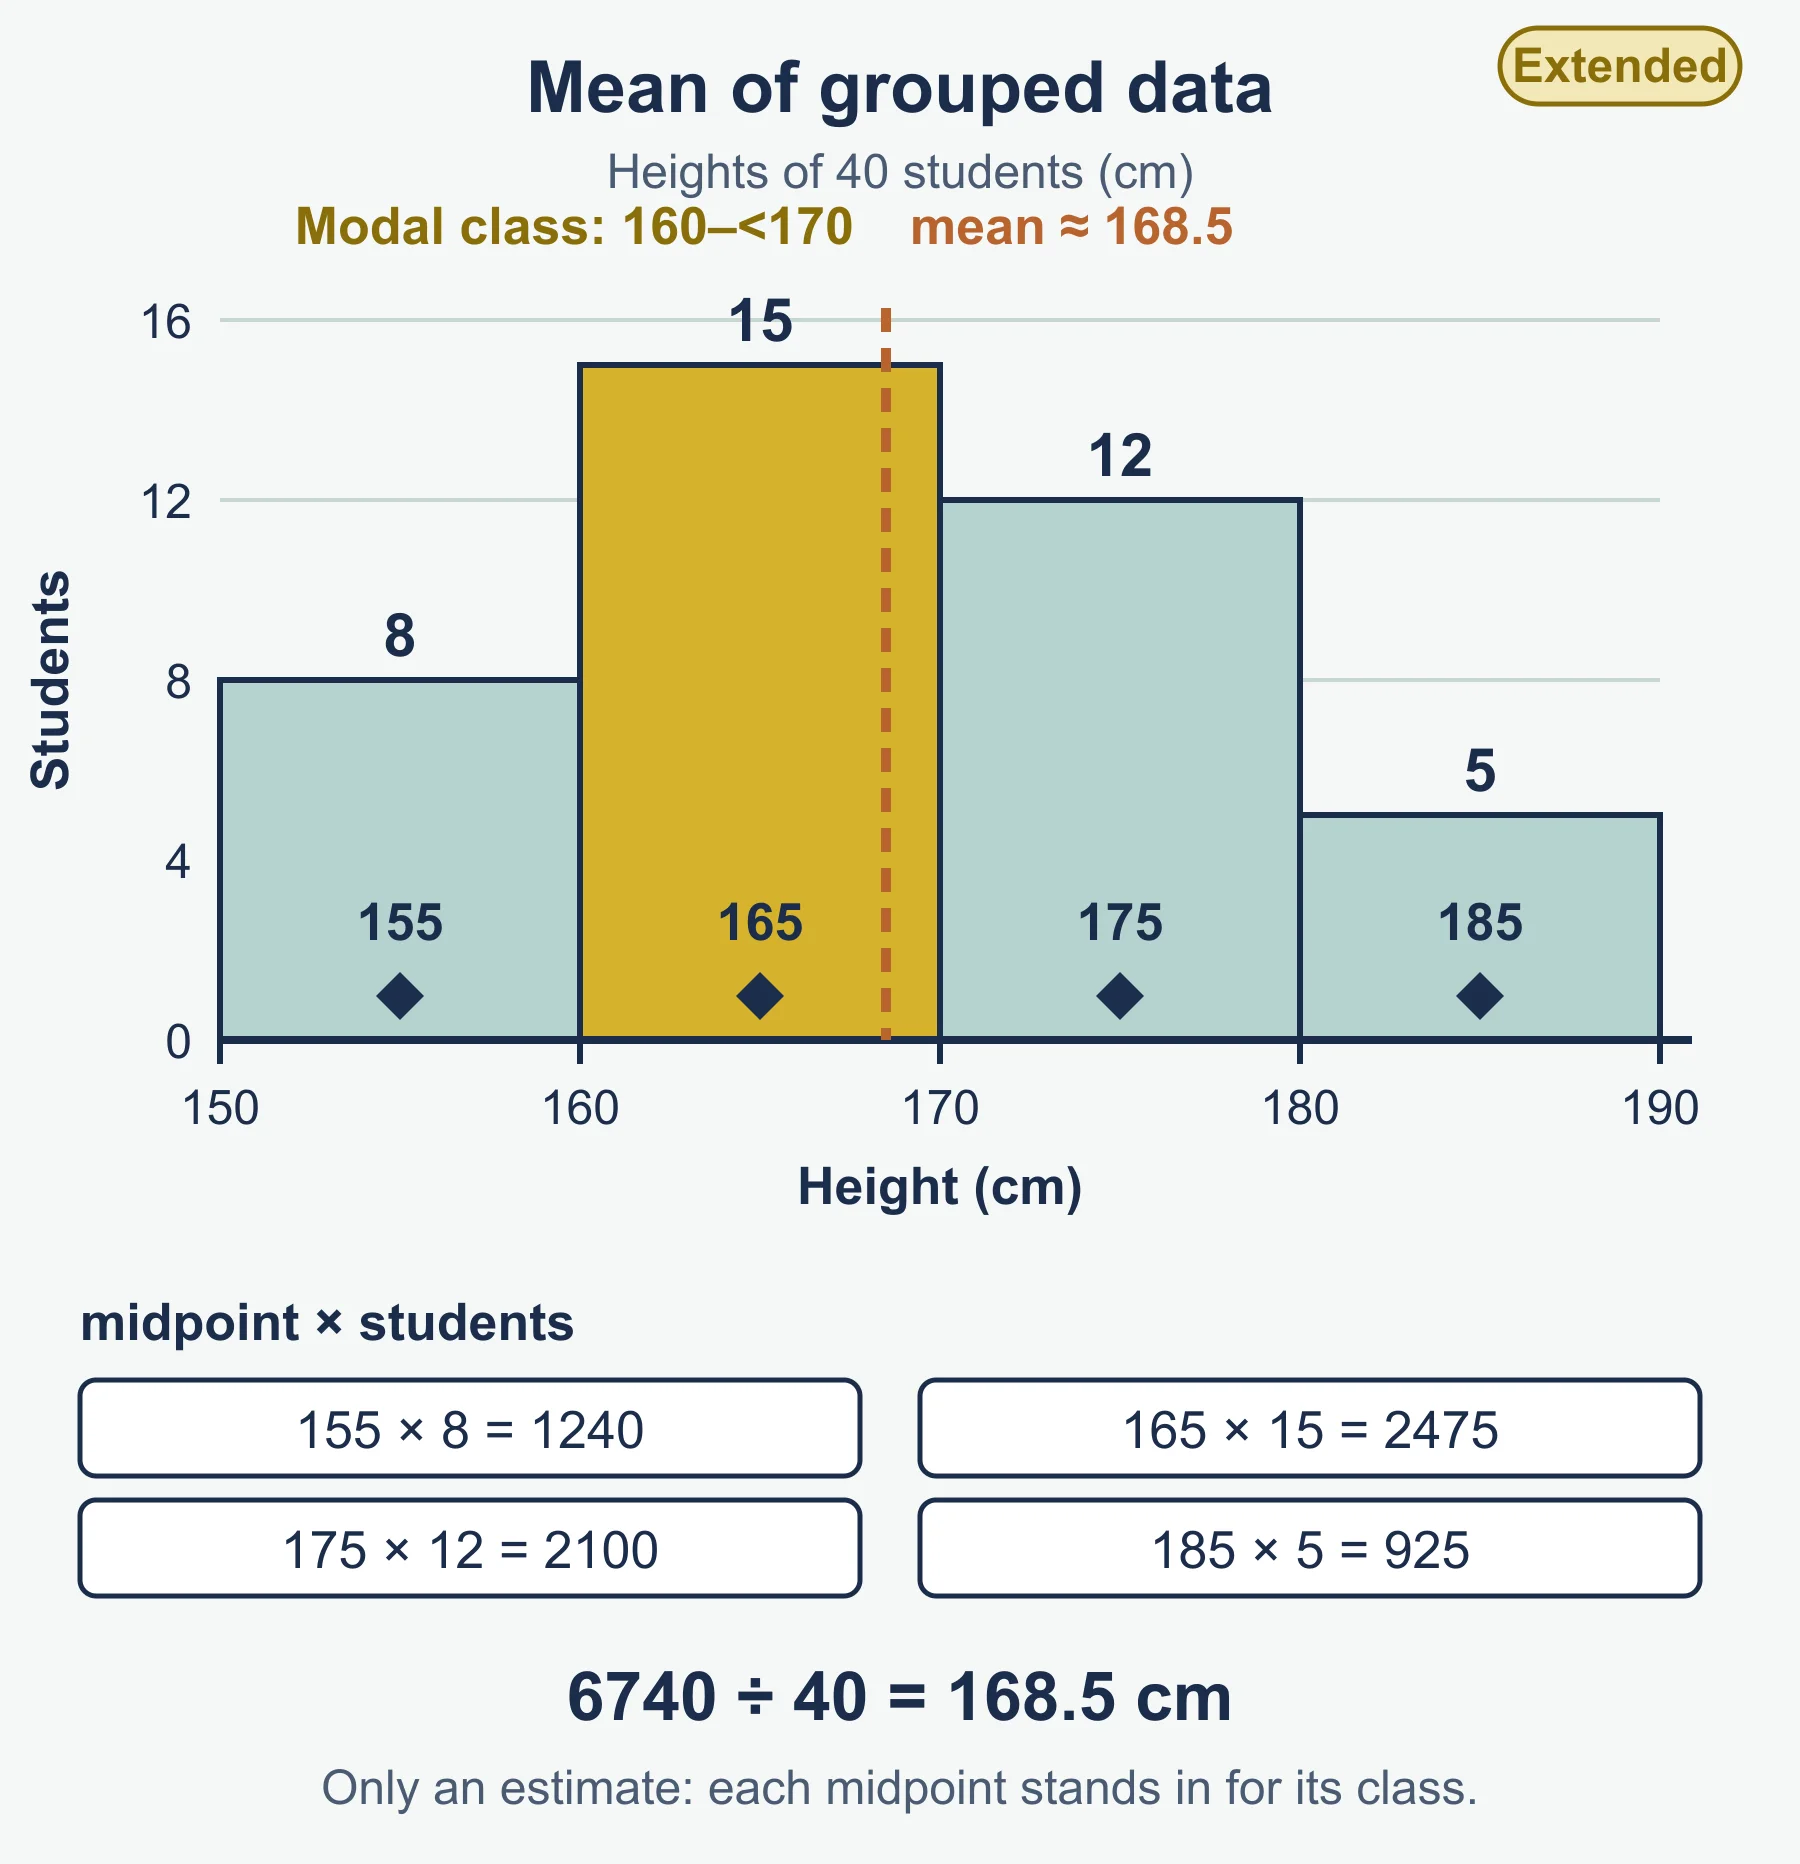
Worked example 4 (grouped data). Time, t minutes, 40 people waited:
| Time (minutes) | 0 < t ≤ 10 | 10 < t ≤ 20 | 20 < t ≤ 30 | 30 < t ≤ 40 |
|---|---|---|---|---|
| Frequency | 4 | 15 | 12 | 9 |
Use the midpoint of each class as a stand-in for every value in it.
Midpoints: 5, 15, 25, 35
Σ(midpoint × frequency) = 20 + 225 + 300 + 315 = 860
Estimated mean = 860 ÷ 40 = 21.5 minutes
Modal class: 10 < t ≤ 20
Running totals 4, 19, 31, 40: the 20th and 21st values are in 20 < t ≤ 30
The mean is only an estimate because you do not know the exact values in each class.
Outliers
An outlier is a value far from the rest. For 12, 14, 15, 15, 16, 17, 18, 41 the mean is 18.5, but without 41 it is about 15.3. The median barely moves (15.5 to 15). The range drops from 29 to 6. When there is an outlier, the median is usually the better average, and the range is not a reliable measure of spread.
Comparing distributions
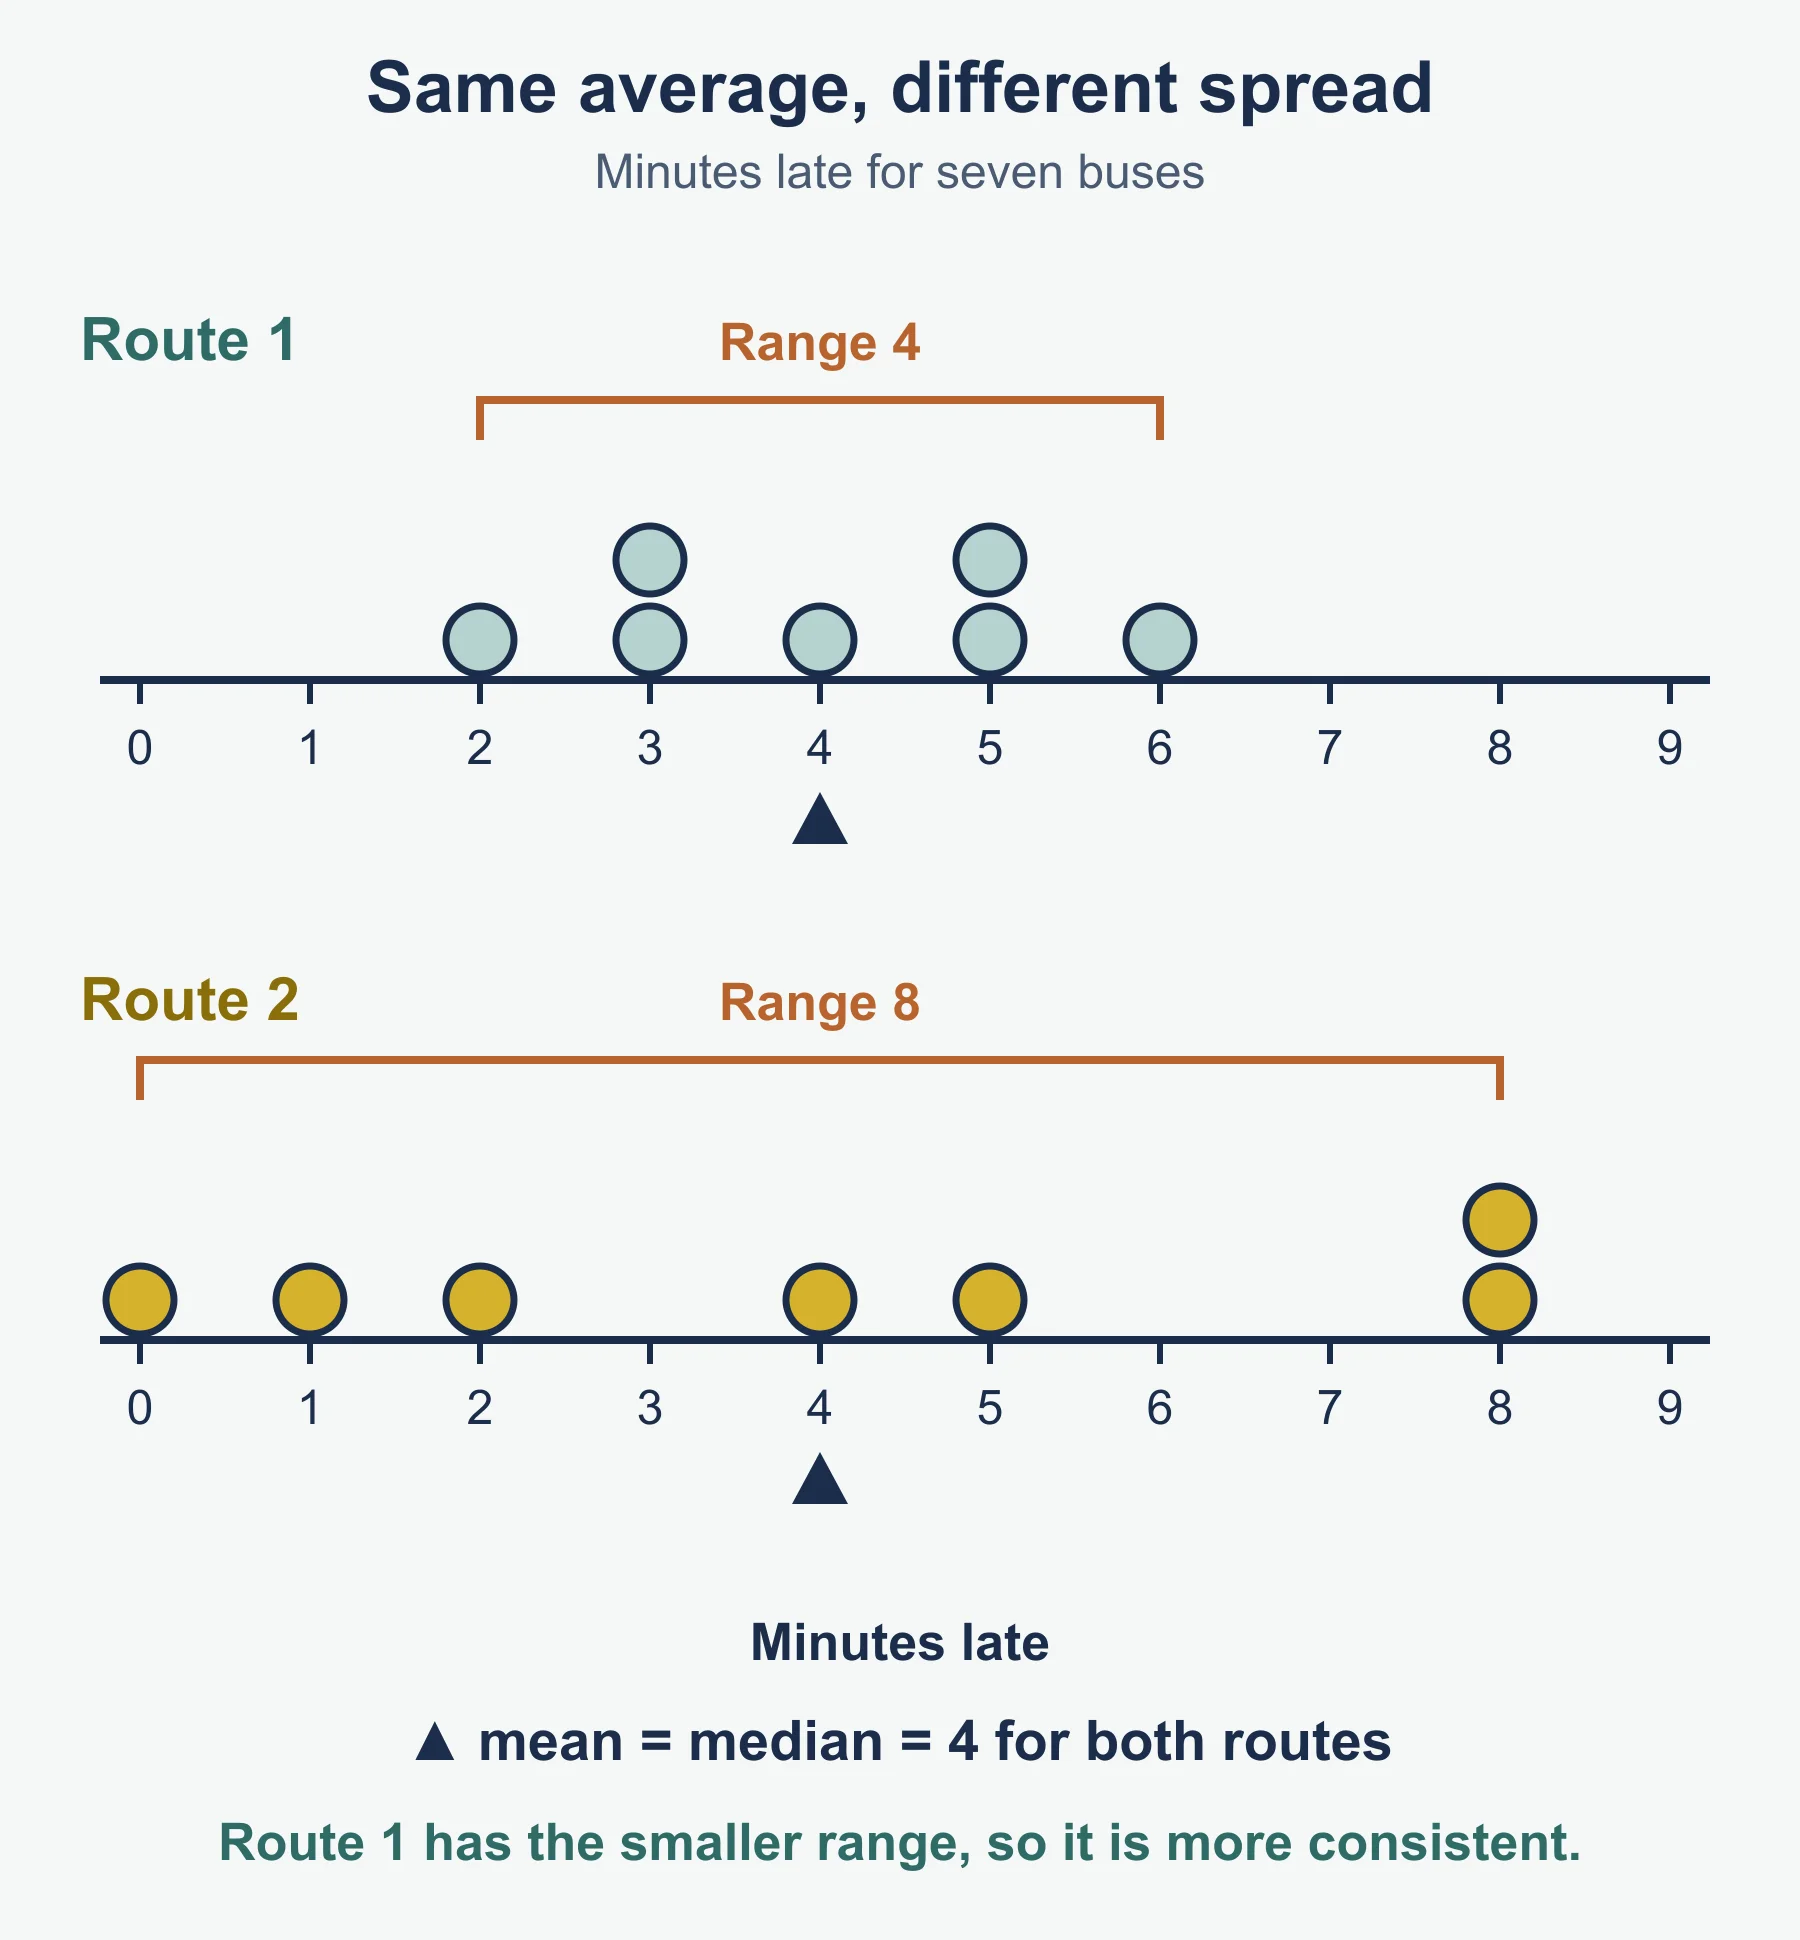
Always make two comparisons: one of an average and one of a spread, each in the context of the question.
Example: Class A has median 62 and range 30. Class B has median 55 and range 48. “On average Class A scored higher, because its median is higher. Class A’s scores were more consistent, because its range is smaller.”
Histograms and cumulative frequency (S3) – Higher tier only
Histograms
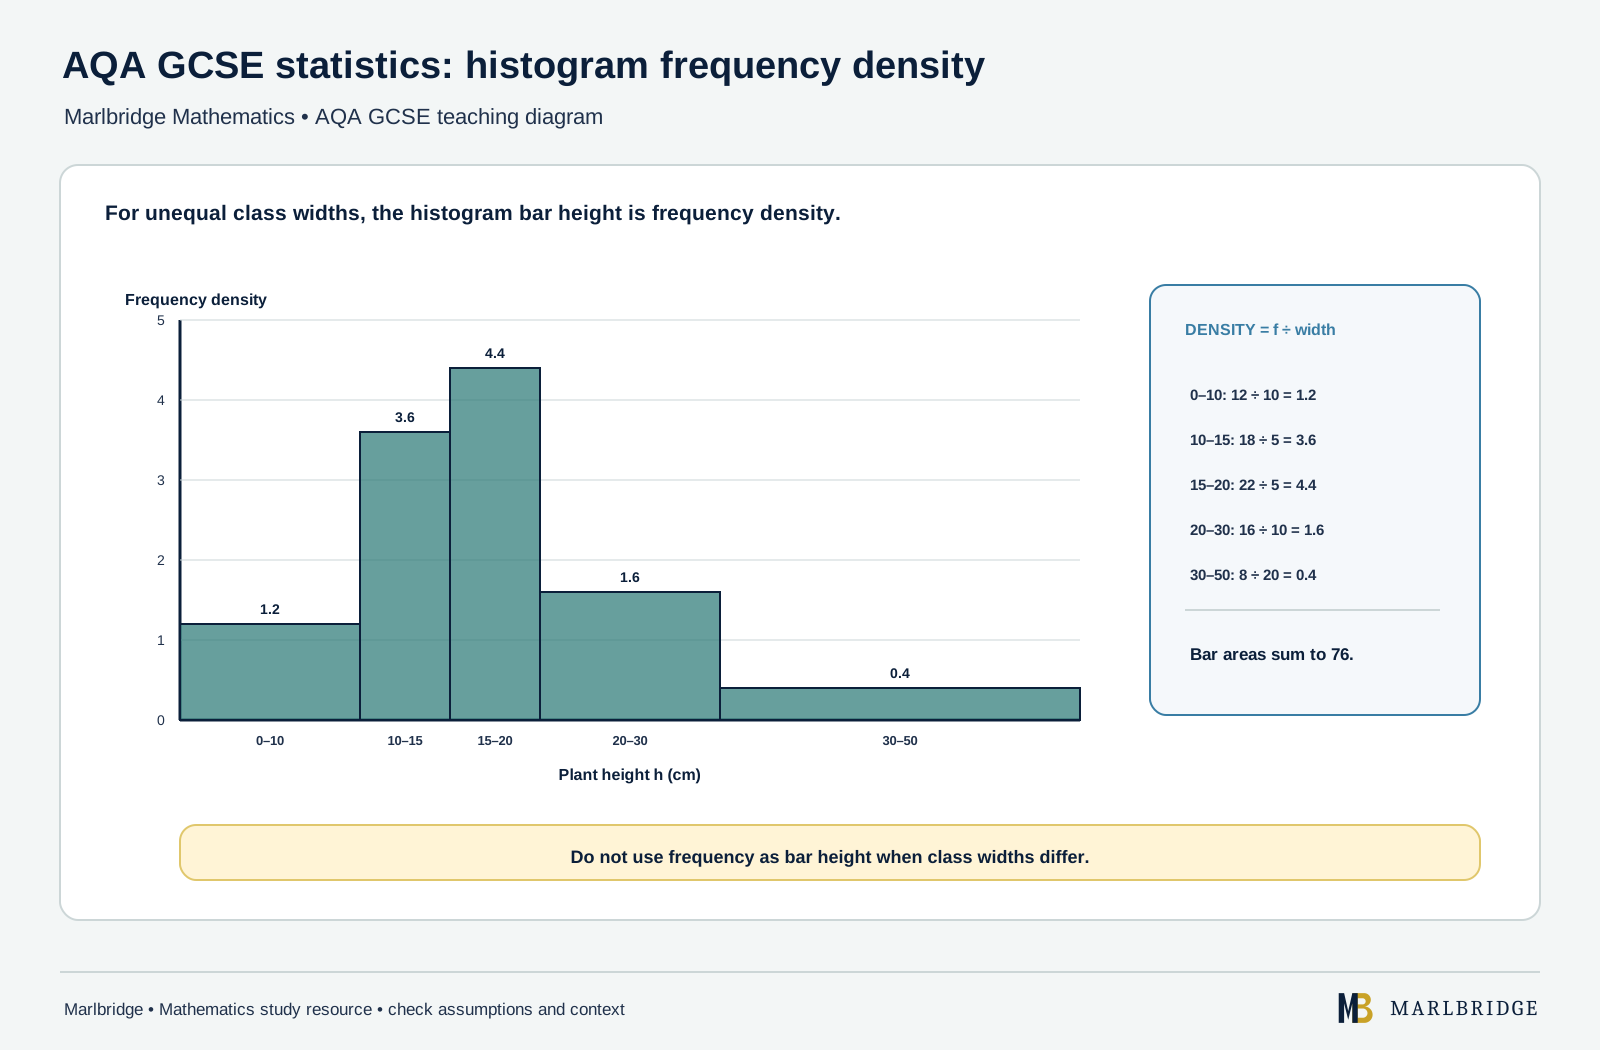
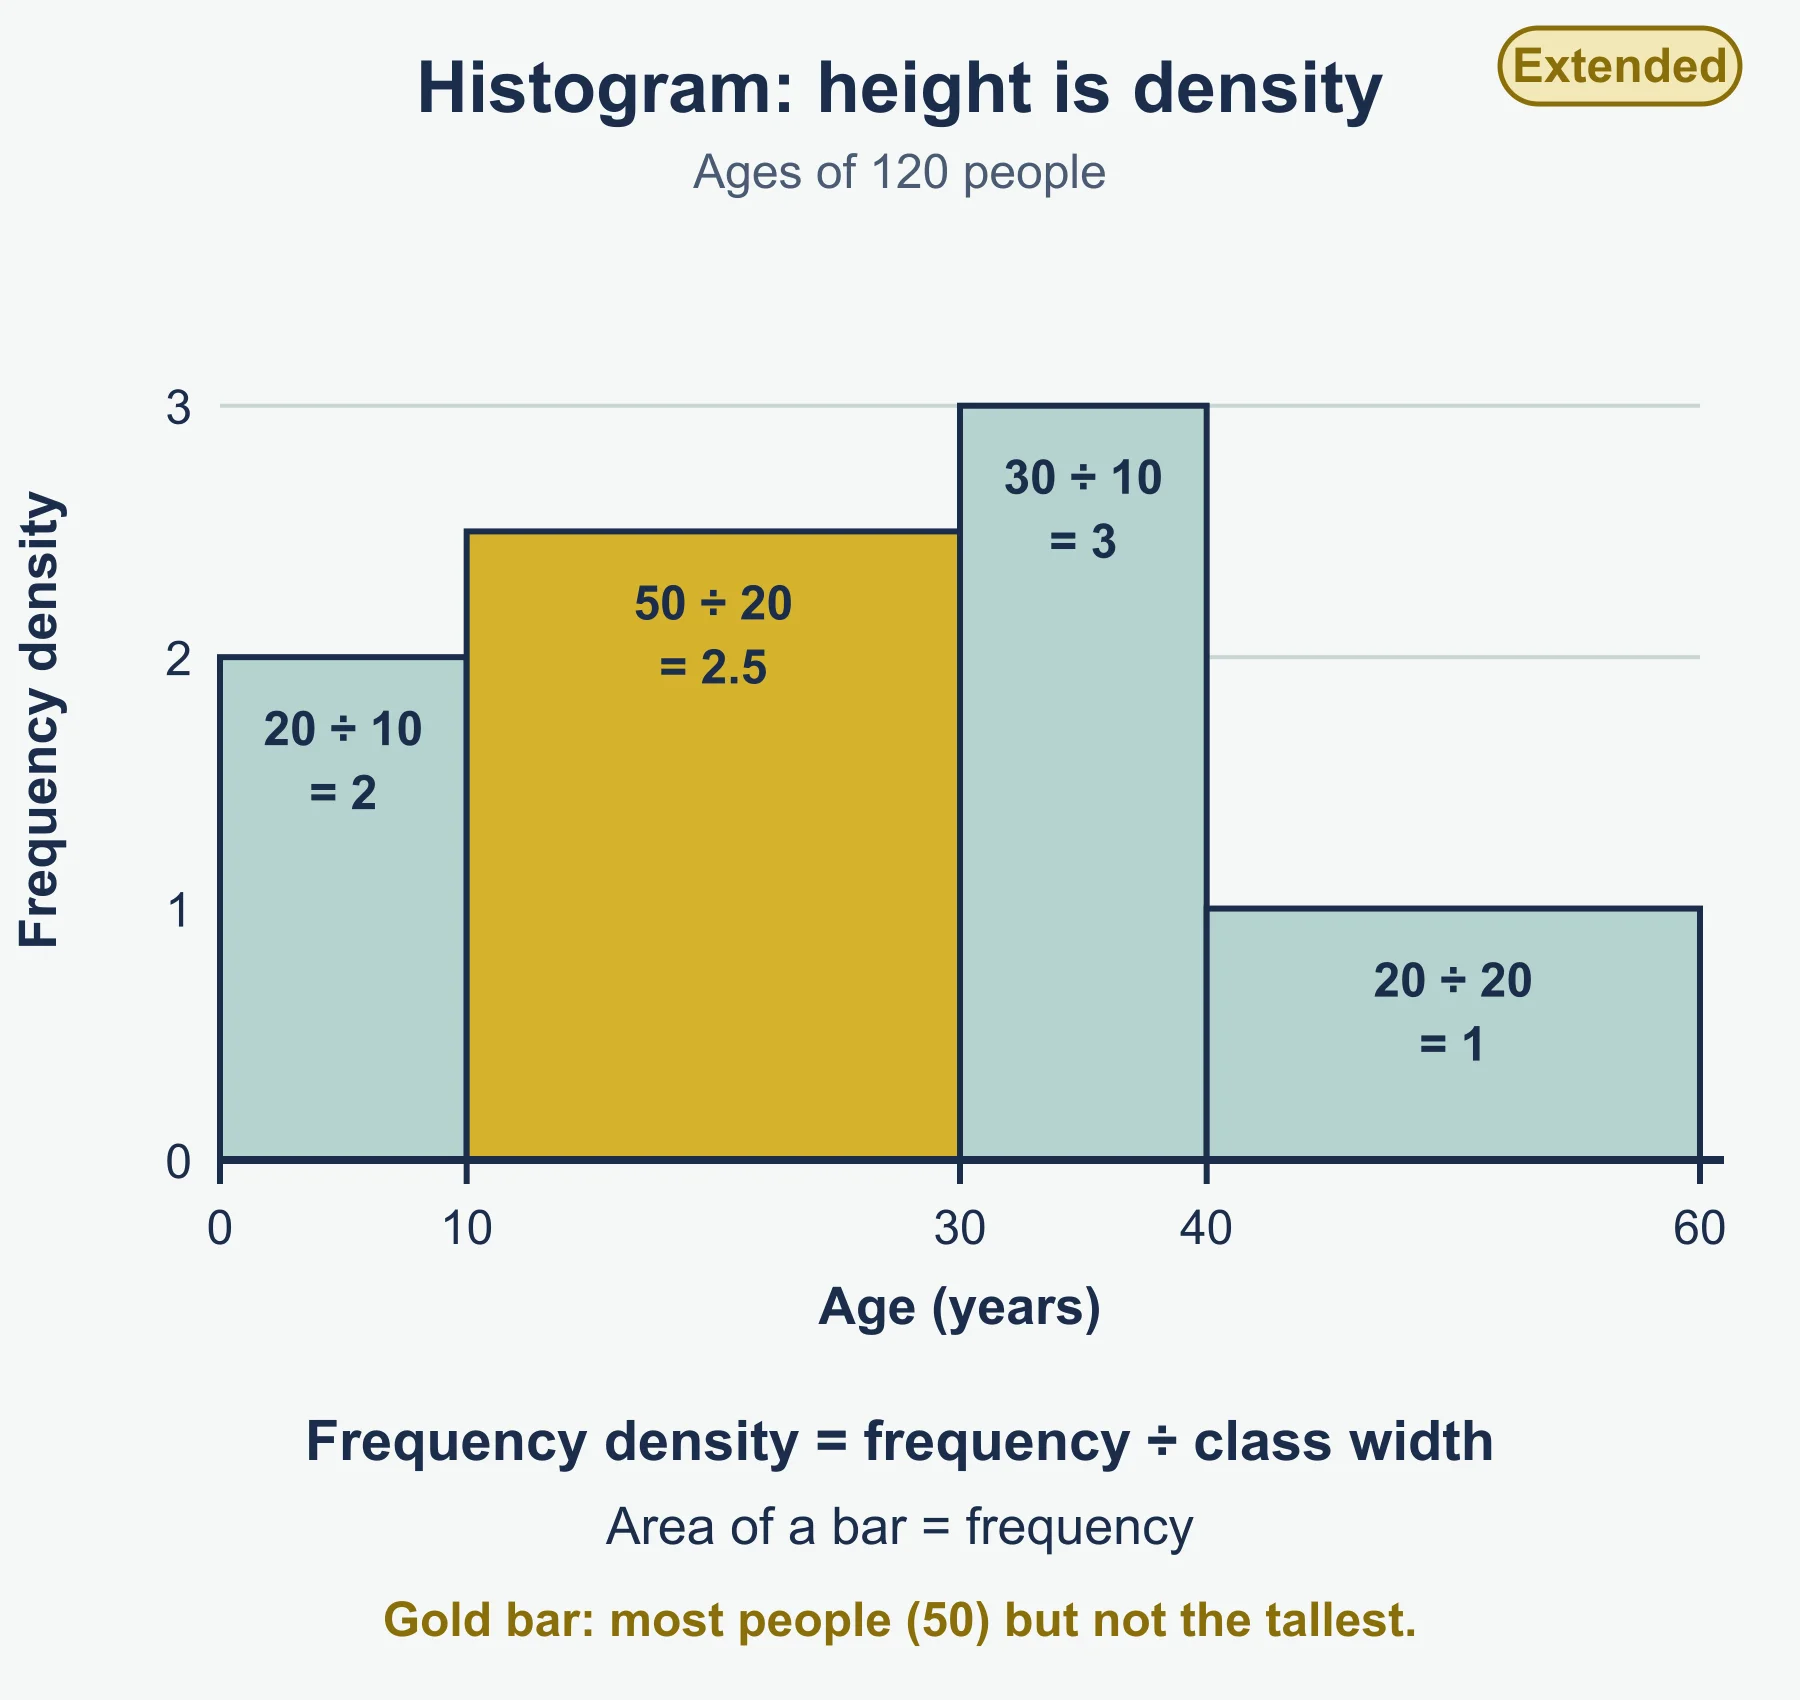
In a histogram the area of each bar stands for the frequency. The height is the frequency density:
frequency density = frequency ÷ class width
Worked example 5. Heights of 76 plants:
| Height h (cm) | 0 < h ≤ 10 | 10 < h ≤ 15 | 15 < h ≤ 20 | 20 < h ≤ 30 | 30 < h ≤ 50 |
|---|---|---|---|---|---|
| Frequency | 12 | 18 | 22 | 16 | 8 |
| Frequency density | 1.2 | 3.6 | 4.4 | 1.6 | 0.4 |
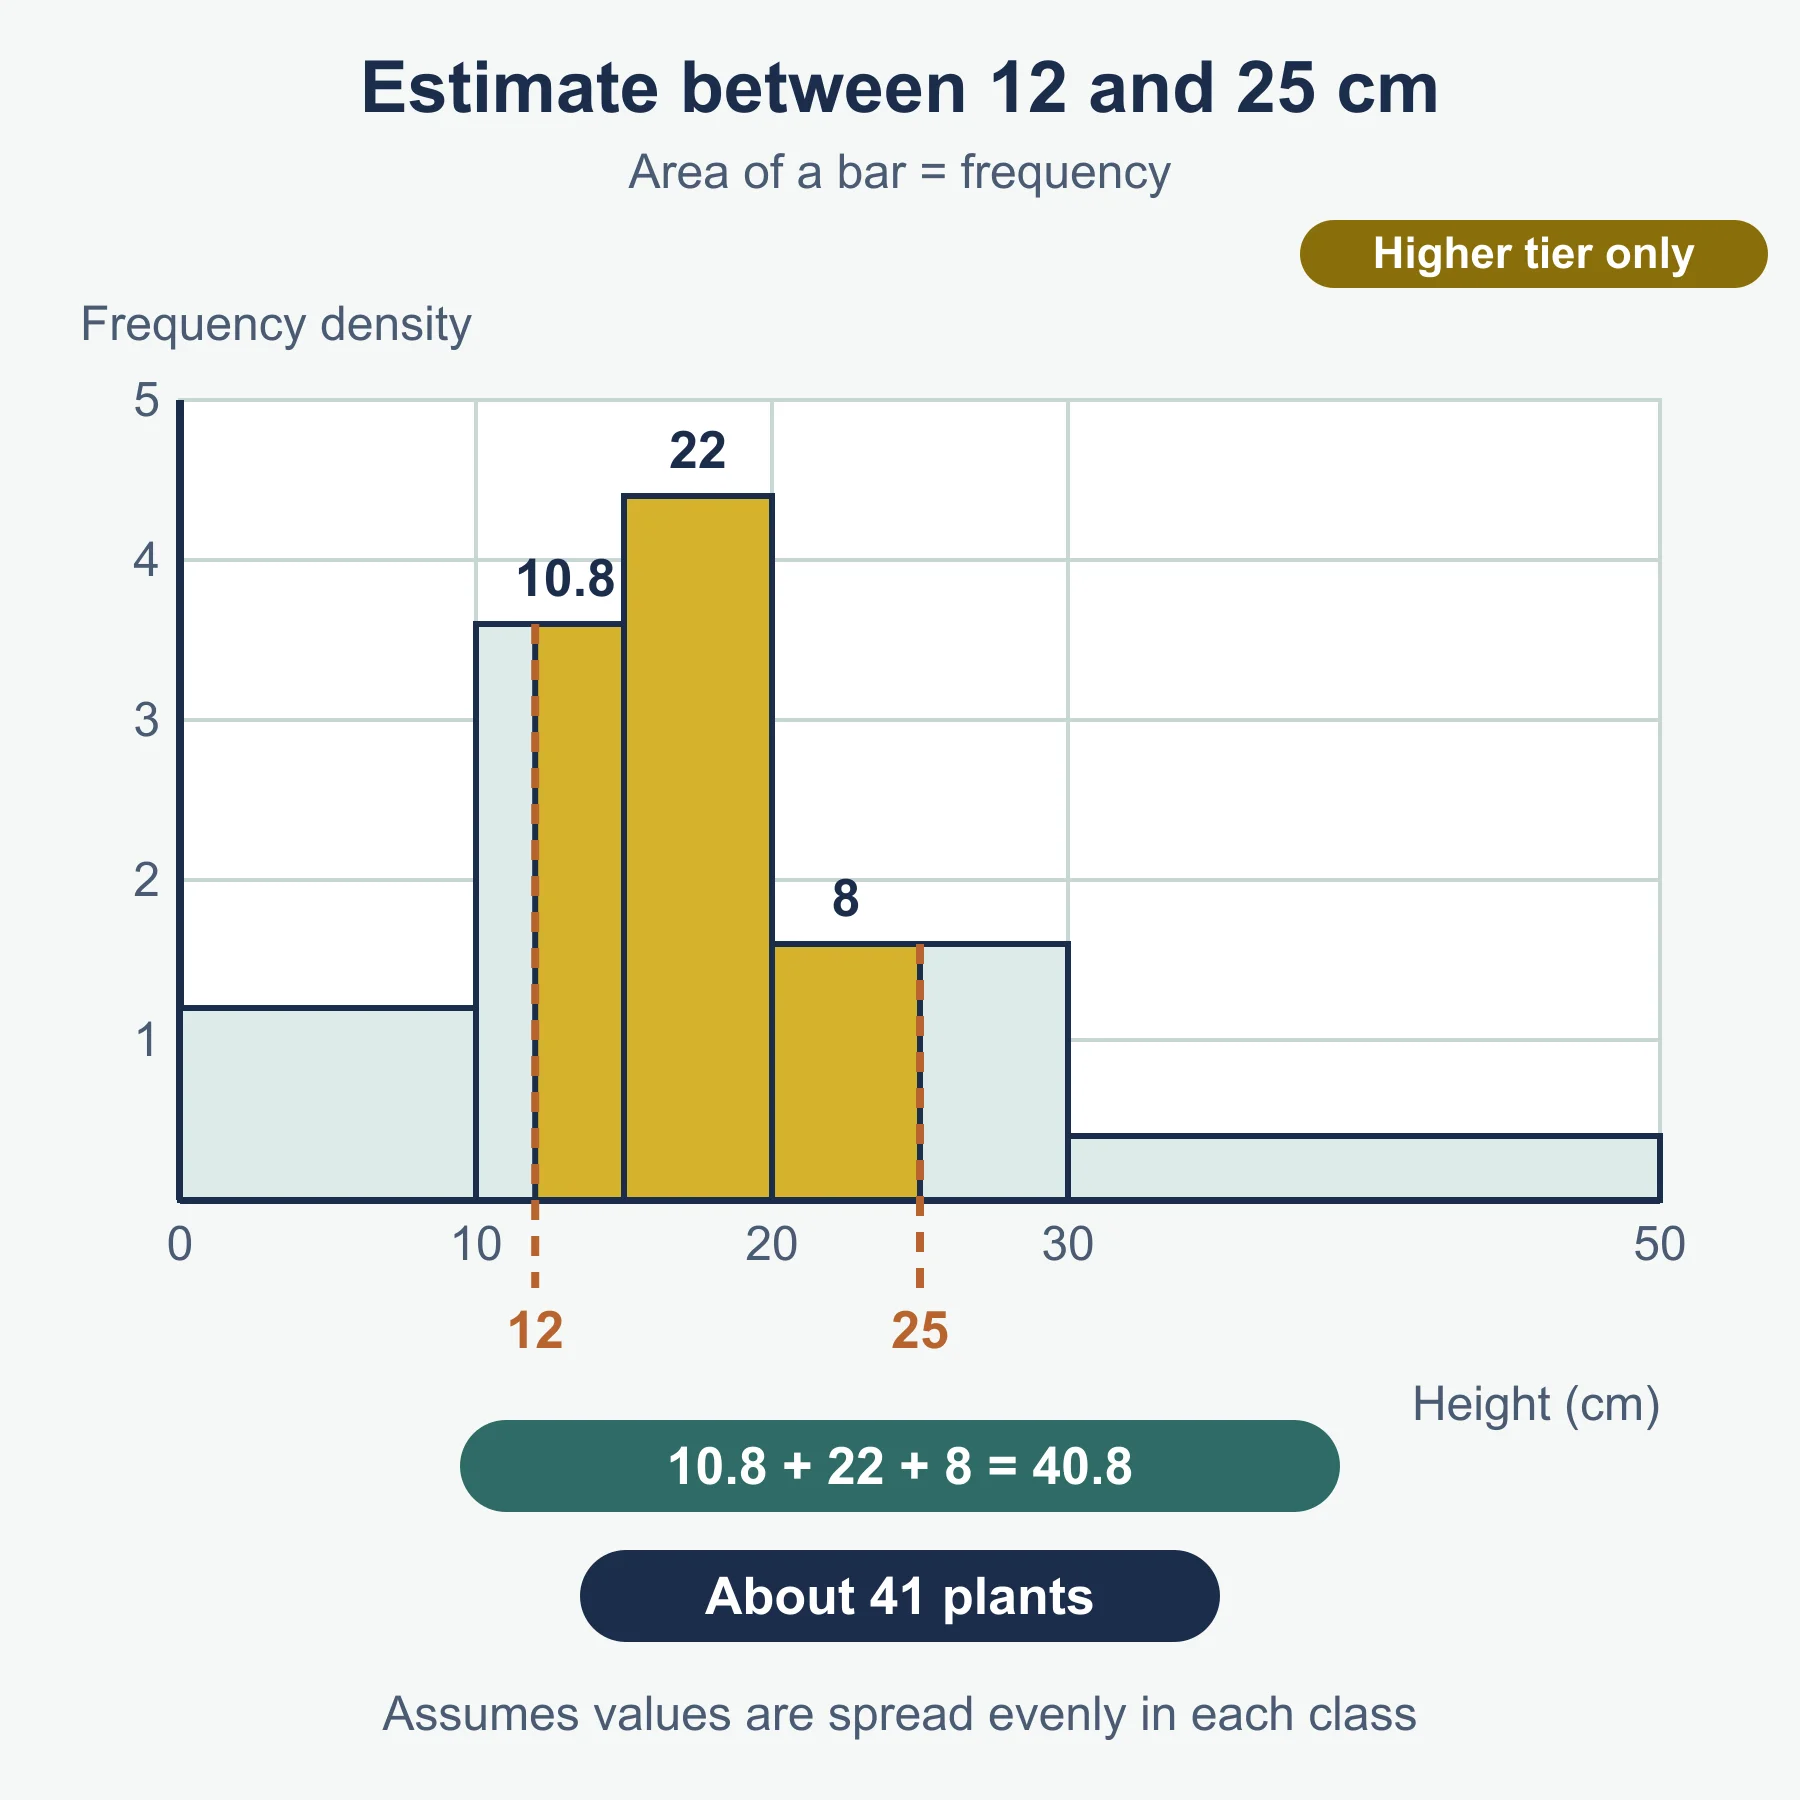
Estimate how many plants are between 12 cm and 25 cm:
10 < h ≤ 15: the part from 12 to 15 is 3/5 of the class → 3/5 × 18 = 10.8
15 < h ≤ 20: all 22
20 < h ≤ 30: the part from 20 to 25 is 5/10 of the class → 5/10 × 16 = 8
Total ≈ 10.8 + 22 + 8 = 40.8, about 41 plants
This assumes values are spread evenly within each class.
Cumulative frequency graphs
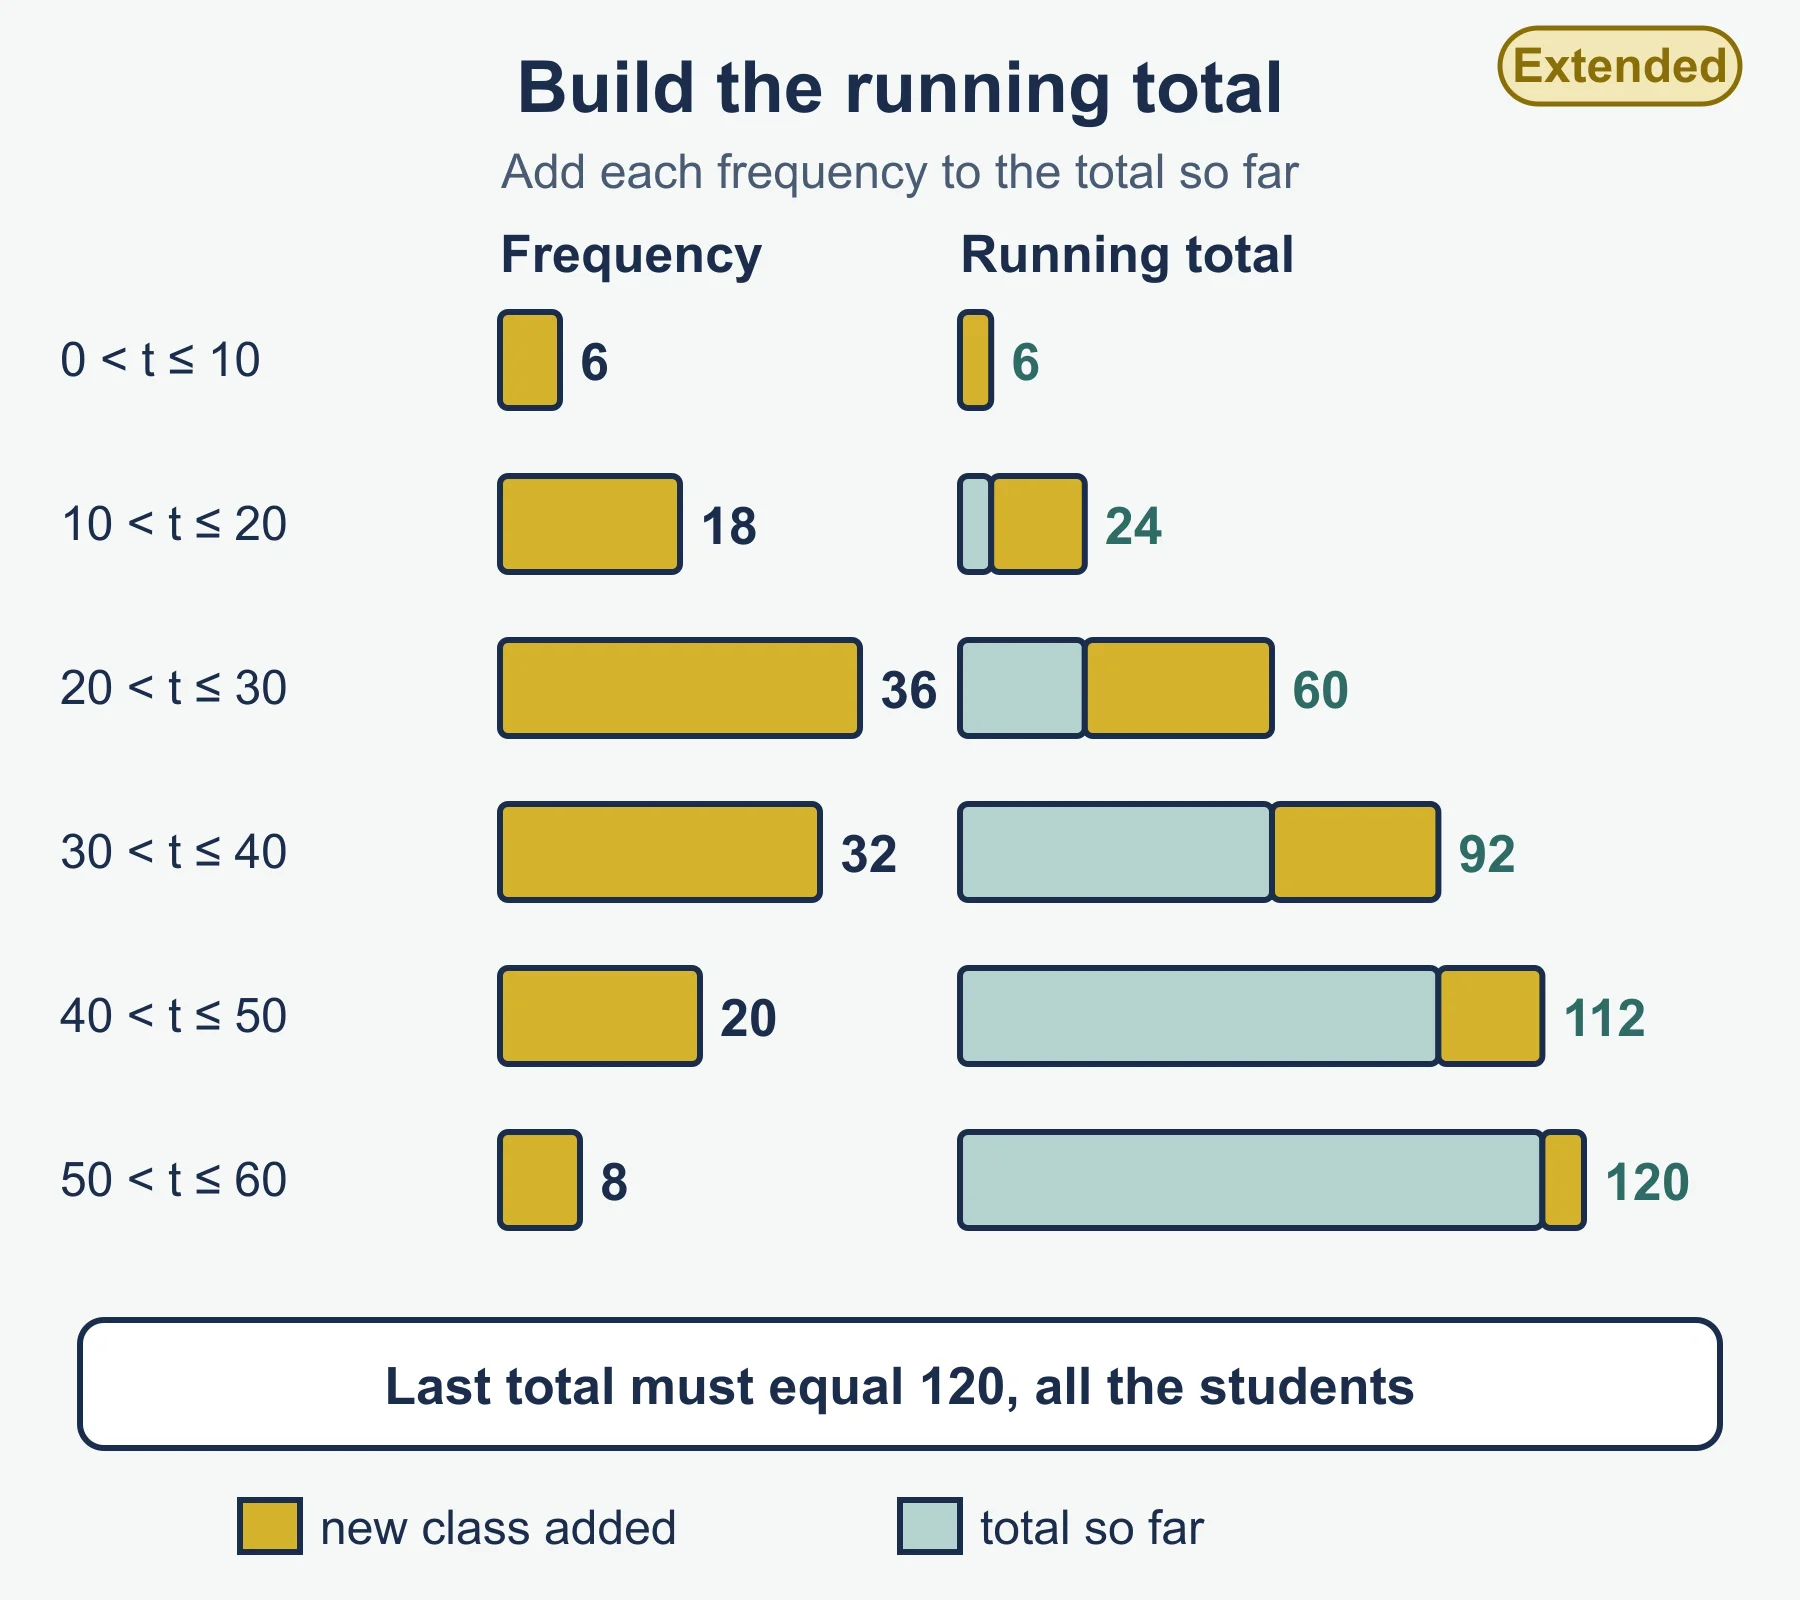
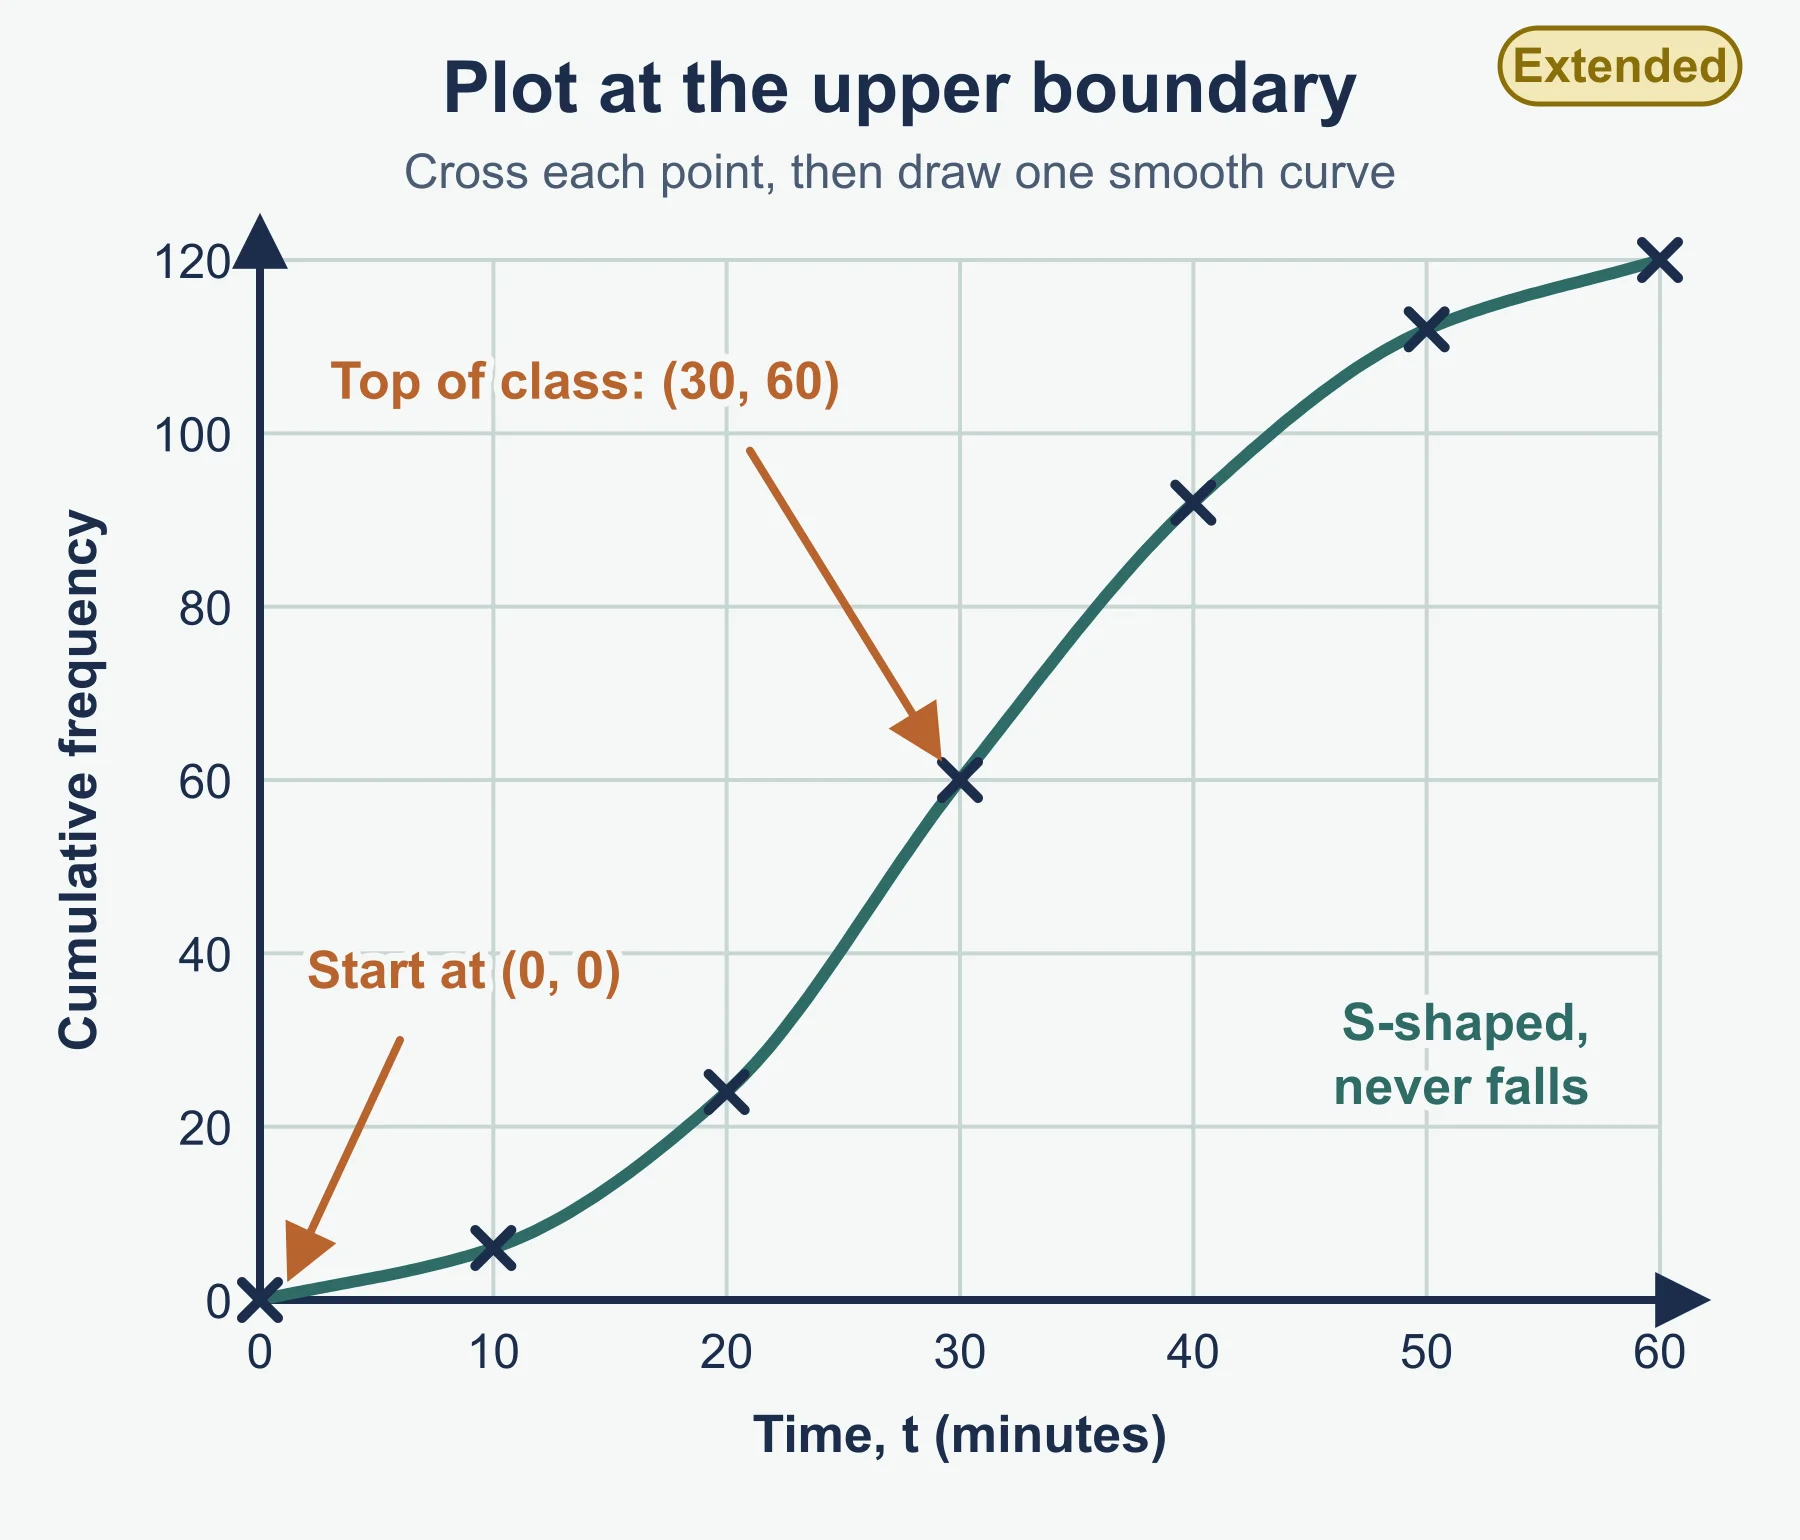
Add the frequencies as you go, then plot each running total at the upper class boundary. Join with a smooth curve or straight lines, starting from the lower boundary of the first class at a cumulative frequency of 0.
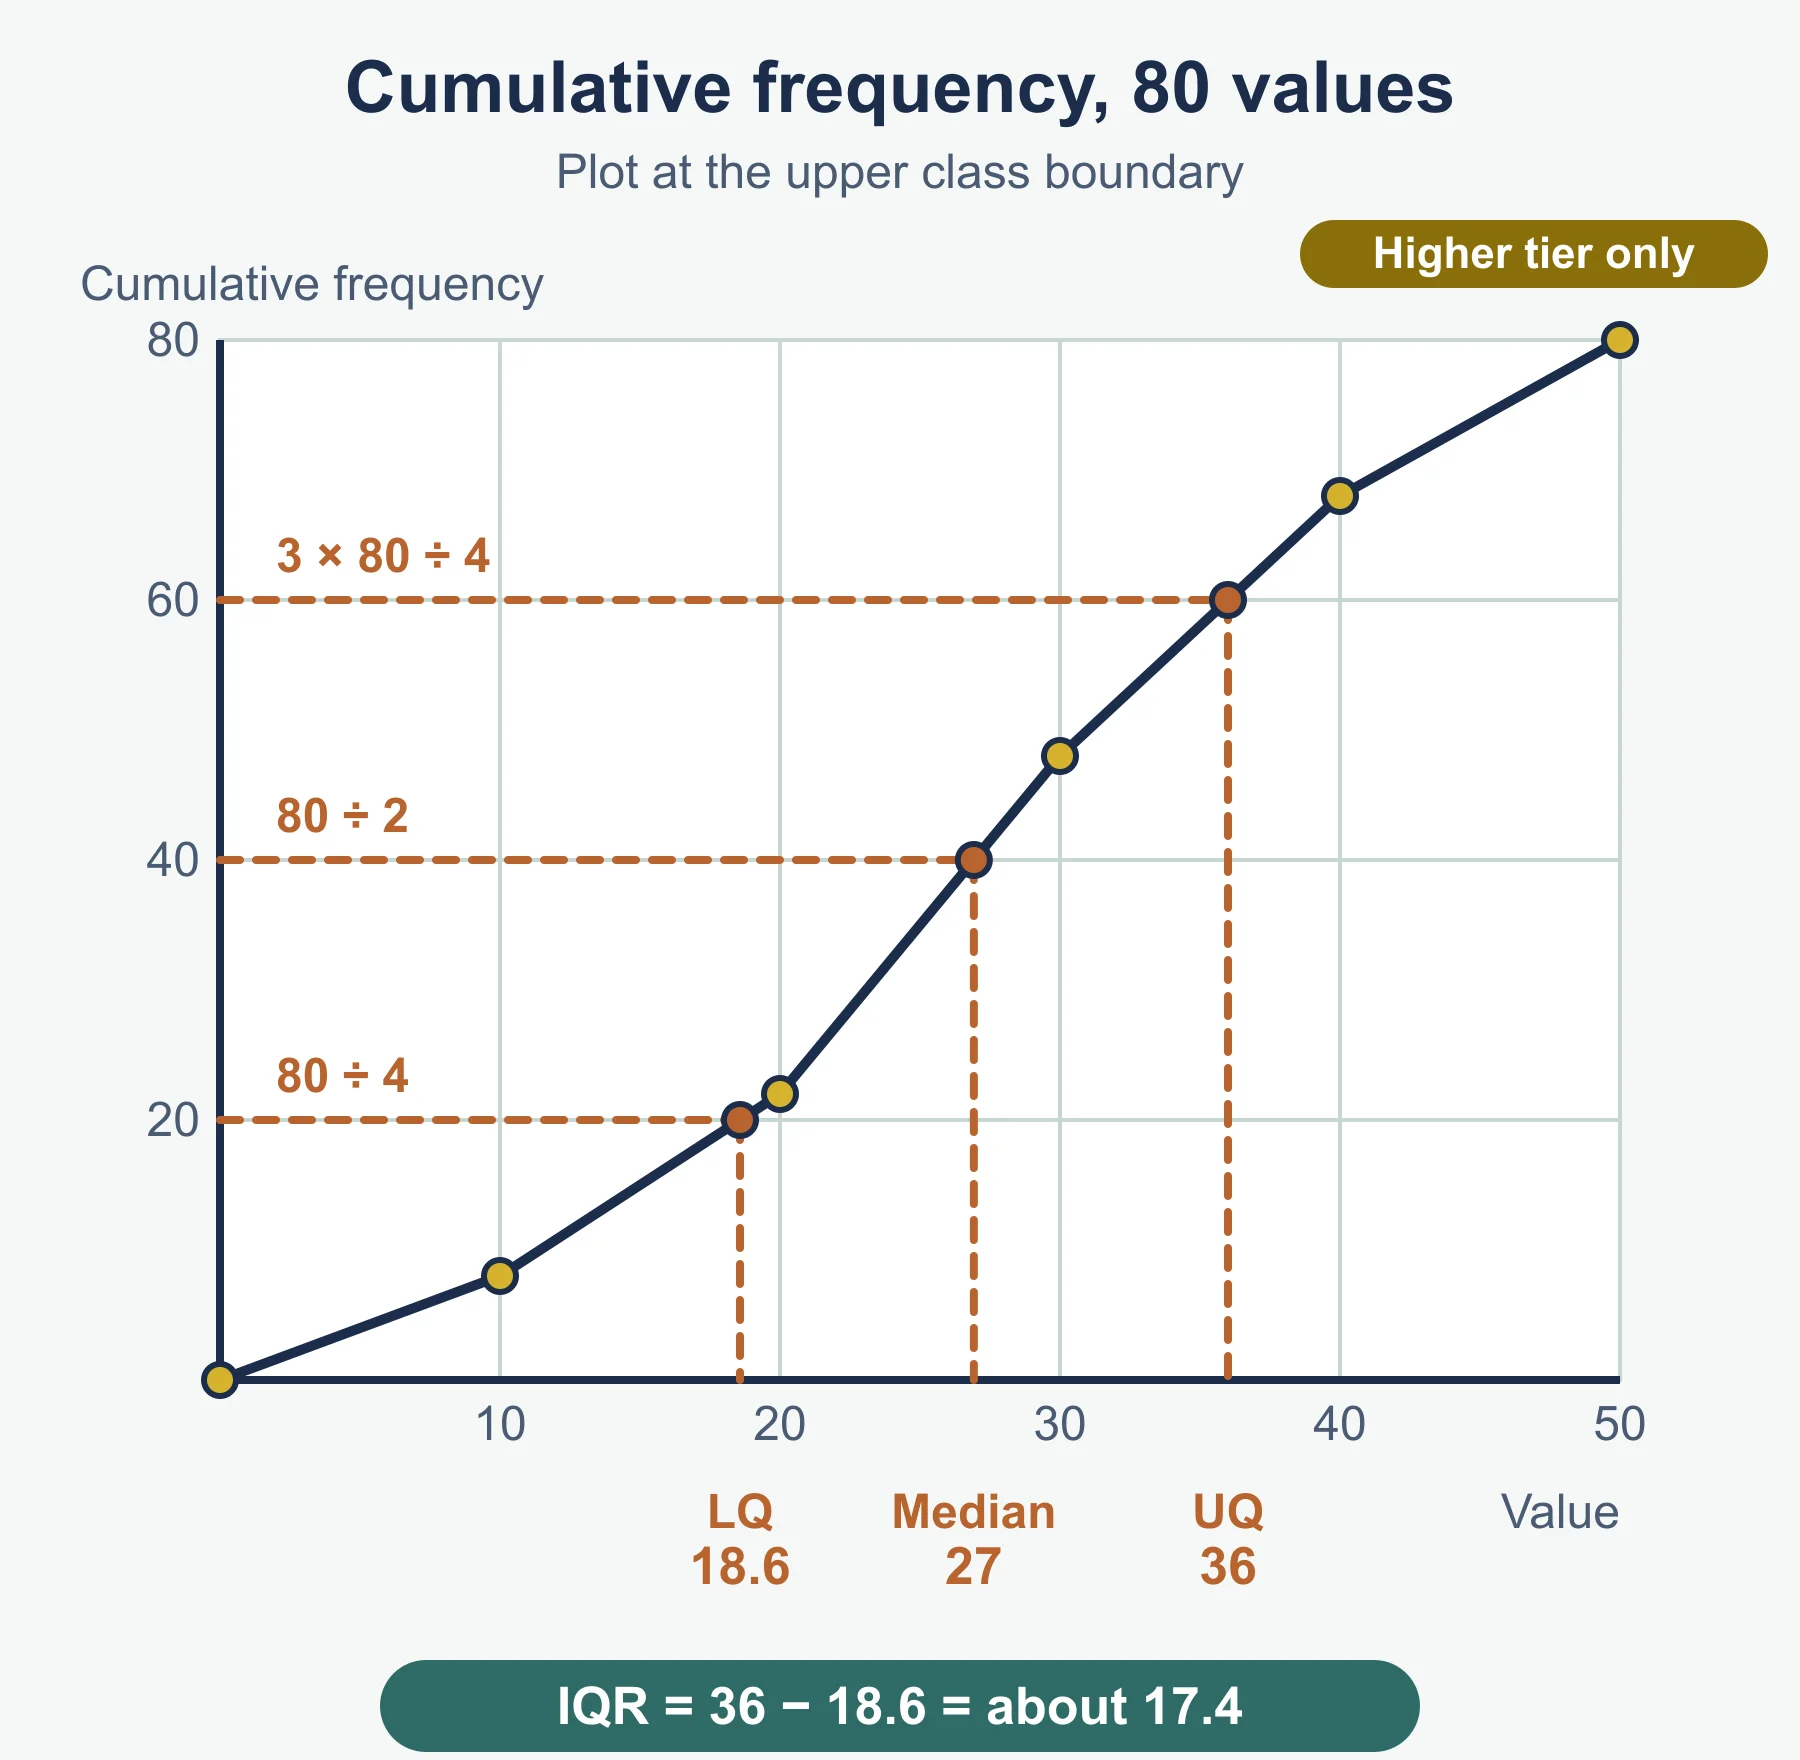
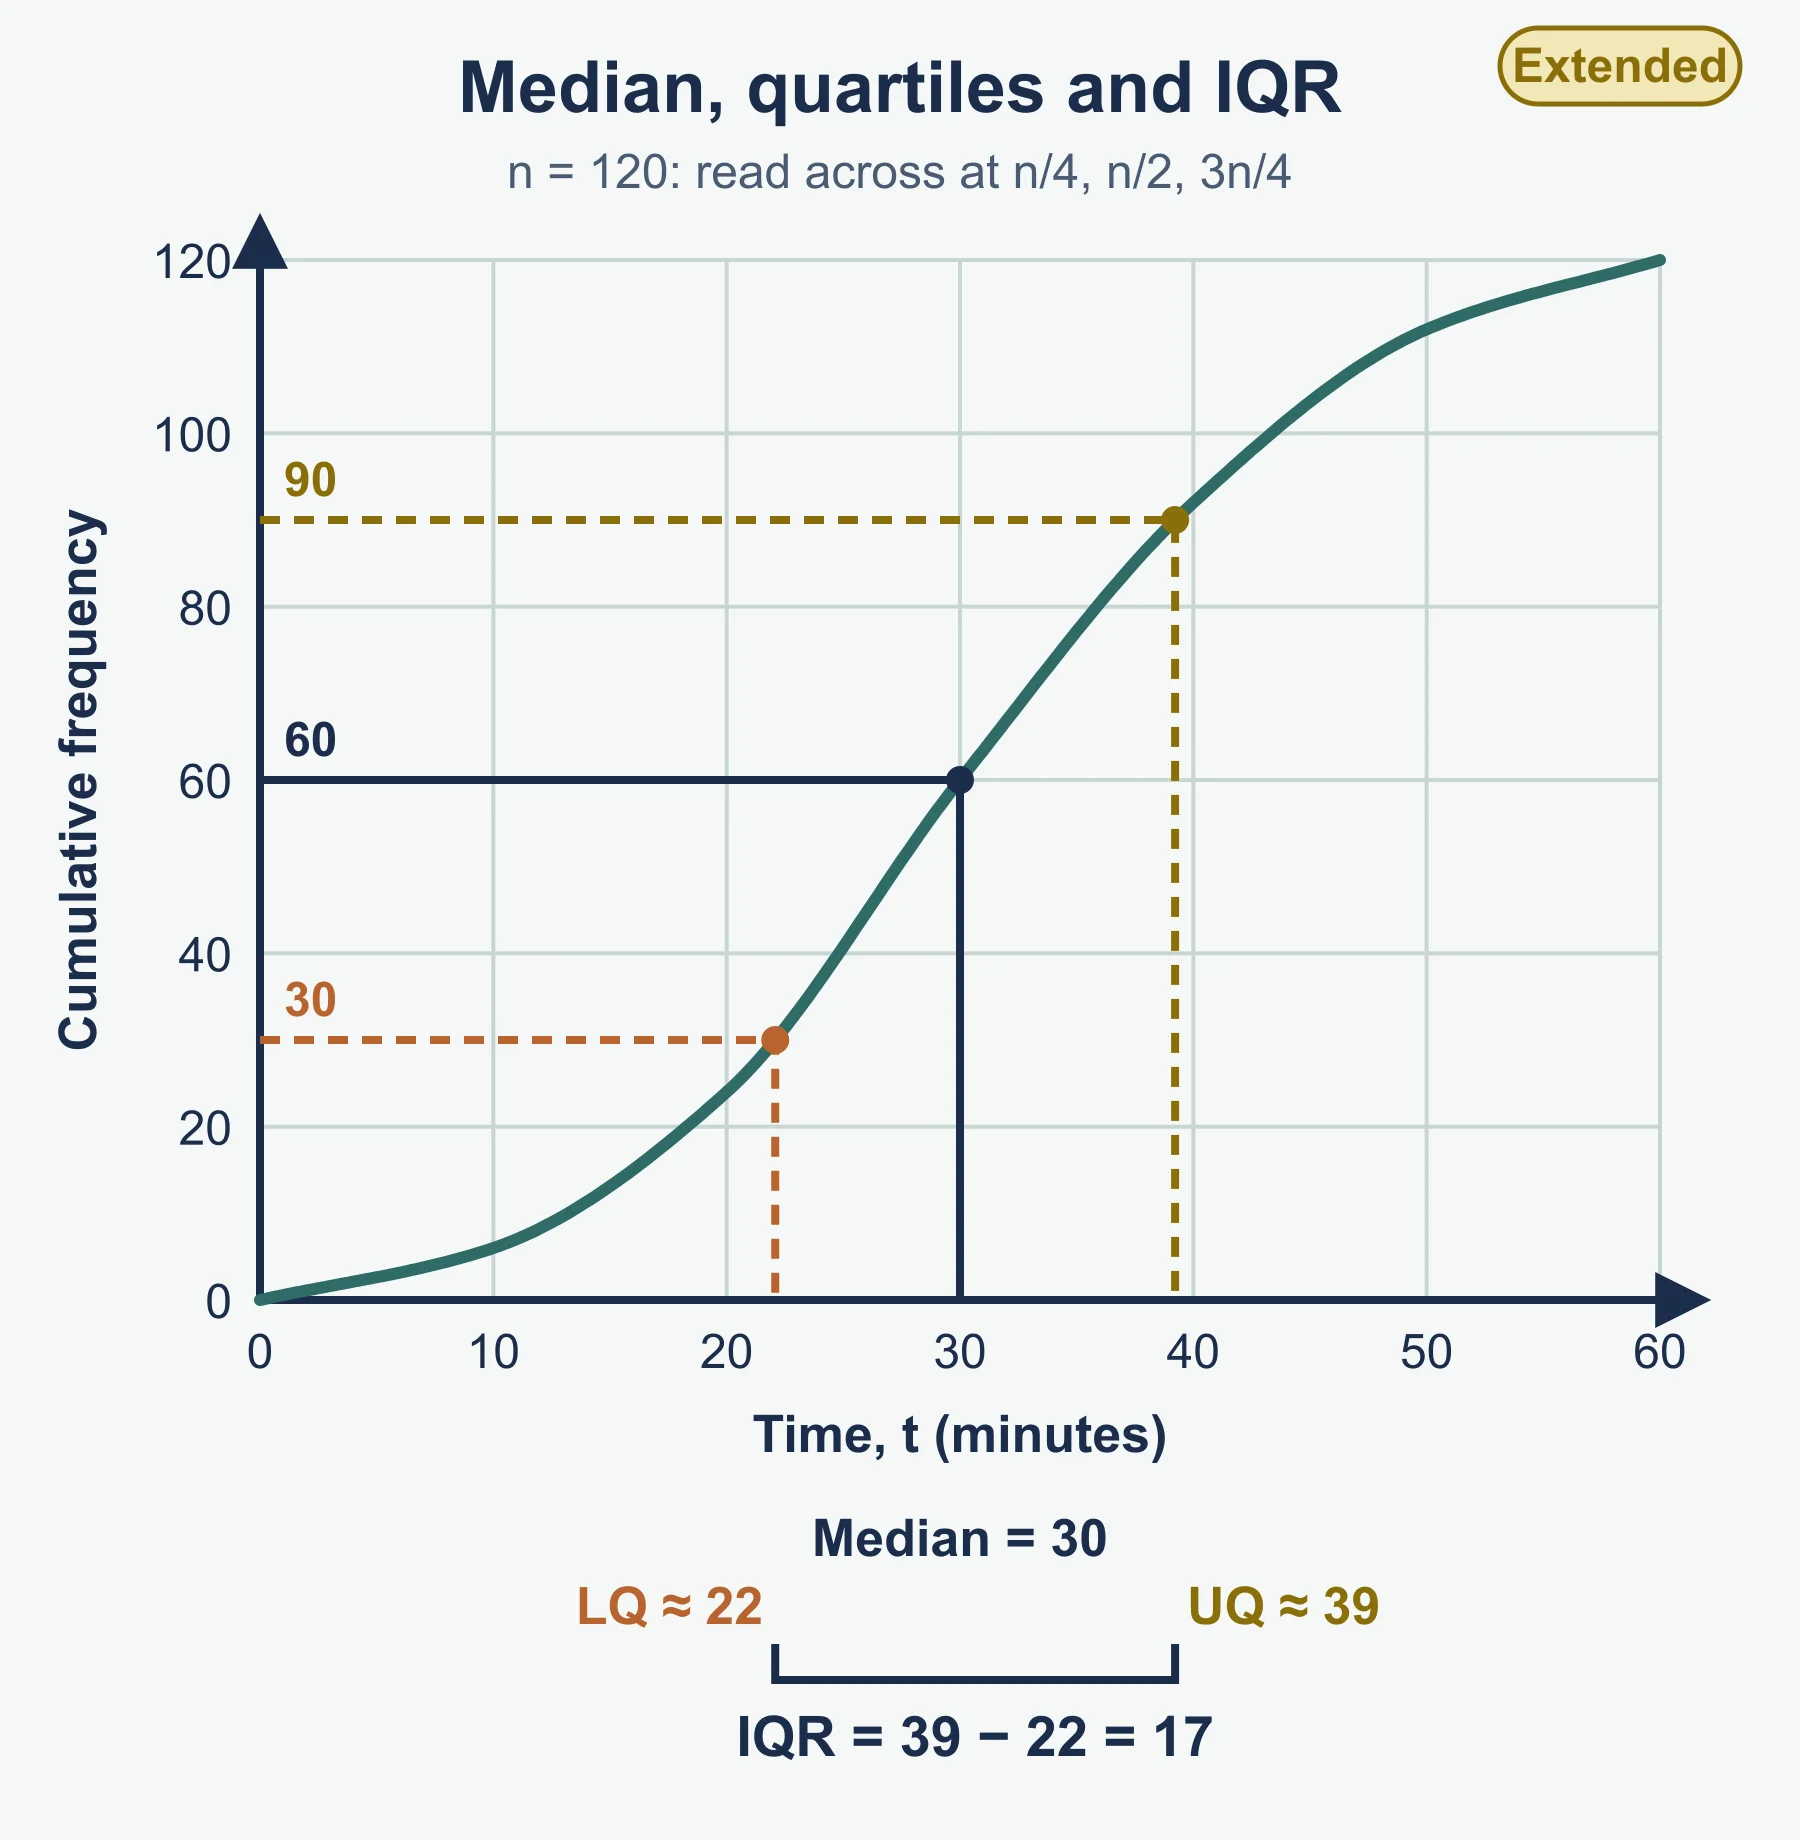
For 80 values in classes 0–10, 10–20, 20–30, 30–40, 40–50 with frequencies 8, 14, 26, 20, 12, plot (10, 8), (20, 22), (30, 48), (40, 68), (50, 80), starting at (0, 0).
- Median: read across at 80 ÷ 2 = 40. It is about 27.
- Lower quartile: read across at 80 ÷ 4 = 20. It is about 18.6.
- Upper quartile: read across at 3 × 80 ÷ 4 = 60. It is about 36.
- Interquartile range = upper quartile − lower quartile, about 17.4.
The values here come from straight lines between the points. A curve gives slightly different readings, which is why exam answers from graphs accept a range of values.
Box plots and interquartile range (S4) – Higher tier only
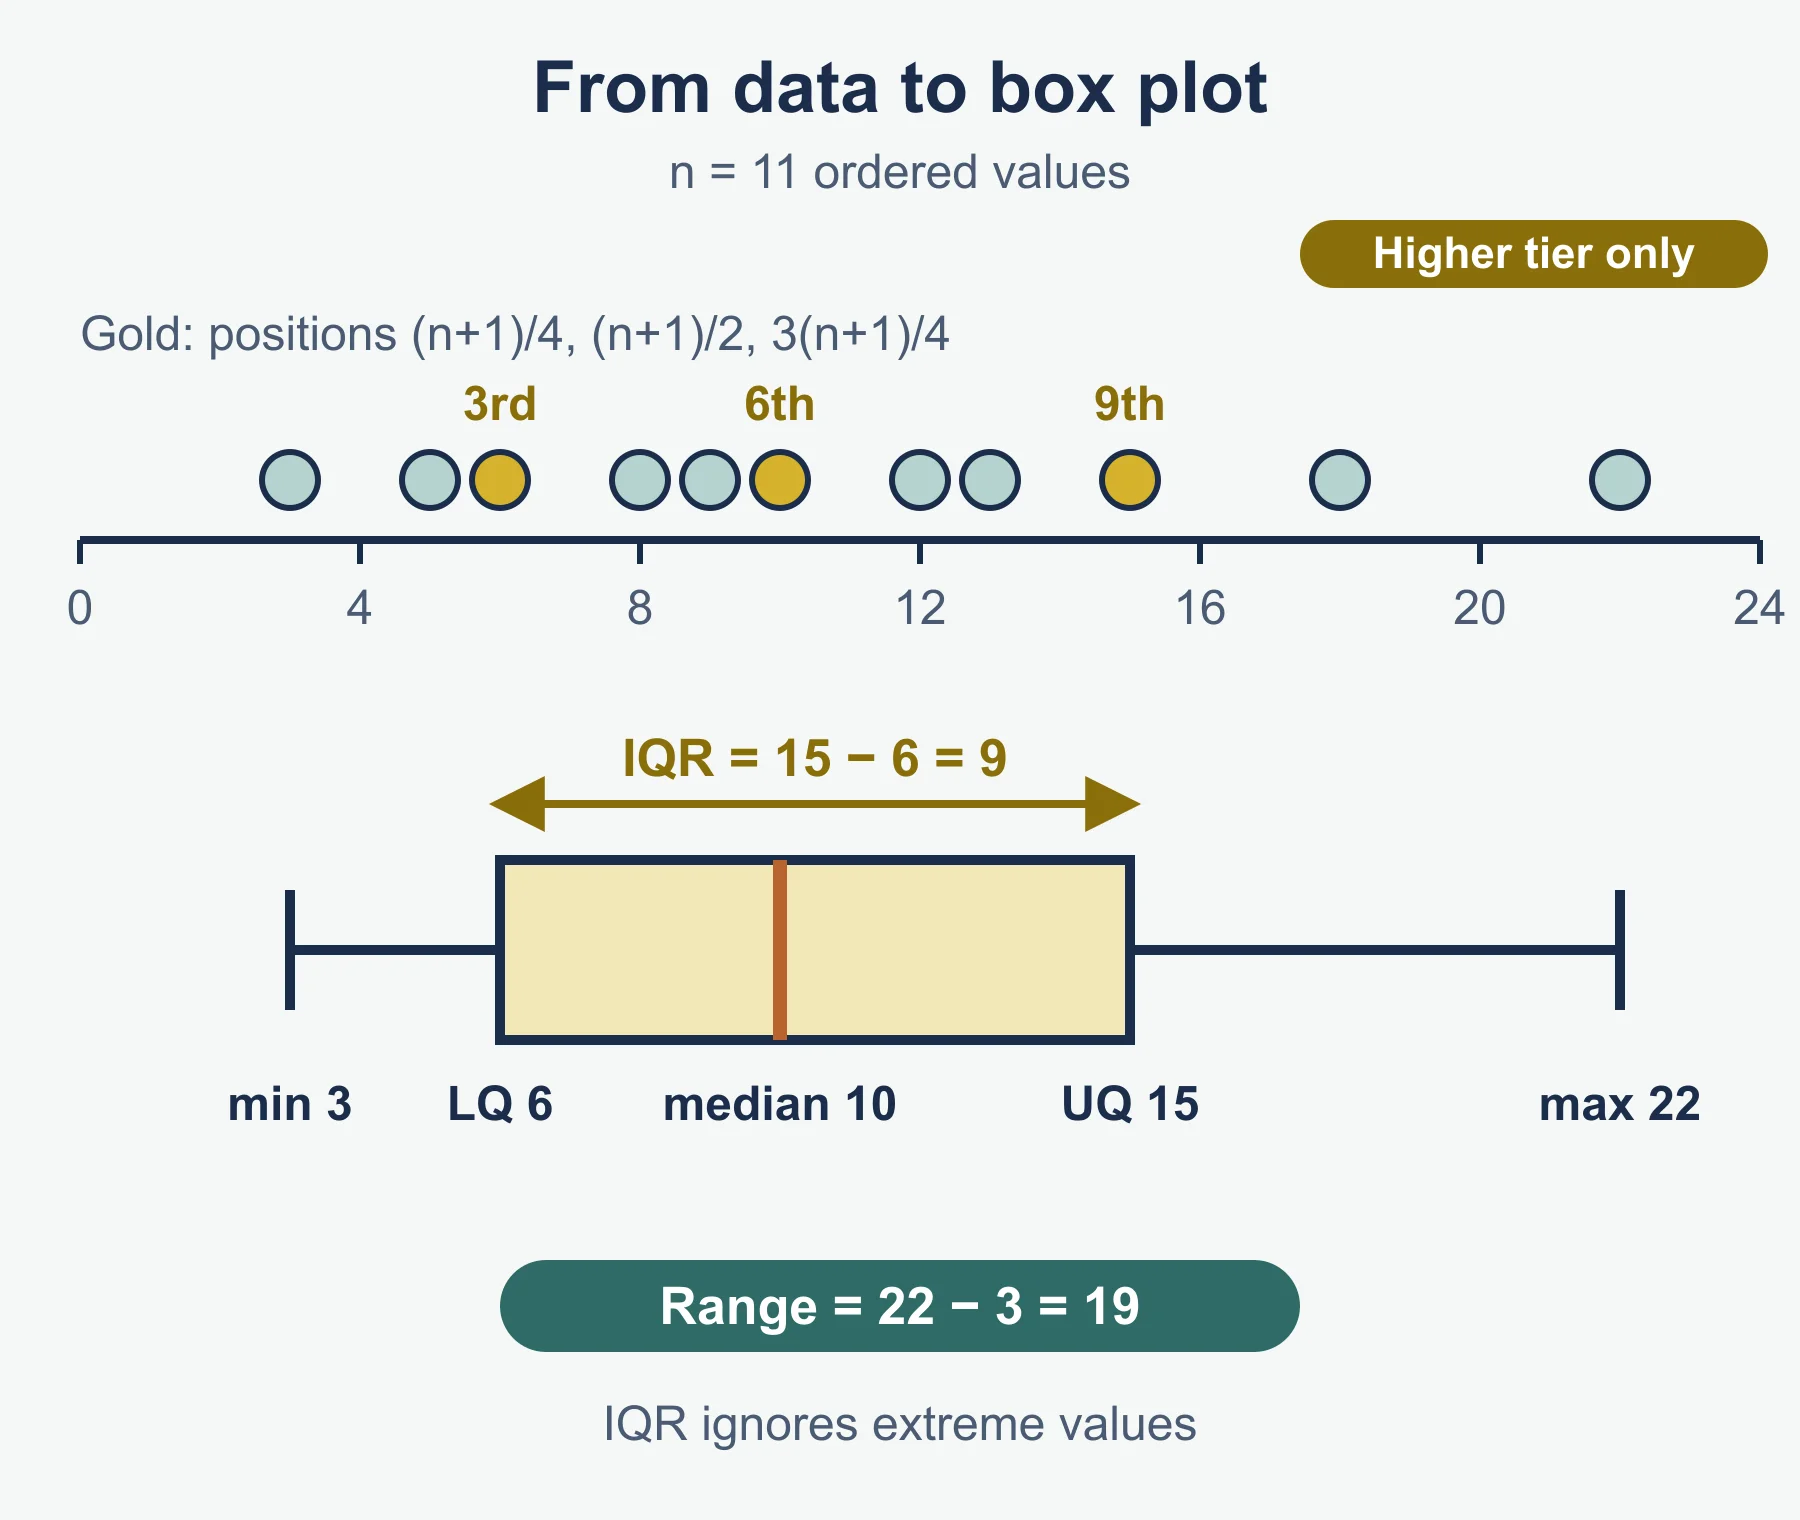
A box plot shows five values: minimum, lower quartile (LQ), median, upper quartile (UQ) and maximum. The interquartile range (IQR = UQ − LQ) is the spread of the middle half of the data. It is not affected by extreme values.
Worked example 6. Data in order: 3, 5, 6, 8, 9, 10, 12, 13, 15, 18, 22 (n = 11).
Median: (11 + 1)/2 = 6th value = 10
LQ: (11 + 1)/4 = 3rd value = 6
UQ: 3 × (11 + 1)/4 = 9th value = 15
IQR = 15 − 6 = 9;  range = 22 − 3 = 19
Draw the box from 6 to 15 with a line at 10, and whiskers out to 3 and 22, above a scale.
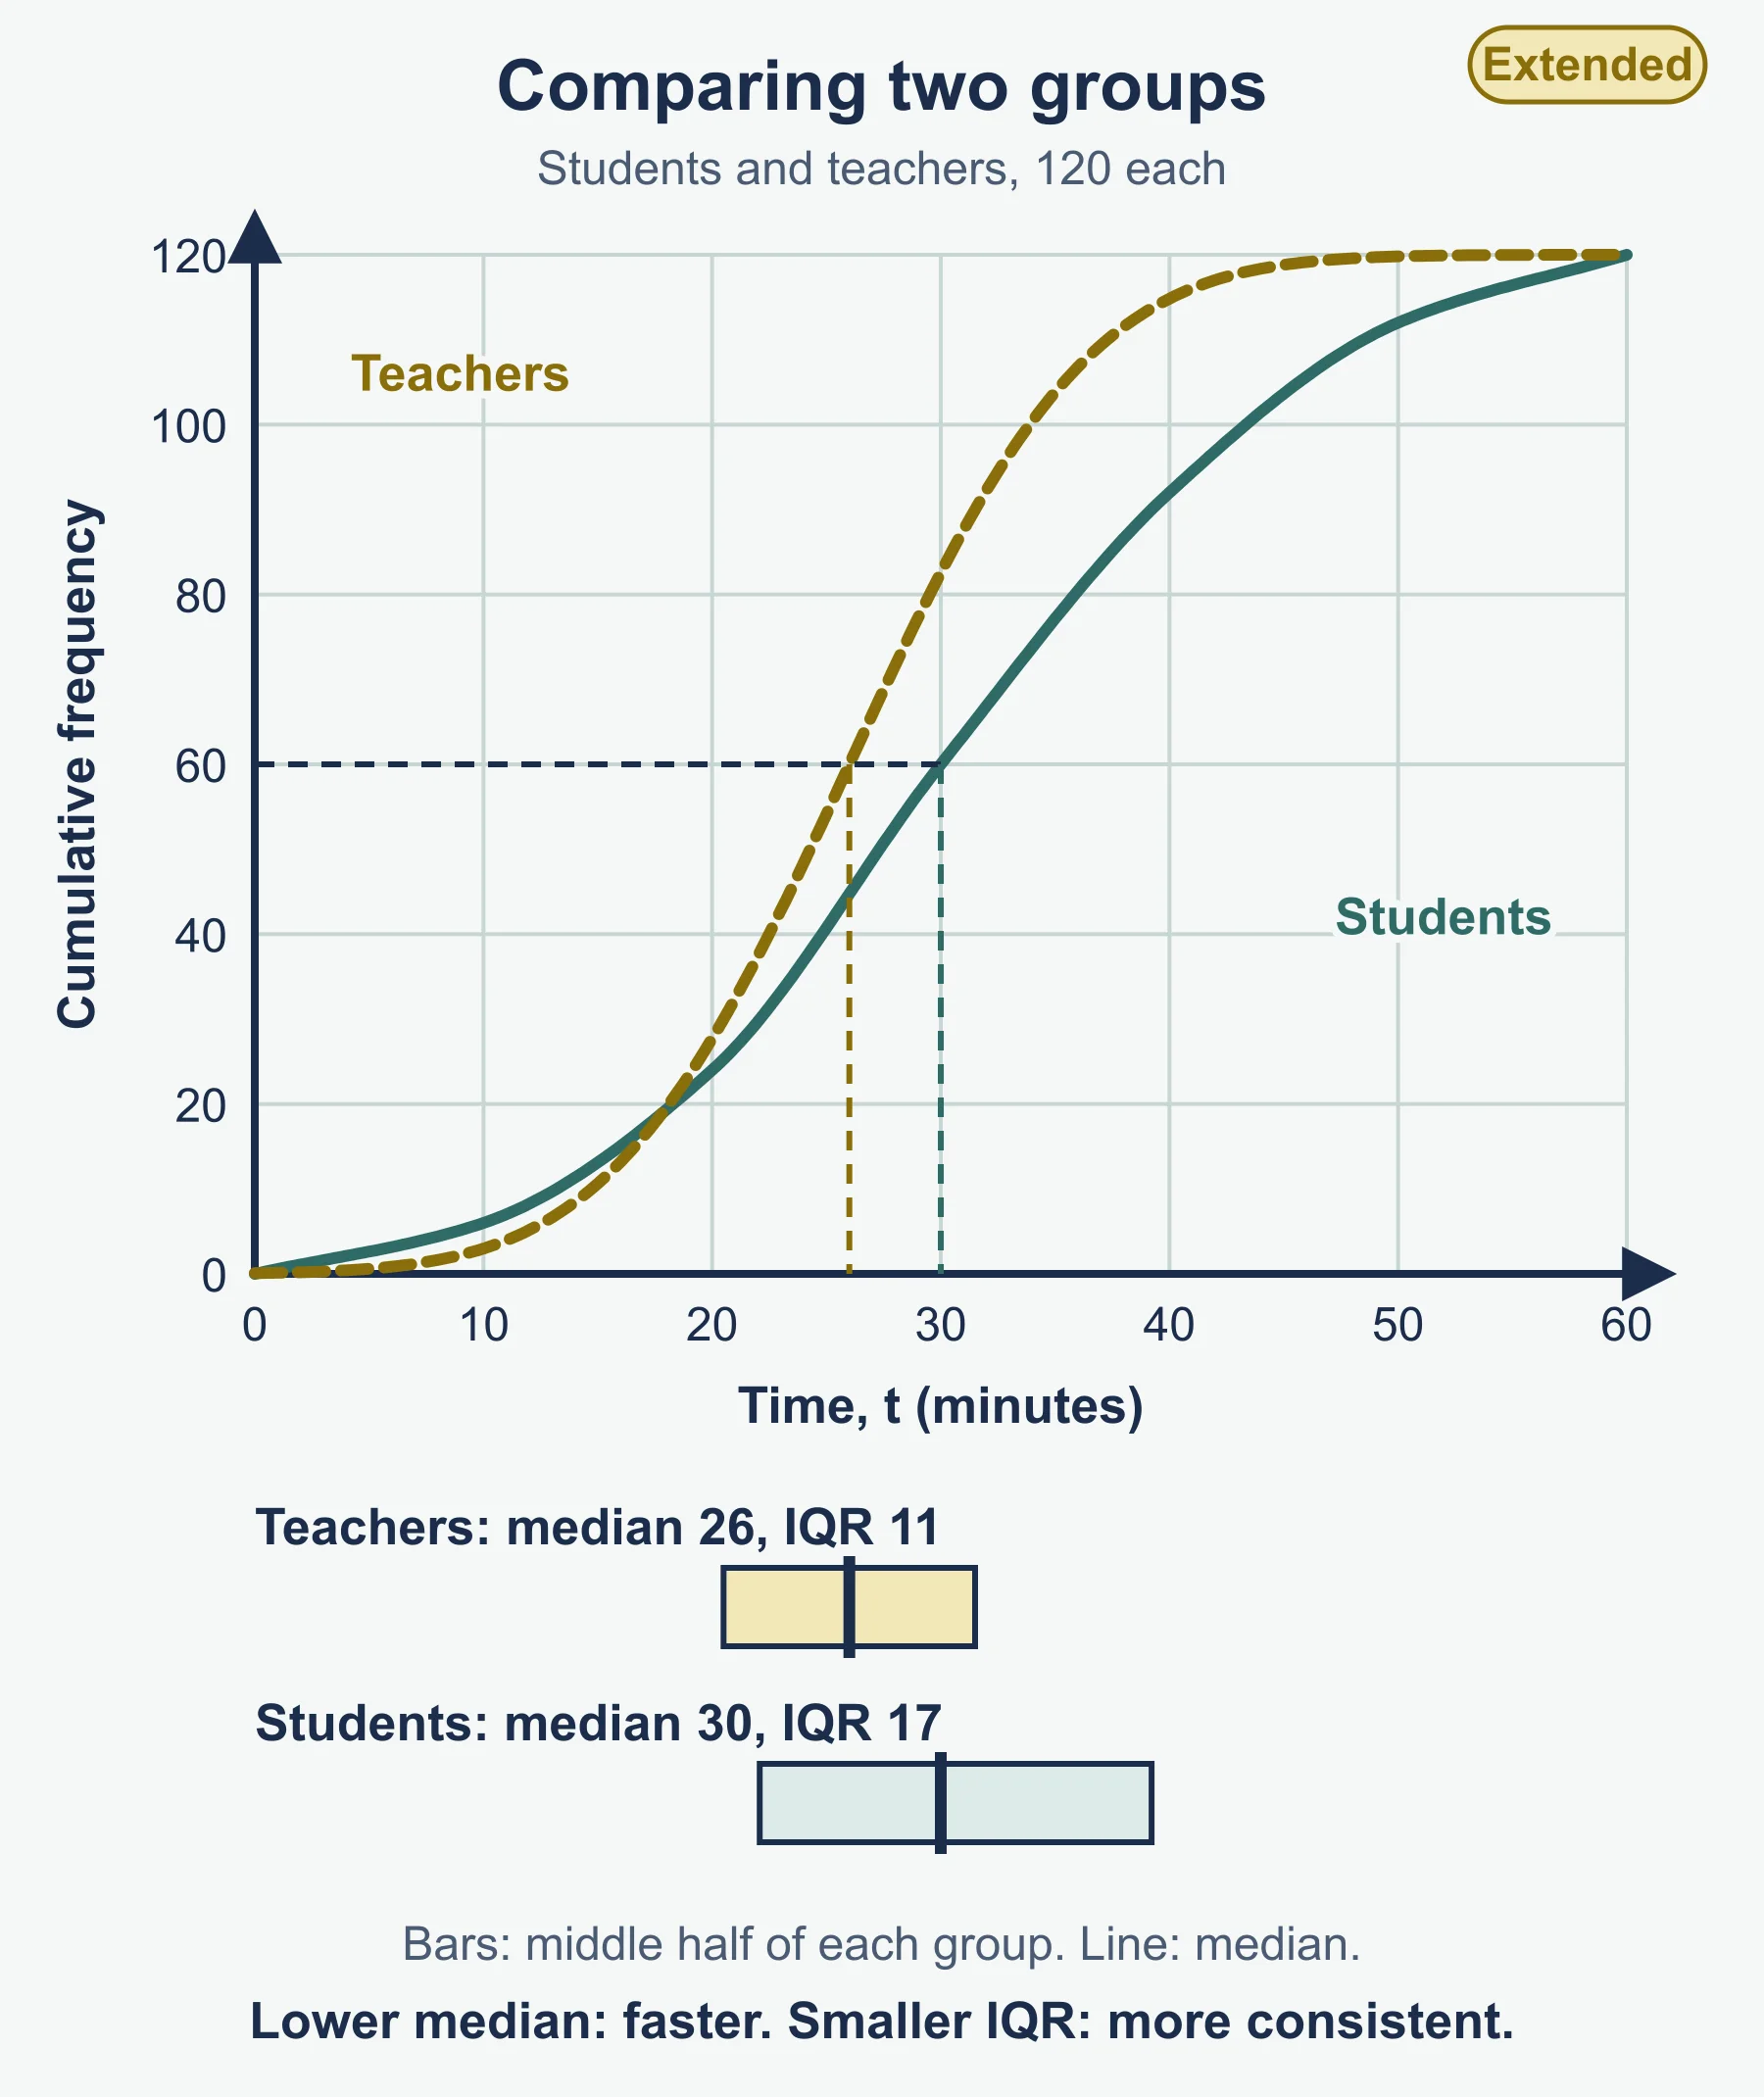
To compare two box plots, compare the medians (average) and the IQRs (consistency), in context.
Scatter graphs (S6)
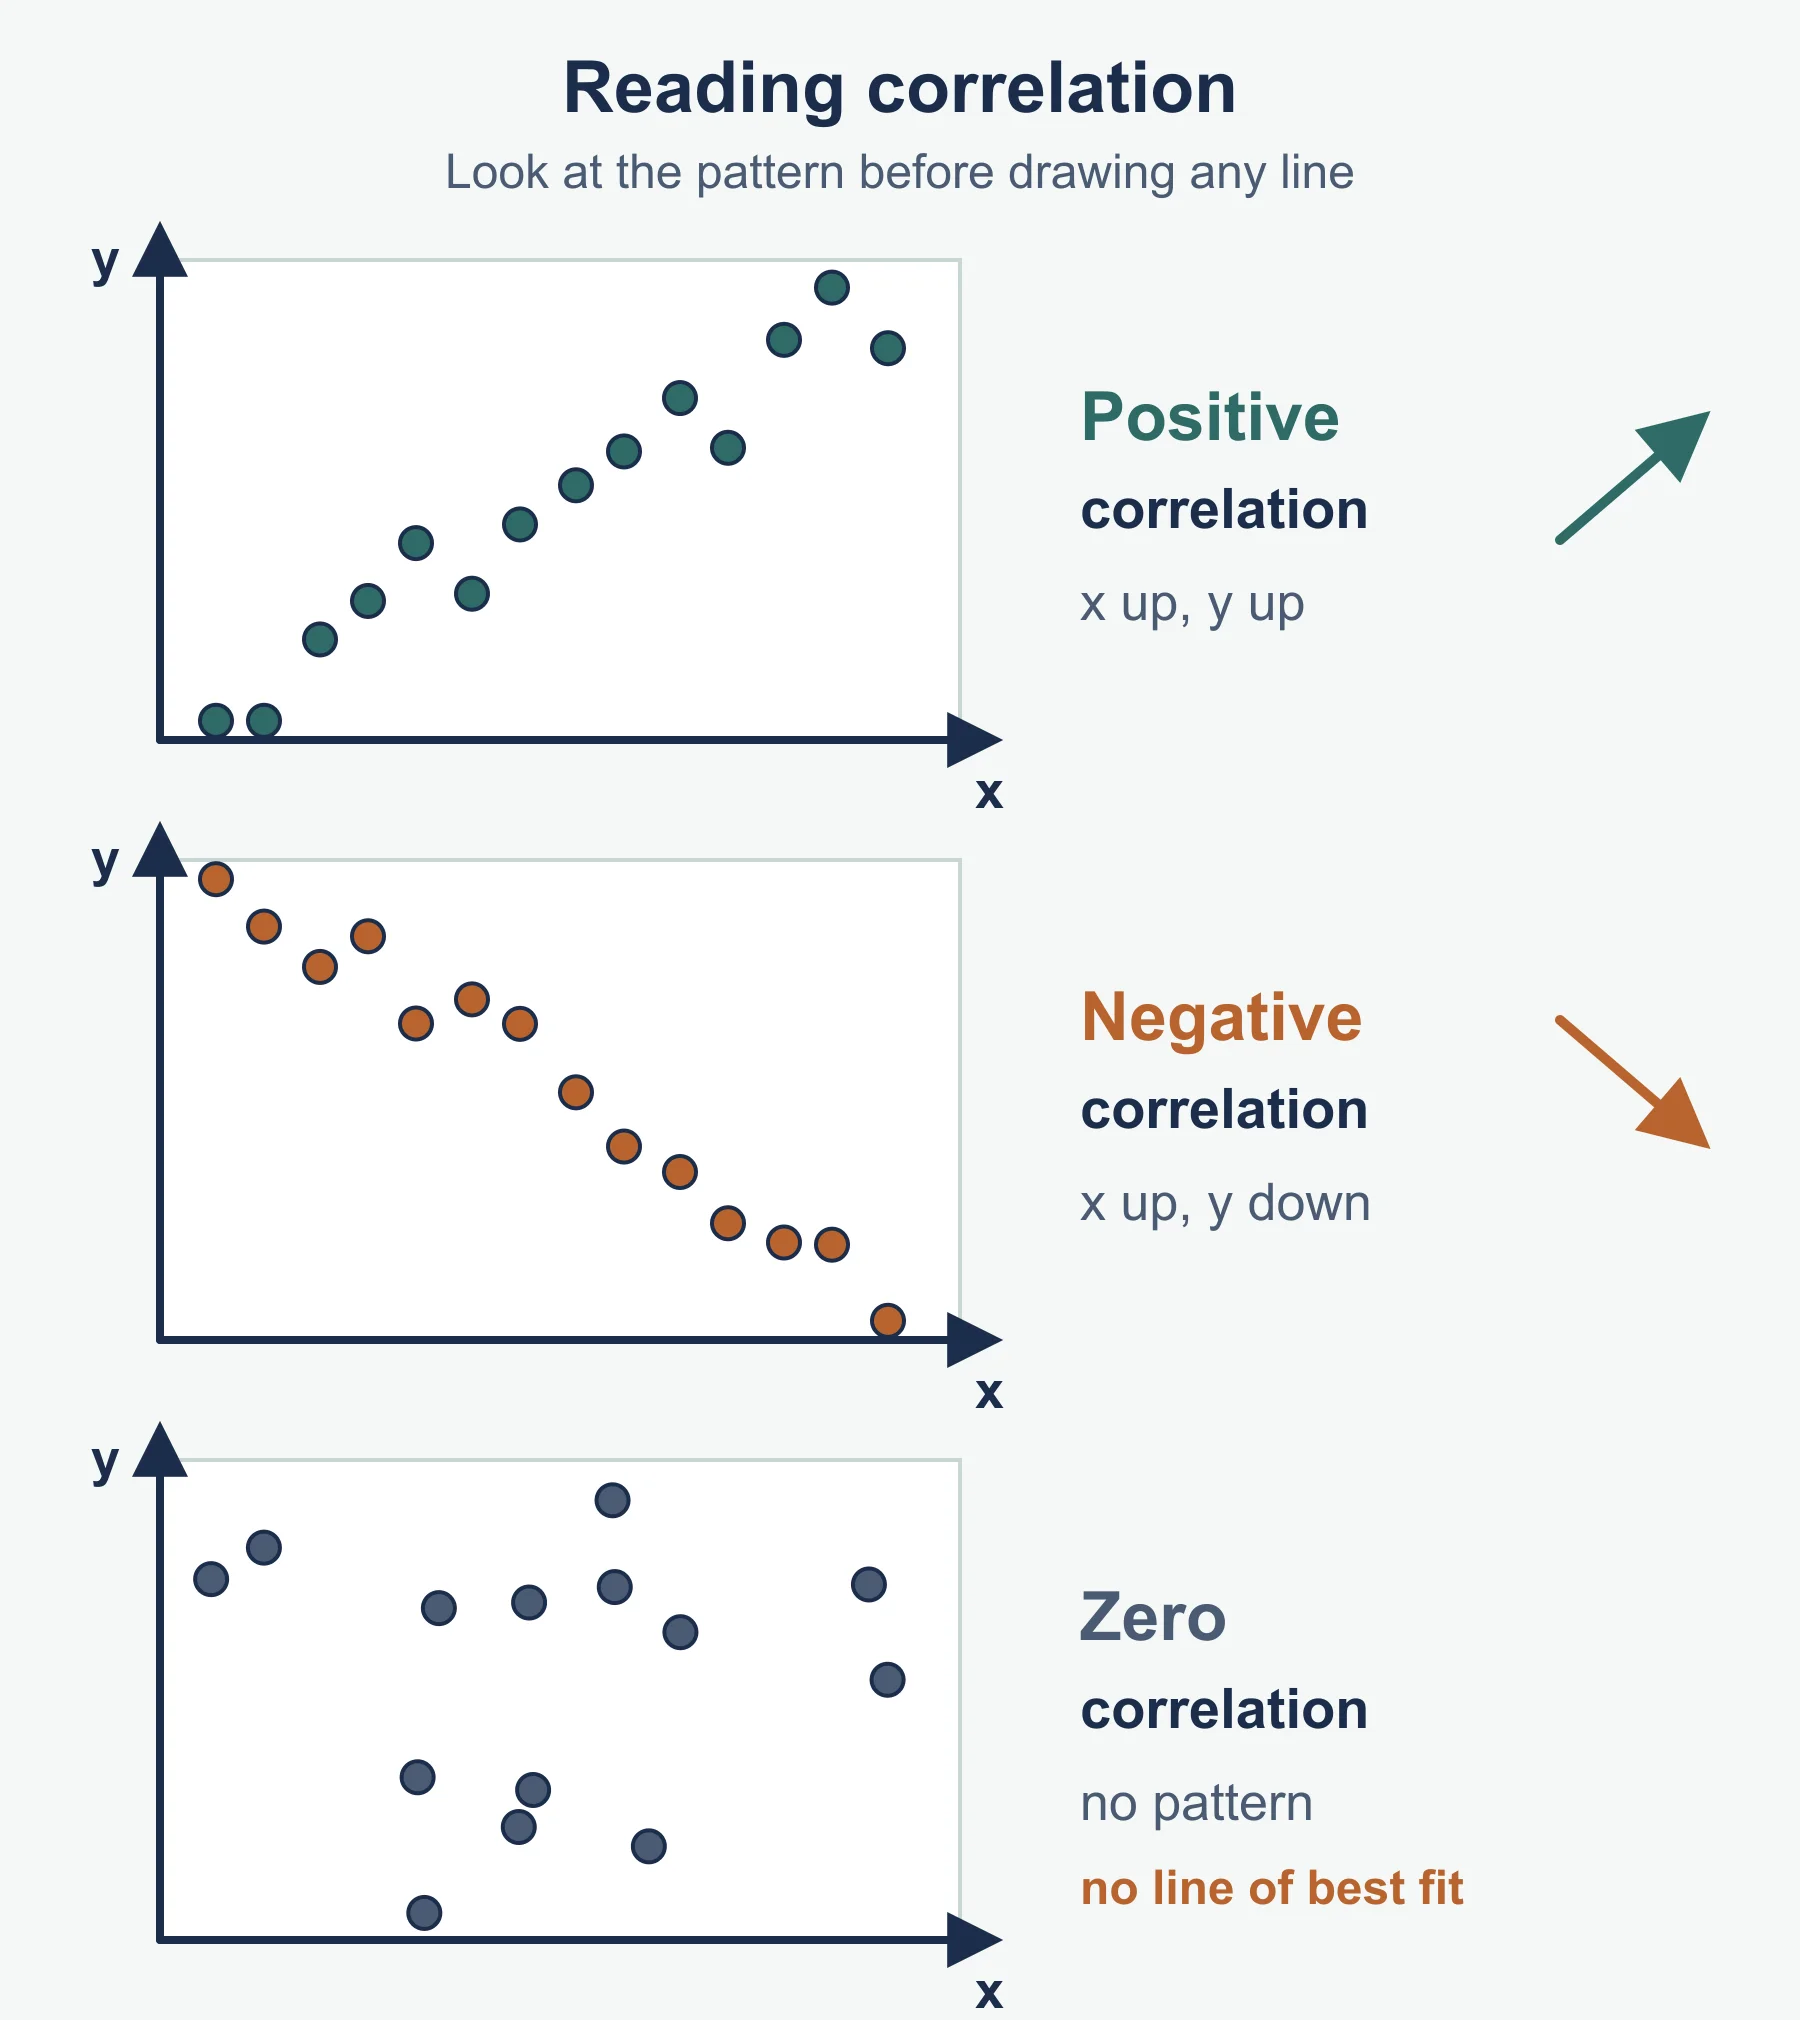
A scatter graph plots pairs of values (bivariate data) to see if they are related.
- Positive correlation: as one goes up, the other tends to go up.
- Negative correlation: as one goes up, the other tends to go down.
- No correlation: no clear pattern.
- Strong correlation means the points lie close to a straight line; weak means they are more spread out.
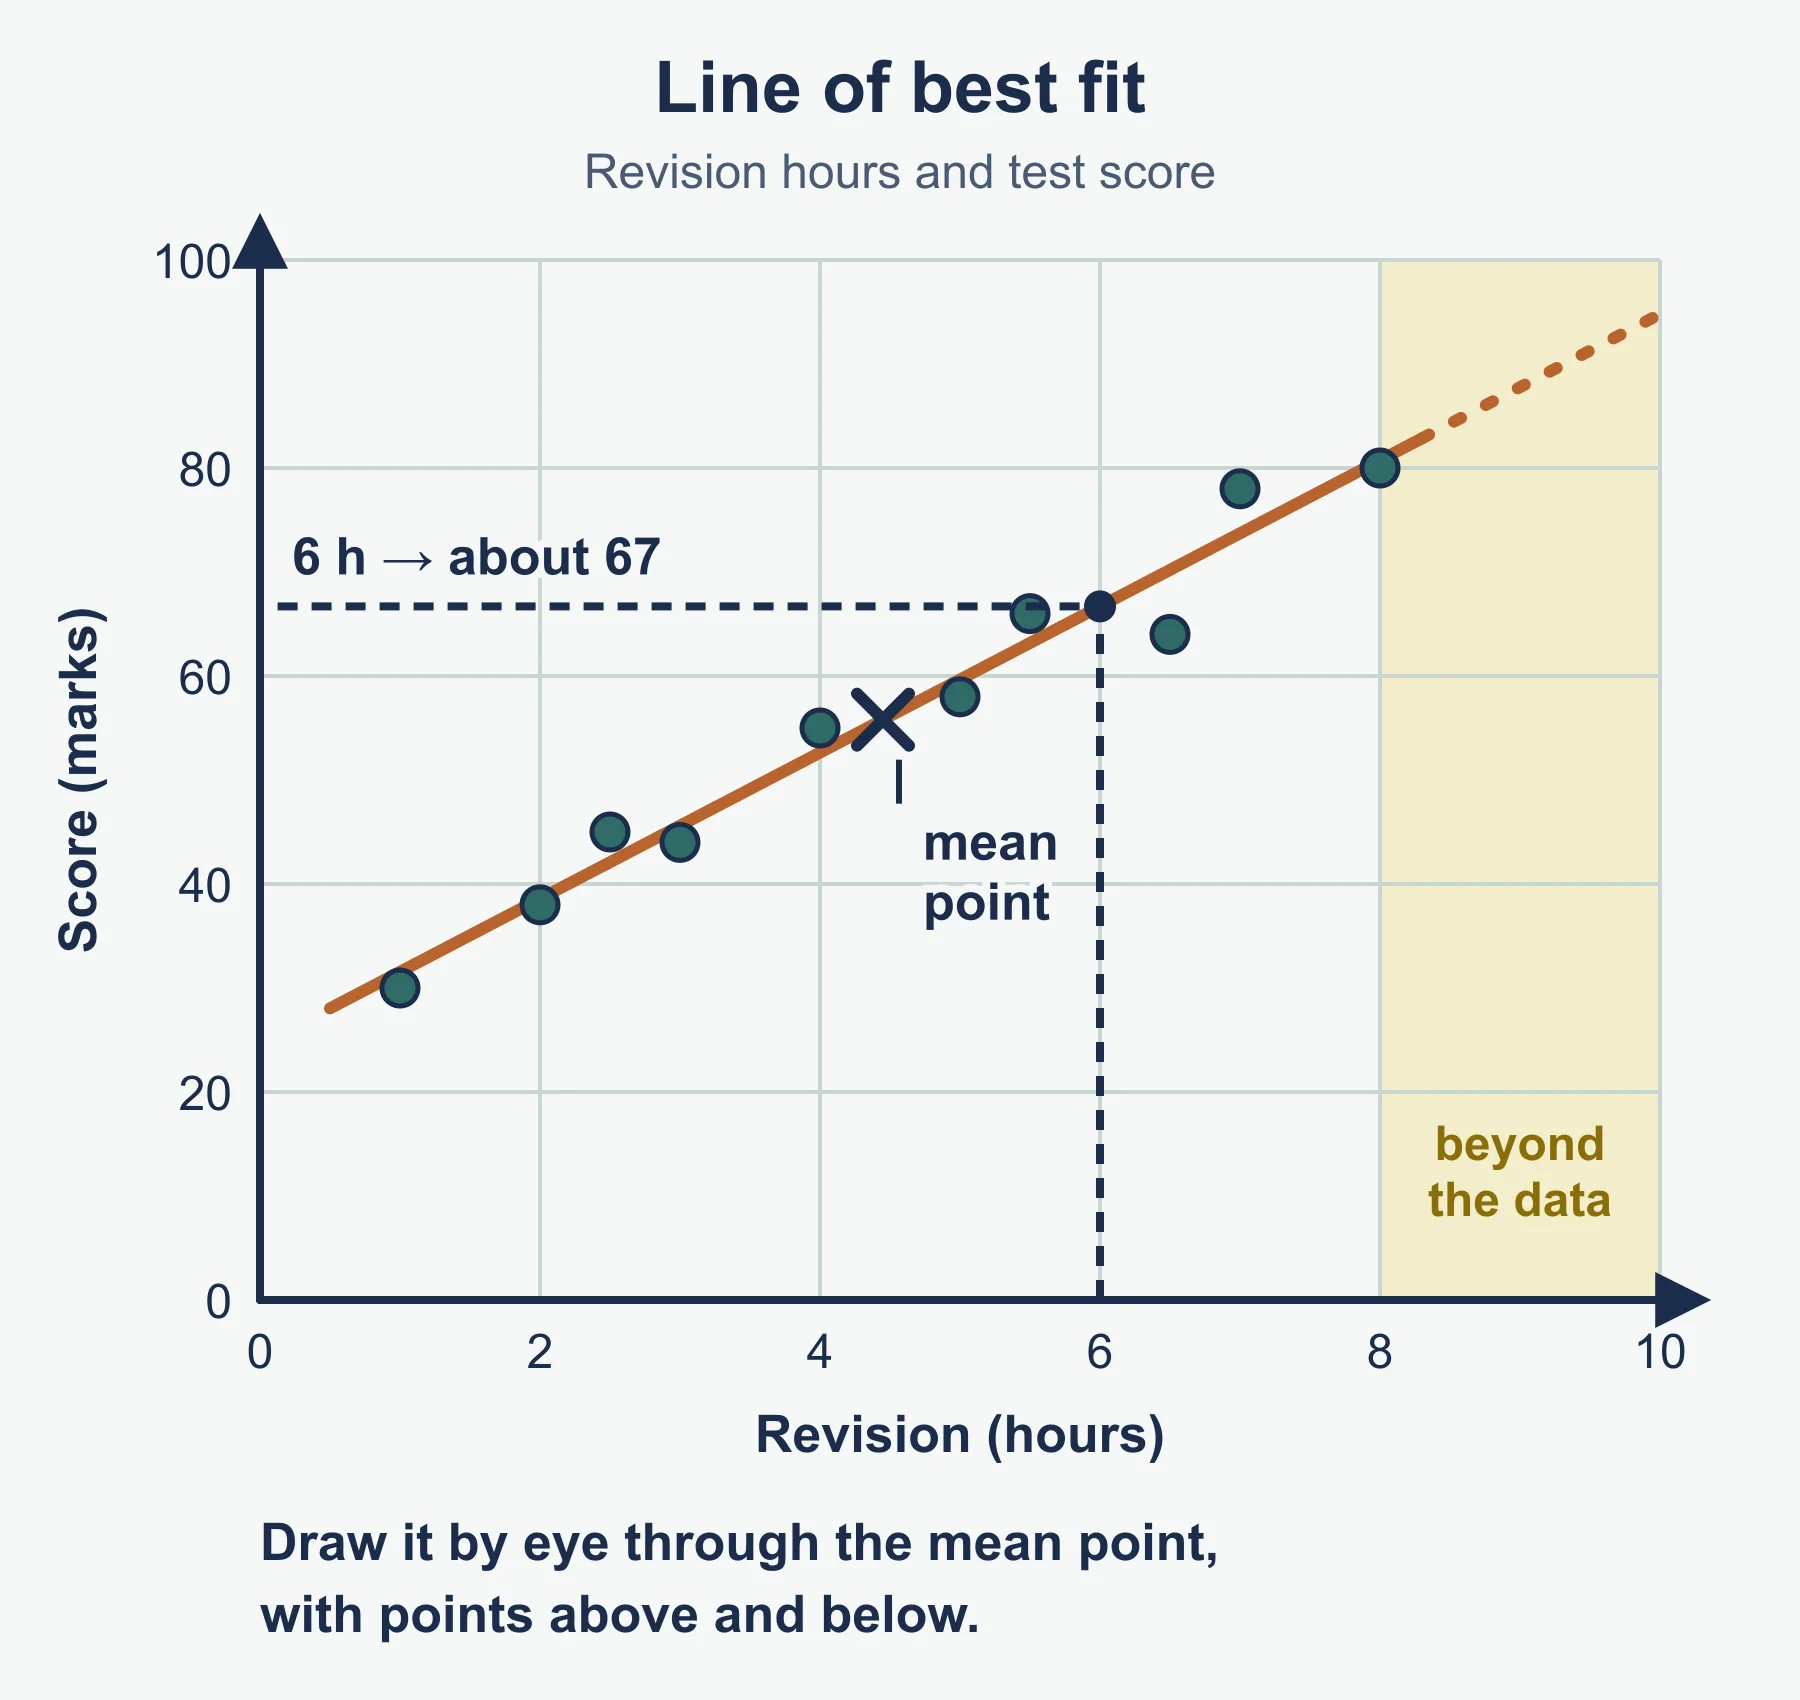
A line of best fit is a straight line drawn by eye through the middle of the points, with roughly as many points above as below. Do not force it through the origin.
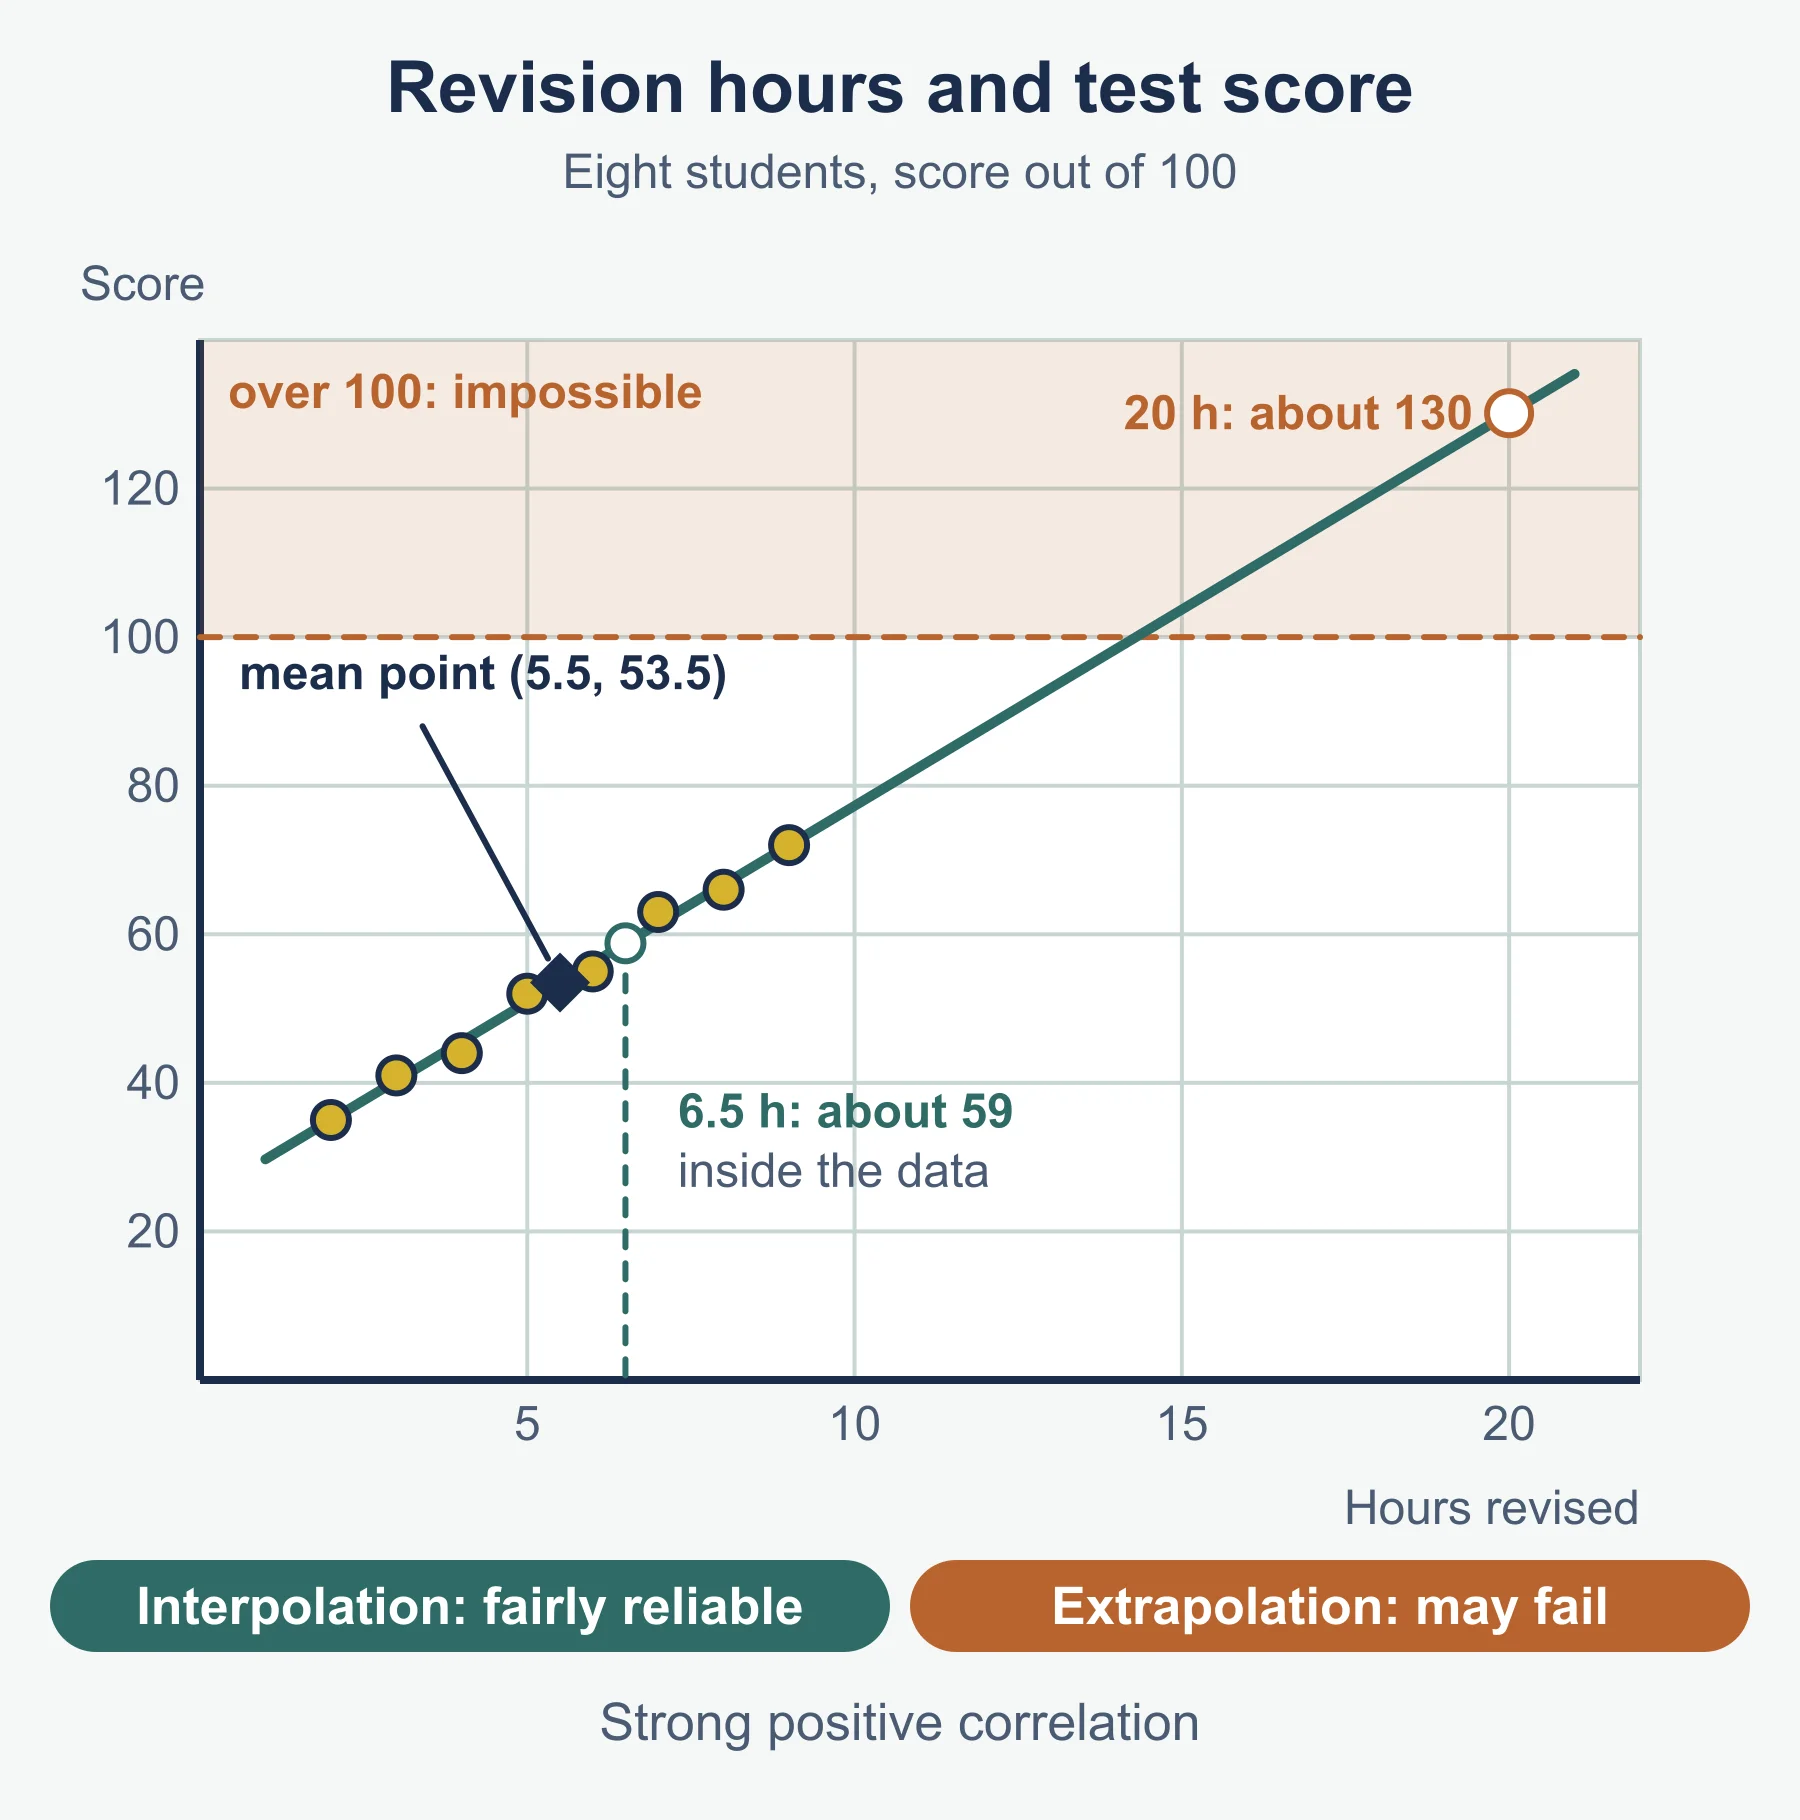
Worked example 7. Hours revised (x) and test score out of 100 (y) for 8 students: (2, 35), (3, 41), (4, 44), (5, 52), (6, 55), (7, 63), (8, 66), (9, 72). This shows strong positive correlation. The mean point is (5.5, 53.5), which is a good point for your line to pass through.
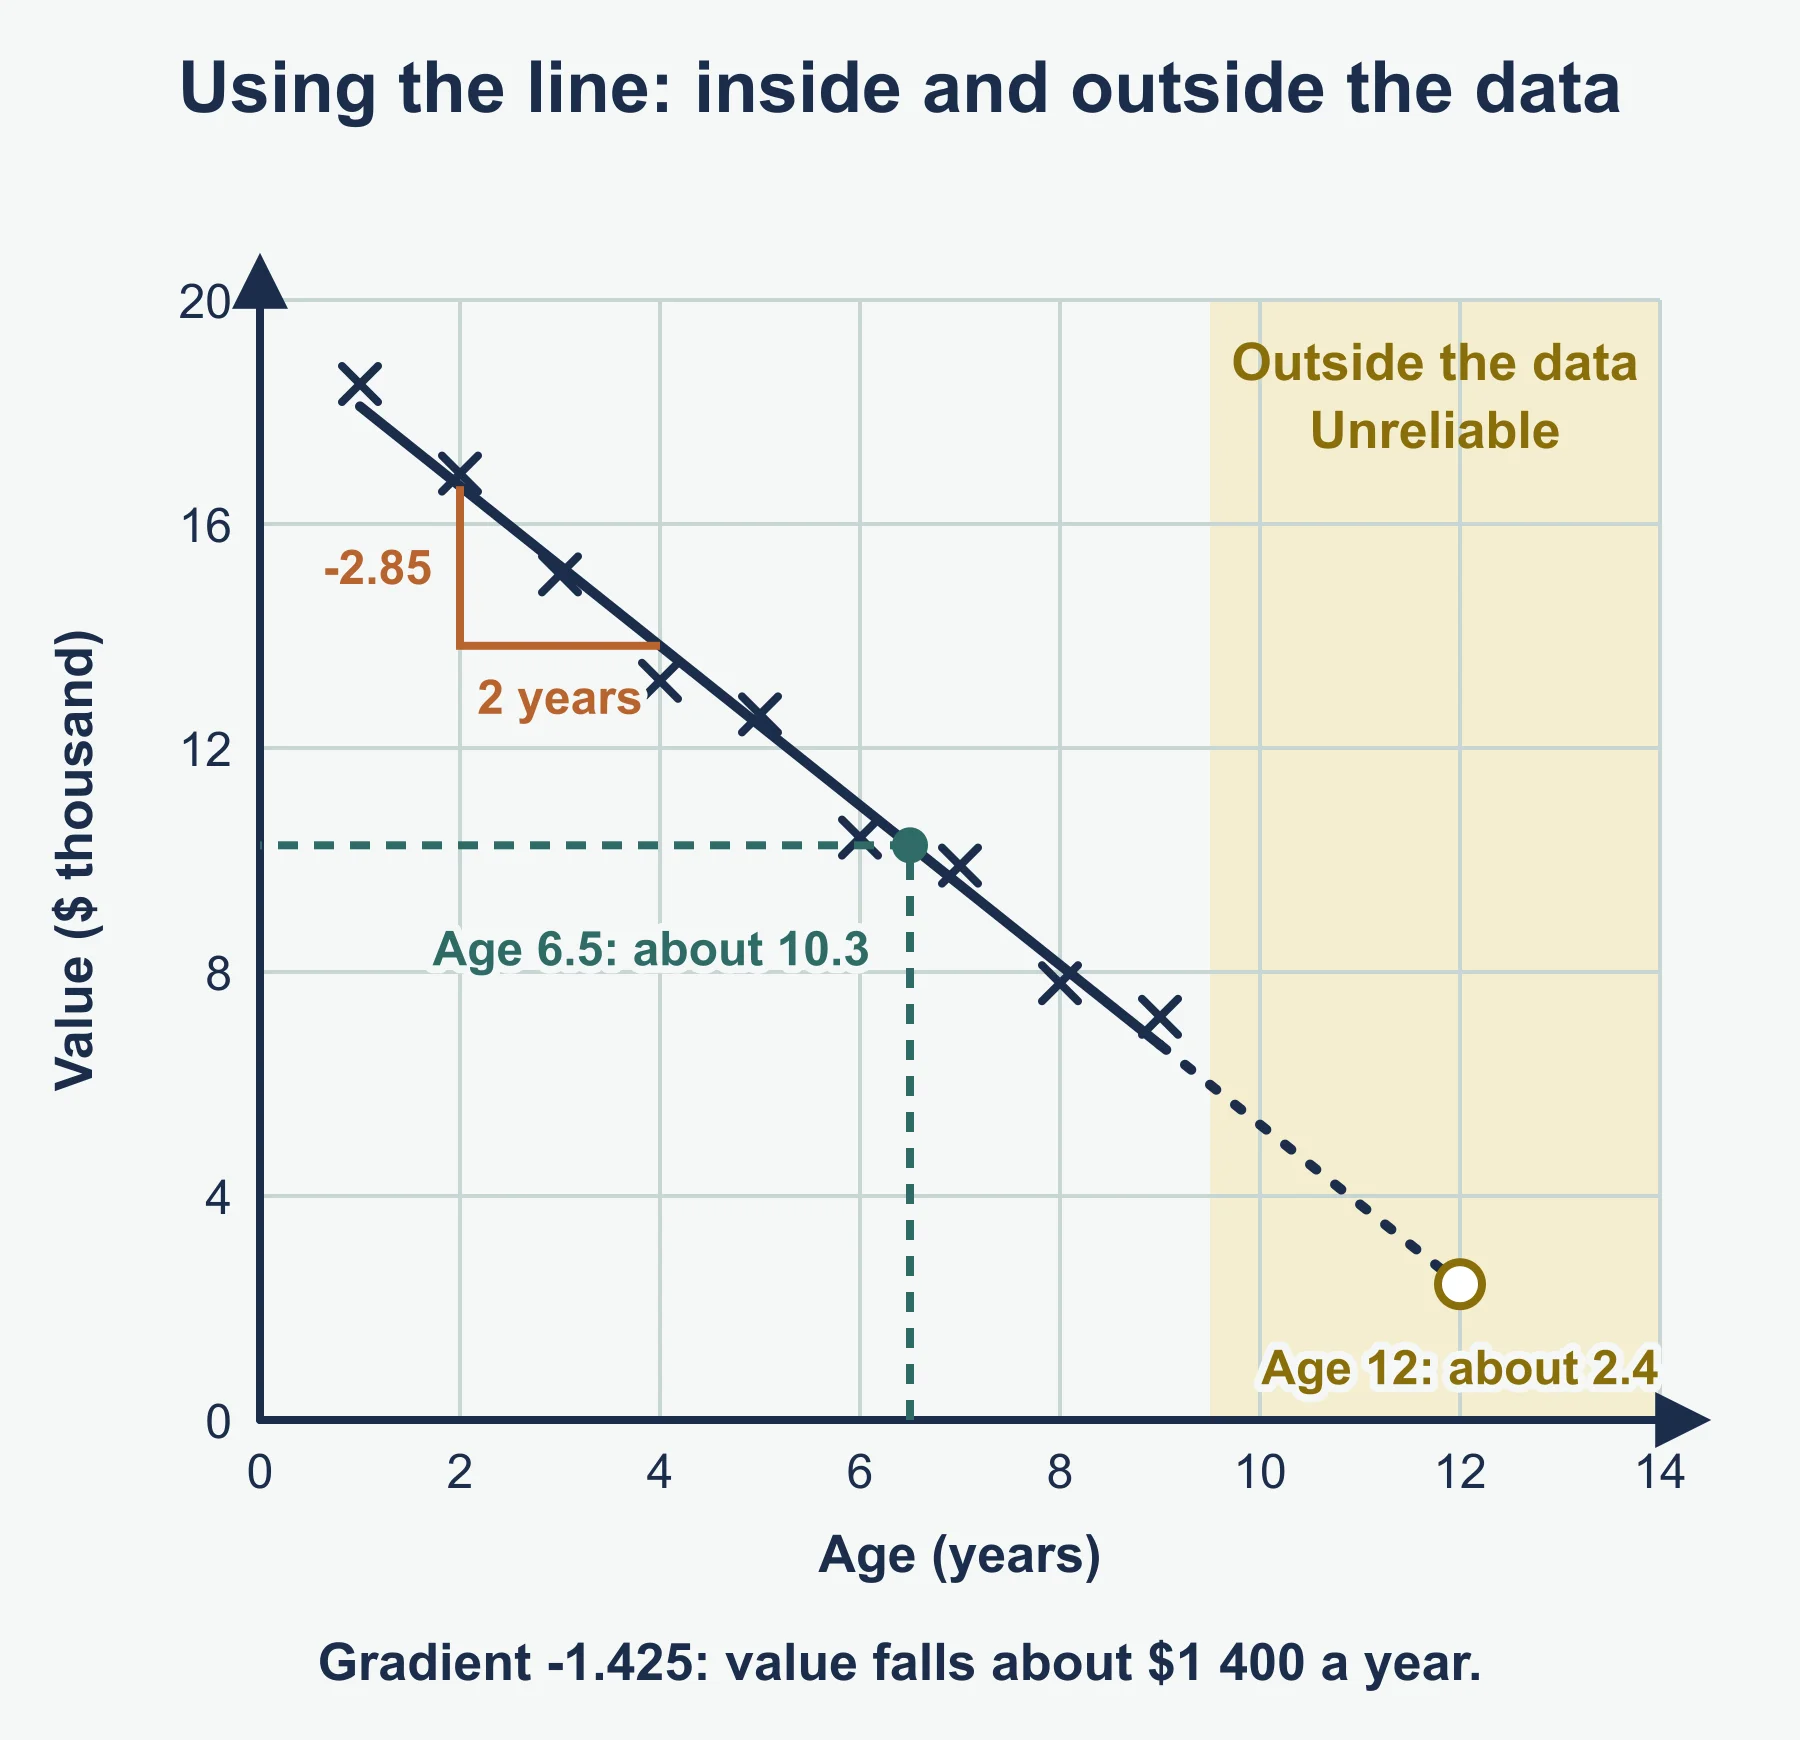
- Using the line to estimate within the range of the data (e.g. 6.5 hours) is interpolation and is fairly reliable.
- Using it outside the data (e.g. 20 hours) is extrapolation. The trend may not continue: a line through the mean point that fits these data predicts about 130 marks at 20 hours, which is impossible.
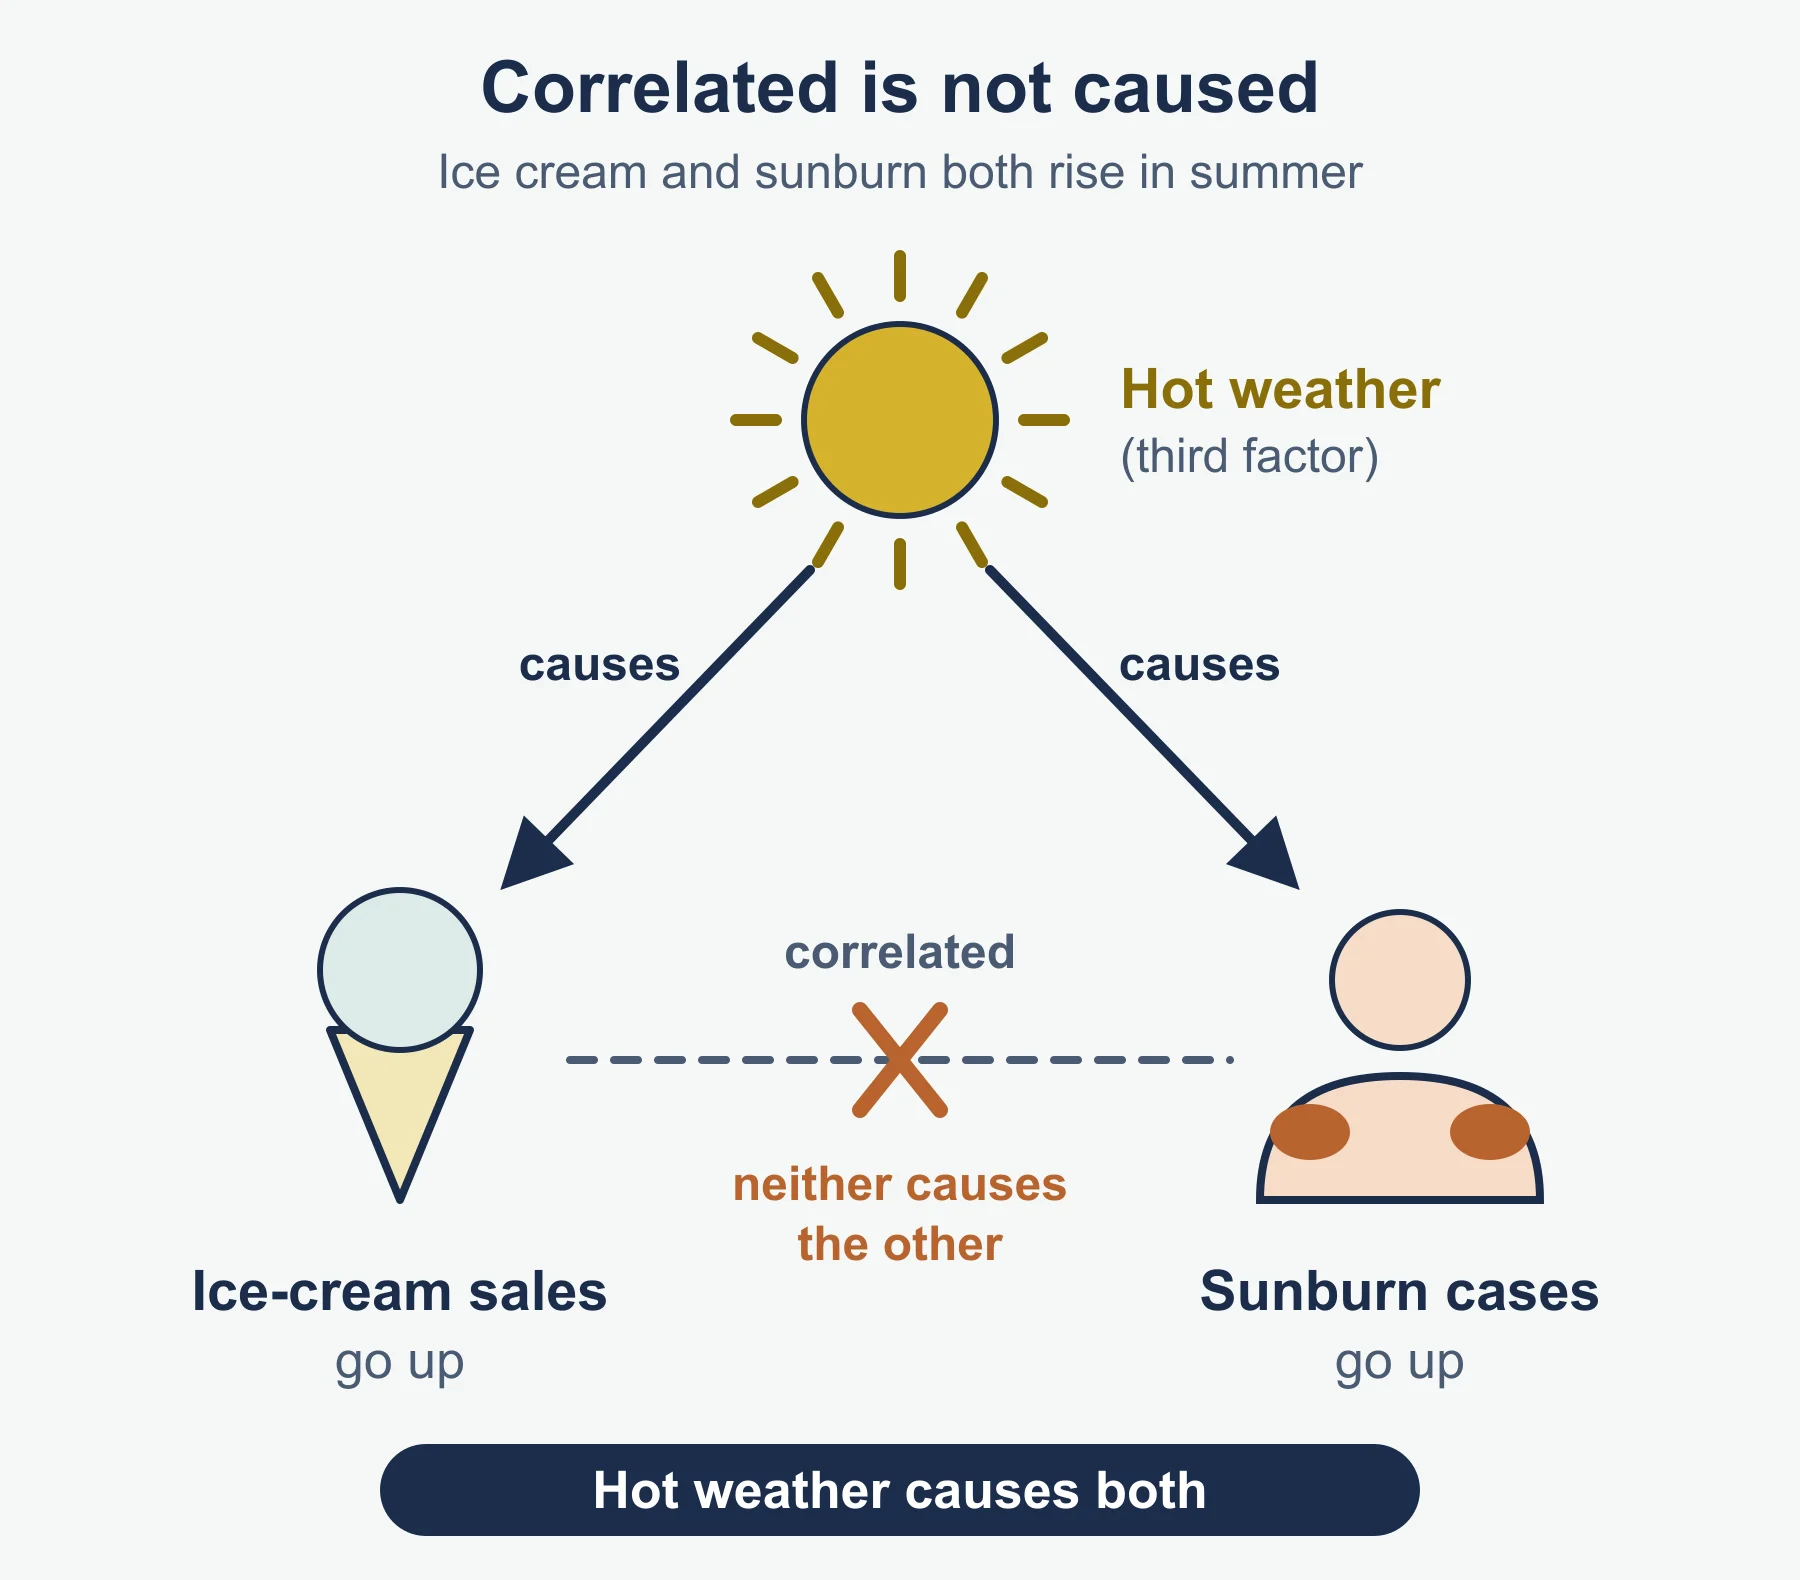
Correlation does not show causation. Ice-cream sales and sunburn cases both rise in summer. They are correlated because of a third factor, hot weather. Neither causes the other.
An outlier on a scatter graph is a point far from the pattern. Ignore it when drawing the line.
Common errors
- Drawing bar charts for continuous data with gaps, or histograms with frequency (not frequency density) on the vertical axis for unequal classes.
- Dividing Σ(midpoint × frequency) by the number of classes instead of the total frequency.
- Using the class width or upper boundary instead of the midpoint for an estimated mean.
- Plotting cumulative frequency at midpoints instead of upper class boundaries.
- Comparing only averages, or giving comparisons with no context.
- Saying one variable “causes” the other because the correlation is strong.
Frequently asked questions
What is the difference between discrete and continuous data? Discrete data can only take separate values, usually counts such as the number of siblings. Continuous data is measured and can take any value in a range, such as height, time or mass.
What is the difference between primary and secondary data? Primary data is collected by you, for example through your own survey. Secondary data was collected by someone else, such as figures from a website or published table.
Does correlation mean one thing causes another? No. Correlation shows that two variables are related, but a third factor may link them. For example, ice-cream sales and sunburn cases both rise in summer.
What topics are in AQA GCSE Maths Topic 6 Statistics? Topic 6 Statistics (S1 to S6) in AQA GCSE Mathematics 8300 covers sampling, charts and diagrams, histograms and cumulative frequency, averages and spread, using samples to describe populations, and scatter graphs.
Next steps
Condense this into the revision notes, then test yourself with the practice questions. The Probability study guide covers the other half of this area of the course.
Official syllabus
AQA GCSE Mathematics (8300) specification, for teaching from September 2015, exams from May/June 2017, version 1.0, published by AQA – section 3.6 Statistics (S1 to S6).
Get free revision emails (optional)
Occasional emails with practice questions, worked explanations and links to free resources for the qualification and subjects you choose. No spam, and you can unsubscribe from any email. The free tools on this site never need an email.
Related resources
-
Practice questions
AQA GCSE Mathematics 8300: Statistics – Practice Questions
Twelve original AQA GCSE Maths 8300 Statistics questions on sampling, averages, pie charts, histograms, box plots and scatter graphs, with marked answers.
Mathematics · AQA · GCSE
Try questions -
Revision notes
AQA GCSE Mathematics 8300: Statistics – Revision Notes
Condensed AQA GCSE Maths 8300 Statistics revision notes: averages, charts, histograms, box plots and scatter graphs, with a self-test and answers.
Mathematics · AQA · GCSE
Revise topic -
Study guides
AQA GCSE Mathematics 8300: Structure and calculation – Study Guide
Study guide for AQA GCSE Maths 8300 section 3.1.1 (N1-N9): ordering, the four operations, primes, listing, indices, surds and standard form.
Mathematics · AQA · GCSE
Read guide
Related articles
-
exam preparation
Where IGCSE Mathematics marks are lost early
The first weeks of an IGCSE Mathematics course rarely go wrong on difficulty. They go wrong on method, command words, rounding and units — four habits that cost marks a student had already earned.
24 August 2026
-
teaching
A Level tuition in Dubai: Cambridge or Pearson Edexcel International A Level?
Schools in Dubai and Abu Dhabi teach either Cambridge International AS & A Level or Pearson Edexcel International A Level. How the two are structured, why it matters for tuition, and how online classes from Lahore work.
9 October 2026
Studying this with a teacher
Working through Mathematics GCSE?
This page is free and stays free. If you would rather be taught it, Marlbridge runs Mathematics classes one-to-one and in small groups of up to 15, online in your own time zone. The first trial class is free. WhatsApp replies within an hour (8am–11pm Pakistan time, every day); email the same day.
AQA Mathematics teachers at Marlbridge

